Structure-aware Reinforcement Learning Algorithms for Generative Models Post Training
Hanyang Zhao
· Columbia Academic Commons (C... · 0 citations
Category
2,544 papers
This work proposes a revised axiomatic foundation for narrative realism by treating human drama as a reality‑activating operator acting on fictional settings. The paper demonstrates that readers’ perception of realism in fiction is determined not by the ontological plausibility of the setting but by the existential urg...
Competitive interaction among autonomous sub-agents in a complex adaptive system generates a structural dilemma: unconstrained rivalry accelerates innovation while simultaneously producing destructive entropy, whereas forced equilibrium removes destructive friction at the price of evolutionary stagnation. The present w...
Reach audiences
Advertise in front of researchers, engineers, and readers.
The present research introduces WushuDRL-Net, an intelligent framework based on deep reinforcement learning (DRL) to enhance Wushu movement learning and training. The system employs the Proximal Policy Optimization with Motion Alignment Feedback (PPO-MAF) technique, which combines expert imitation, rhythm alignment, an...
ArchiveGene–UzMorphSim MultiDomain v1.1 is a multi-domain Uzbek research dataset developed for semantic similarity, adaptive model routing, document understanding, layout-aware processing, and document-orientation analysis. The resource comprises a primary corpus of 2,000 text documents for semantic-similarity experime...
Power grid fault diagnosis and prediction represent critical challenges in modern electrical infrastructure management, requiring rapid, accurate, and scalable decision-making under complex, dynamic conditions. This paper proposes a novel framework integrating MARL with MFG theory to address the inherent scalability li...
simulation code of BRL model and operational algorithum of S1
ArchiveGene–UzMorphSim MultiDomain v1.1 is a multi-domain Uzbek research dataset developed for semantic similarity, adaptive model routing, document understanding, layout-aware processing, and document-orientation analysis. The resource comprises a primary corpus of 2,000 text documents for semantic-similarity experime...
Destructive earthquakes are natural hazards highlighting the importance of introducing disaster preparedness from early childhood. Preschool children require developmentally appropriate educational approaches that connect scientific understanding with experiential, play-based, and participatory learning. This study pre...
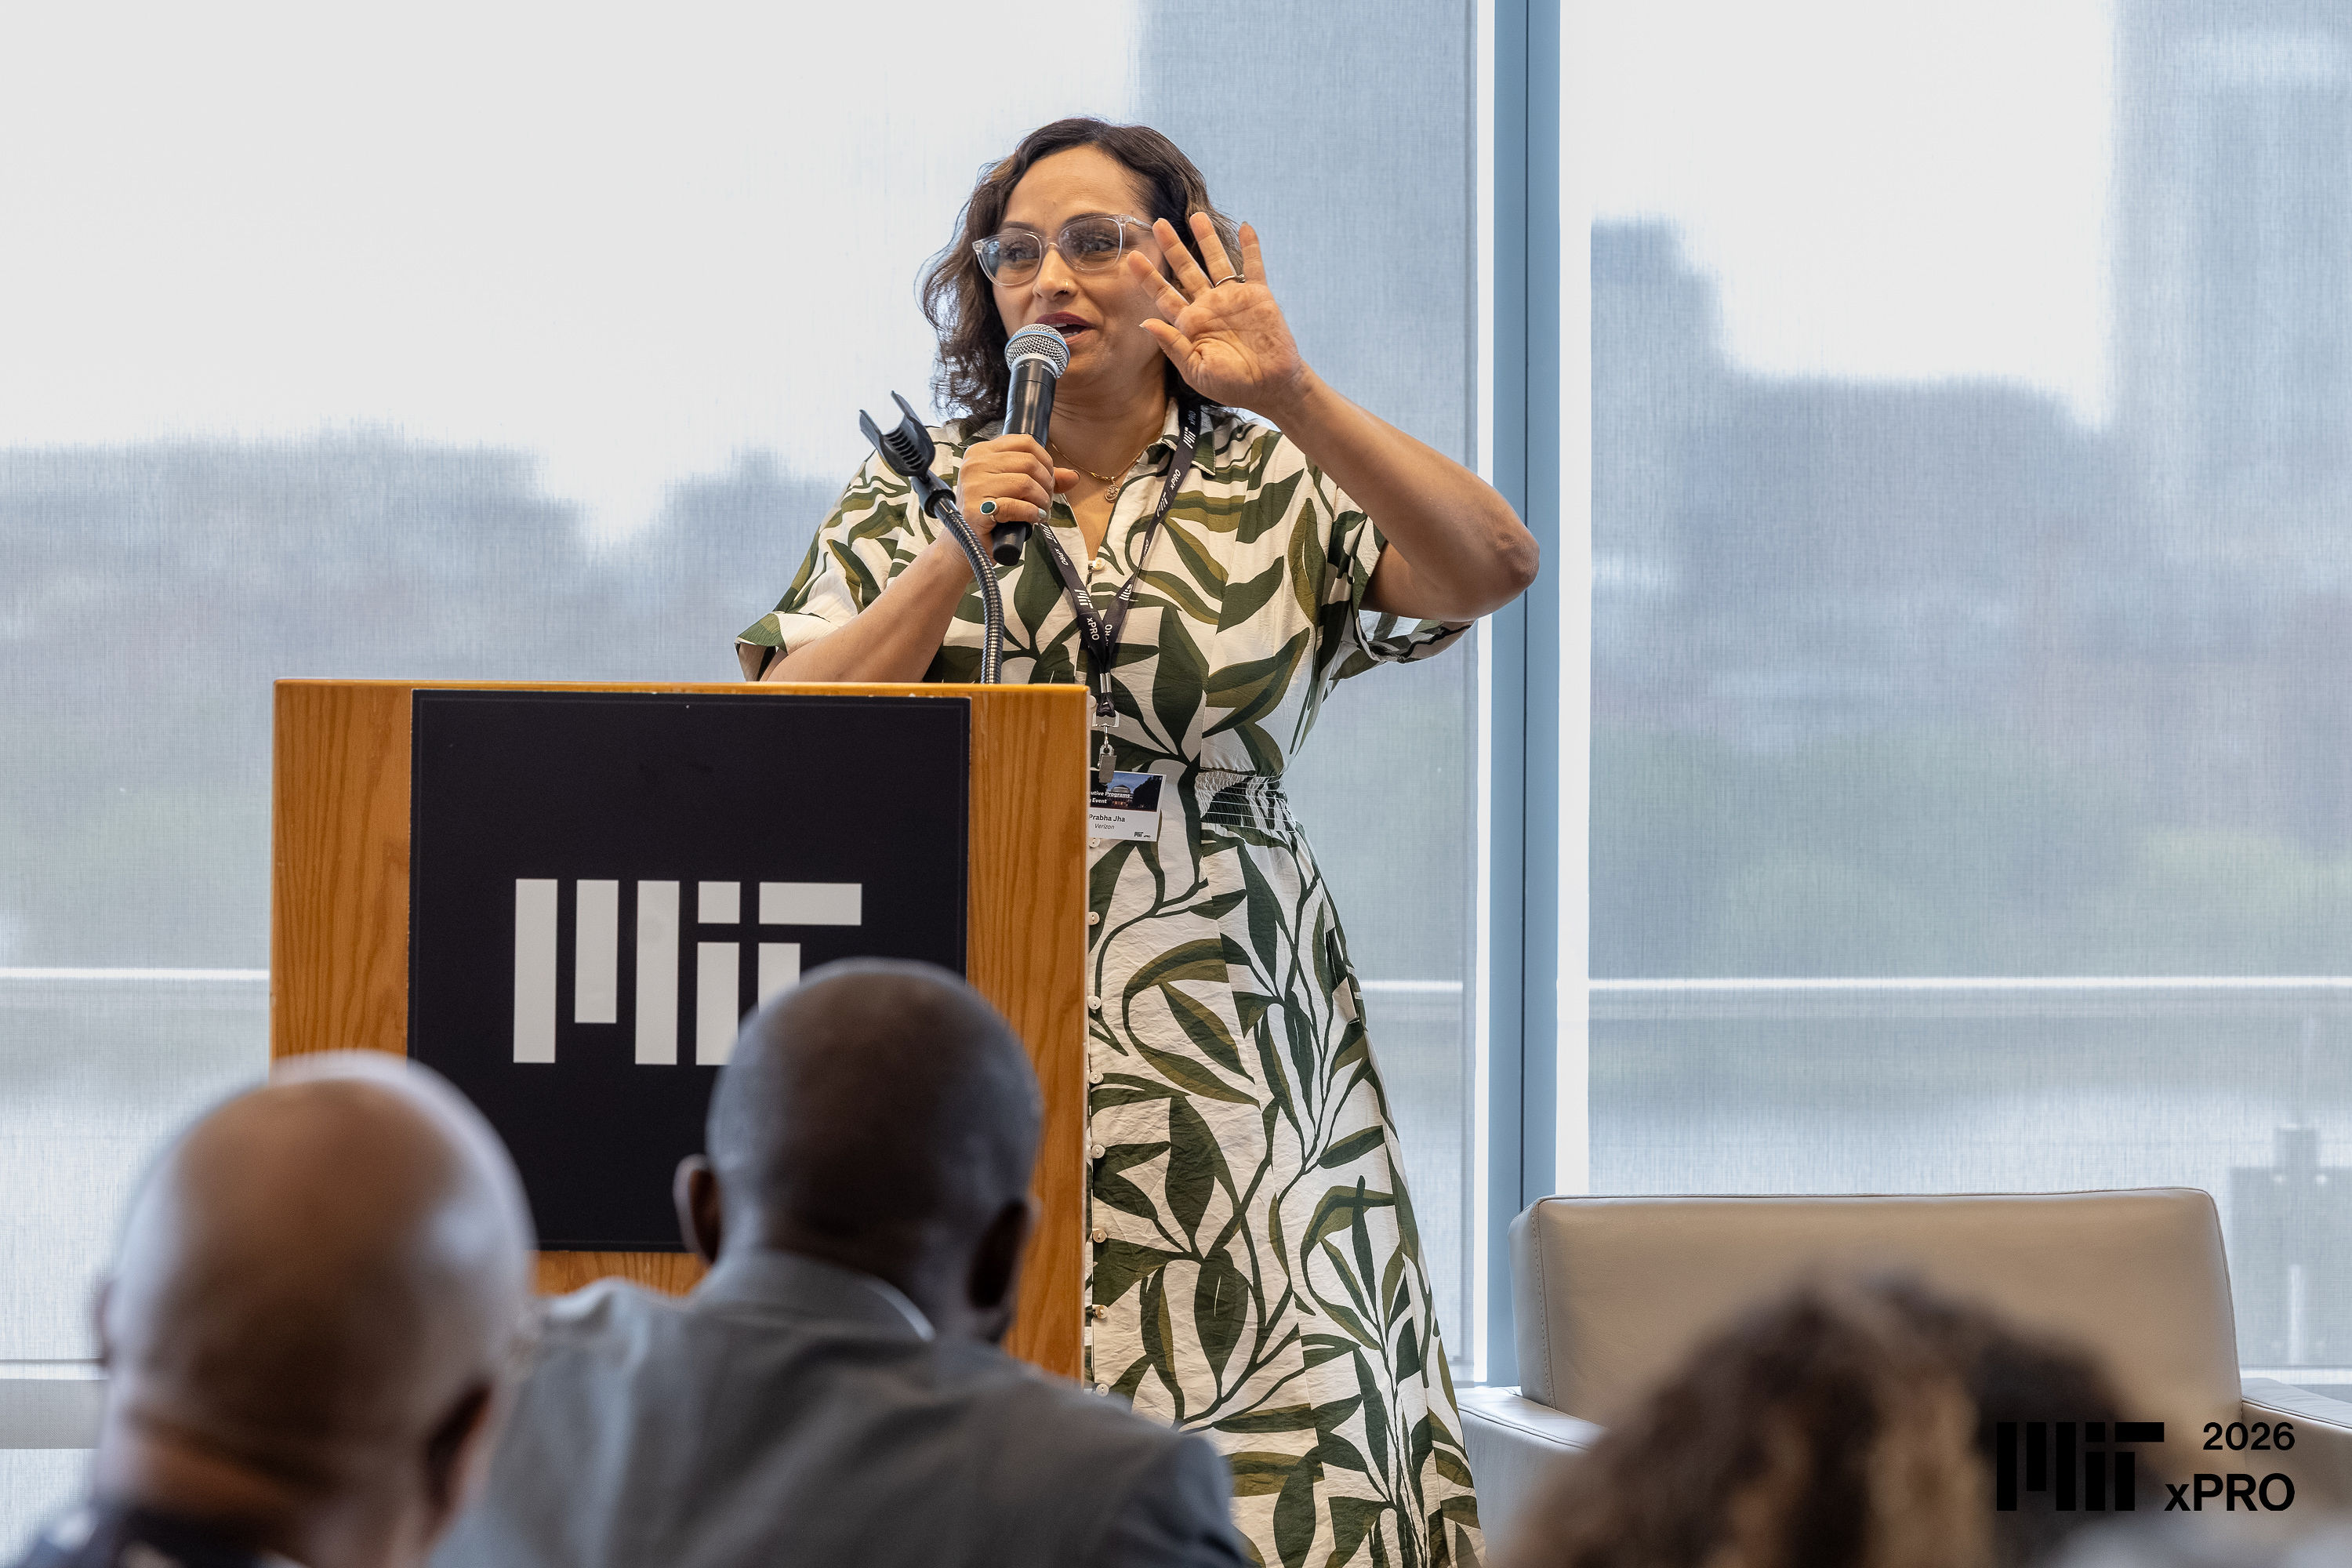
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Education Innovation
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
A Blog post by NVIDIA on Hugging Face
A Blog post by IBM Research on Hugging Face
A new machine-learning approach broke records for weather forecasting for an important time frame in emergency planning.
We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.