This chapter introduces play loops as a constructional framework for engaging learners and building instruction from interaction rather than control. A play loop is a mutually sustained, reciprocally reinforcing chain in which each participant’s action both signals the next response and reinforces the previous one. Rat...
Submerged membrane bioreactor (SMBR) systems offer high treatment efficiency and compact operation, but nonlinear dynamics and time-varying membrane fouling make constant-flux regulation challenging. This study develops and evaluates three reinforcement-learning controllers—a deep Q-network (DQN), deep deterministic po...
Yin Liu, Norhaliza Abdul Wahab· International Journal of Com...· 0 citations
In reinforcement learning, an agent learns to map representations of the environment state to predictions of future reward. Most prior work in neuroscience has assumed a fixed representation and studied how reward prediction errors (thought to be conveyed by phasic dopamine signals) are used to update the mapping from...
George Cai, Max Scheller, Wolfgang Kelsch et al.· eLife· 0 citations
In reinforcement learning, an agent learns to map representations of the environment state to predictions of future reward. Most prior work in neuroscience has assumed a fixed representation and studied how reward prediction errors (thought to be conveyed by phasic dopamine signals) are used to update the mapping from...
George Cai, Max Scheller, Wolfgang Kelsch et al.· 0 citations
In reinforcement learning, an agent learns to map representations of the environment state to predictions of future reward. Most prior work in neuroscience has assumed a fixed representation and studied how reward prediction errors (thought to be conveyed by phasic dopamine signals) are used to update the mapping from...
This study presents a vision-language conditioned agent for autonomous excavator operations in physics-based simulation. A semantic action-based instruction scheme is introduced, in which natural language instructions describe excavator action units with target specifications. The agent integrates a vision-language mod...
The Society 5.0 era marks a new chapter in human civilization, positioning Artificial Intelligence (AI)-based technology as a central instrument in social life, including within Islamic education. In this context, tahfizh Al-Qur'an learning a noble tradition of preserving divine revelation, faces a dual challenge: it m...
Rifka Haida Rahma, Supratman Zakir· Journal of Information Syste...· 0 citations
Blood cancer prognosis is still behind clinical need because current prediction algorithms fail to reflect how hematological malignancies grow, reorganize their molecular landscapes, and drift under therapy pressure. Static deep-learning pipelines that treat prognosis as a one-time classification task make existing alg...
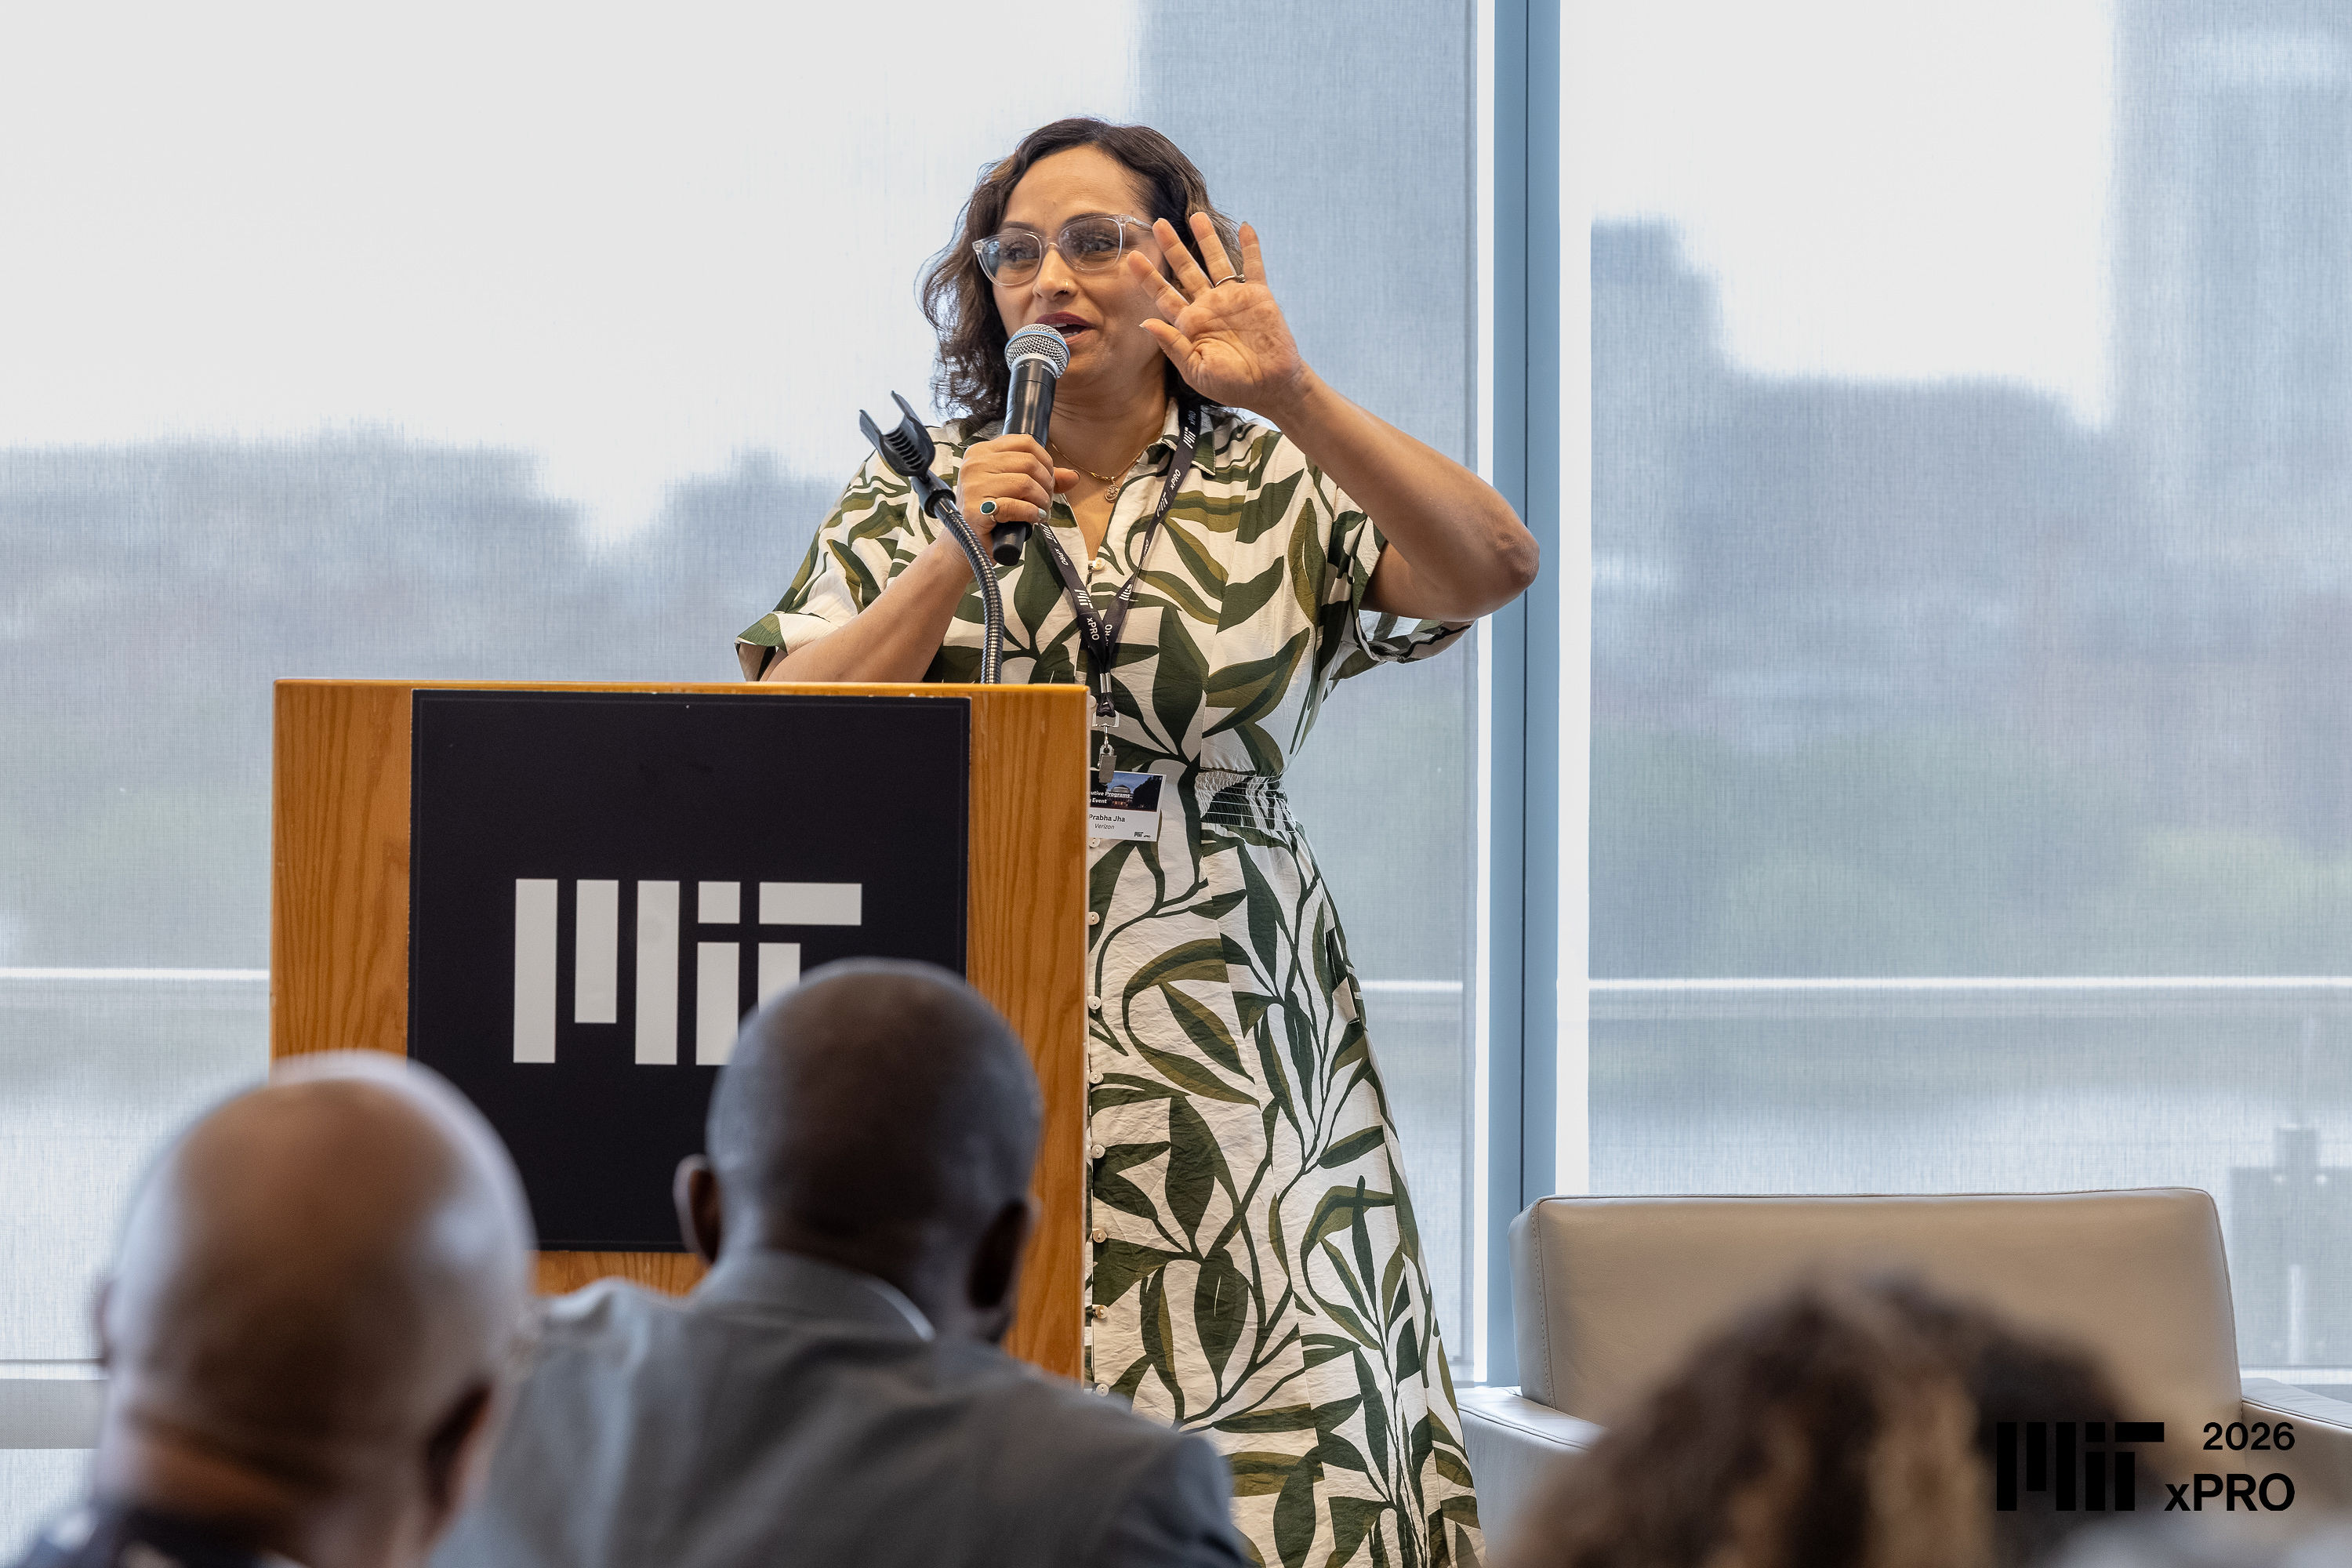
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.