Abstract. The Arctic Weather Satellite (AWS), launched by the European Space Agency (ESA) in August 2024, has enabled the first-ever global ice cloud remote sensing using 325 GHz terahertz channels. Owing to its short wavelength, the 325 GHz frequency band is highly sensitive to scattering by the three frozen hydromete...
IEEE 802.11ax Target Wake Time (TWT) coordinates station sleep and wake schedules for power savings, while RF energy harvesting promises battery-free operation for IoT sensors. Though studied in isolation, the two are coupled; the same access point (AP) that schedules TWT service periods, controls the RF harvest of bat...
A. Maksud, Marcelo M. Carvalho· Proceedings of the 21st Work...· 0 citations
Homeschooling requires learning that is flexible and responsive to differences in learners’ readiness, interests, and needs. This study aimed to describe the implementation of content- and process-differentiated blended learning at Homeschooling Candrawinata Bandung, including its planning, implementation, evaluation,...
Lismawati Lismawati, Sri Handayani· LEARNING Jurnal Inovasi Pene...· 0 citations
NeatRL is a reinforcement learning library built around single-file, self-contained implementations of classic and modern deep RL algorithms: DQN, A2C, PPO, DDPG, TD3, SAC and more, with Gymnasium and Atari support and Weights & Biases experiment tracking. NeatRL source code is licensed under the MIT License.
Yuvraj Singh· Zenodo (CERN European Organi...· 0 citations
Decision models answer typed questions with probabilities instead of text, and their main selling point is that those probabilities can be trusted. TypeSafe says its Jev model, trained with an unpublished method called Reinforcement Learning for Calibrated Decisions (RLCD), returns "epistemically honest" probabilities....
Mohit Shankar Velu· Zenodo (CERN European Organi...· 0 citations
Beyond Heuristics is a 3-page research journal on how Artificial Intelligence is changing logic gate synthesis in Electronic Design Automation (EDA). Modern chips contain billions of gates, and traditional rule-based synthesis struggles to balance power, performance, and area. The journal reviews three AI approaches to...
Jommel John Sinsuan· Zenodo (CERN European Organi...· 0 citations
Building on recent insights that augmenting reinforcement‐learning policies with disturbance estimates improves robustness and sim-to-real transfer, this paper proposes a disturbance-aware actor–critic RL framework for high‐precision robotic manipulators. We derive the dynamics of manipulators ranging from two to six d...
V. Nguyen, Thi Thanh Tam Le, D. Pham et al.· PLoS ONE· 0 citations
Fast charging of lithium-ion battery (LIB) packs is constrained by thermal runaway risk, cell state-of-charge (SOC) imbalance, and accelerated capacity fade, challenges compounded by spatial temperature gradients and the diversity of cathode chemistries and configurations across electric vehicles and stationary storage...
Saumya Karan, P. Bharadwaj· Applied Energy· 0 citations
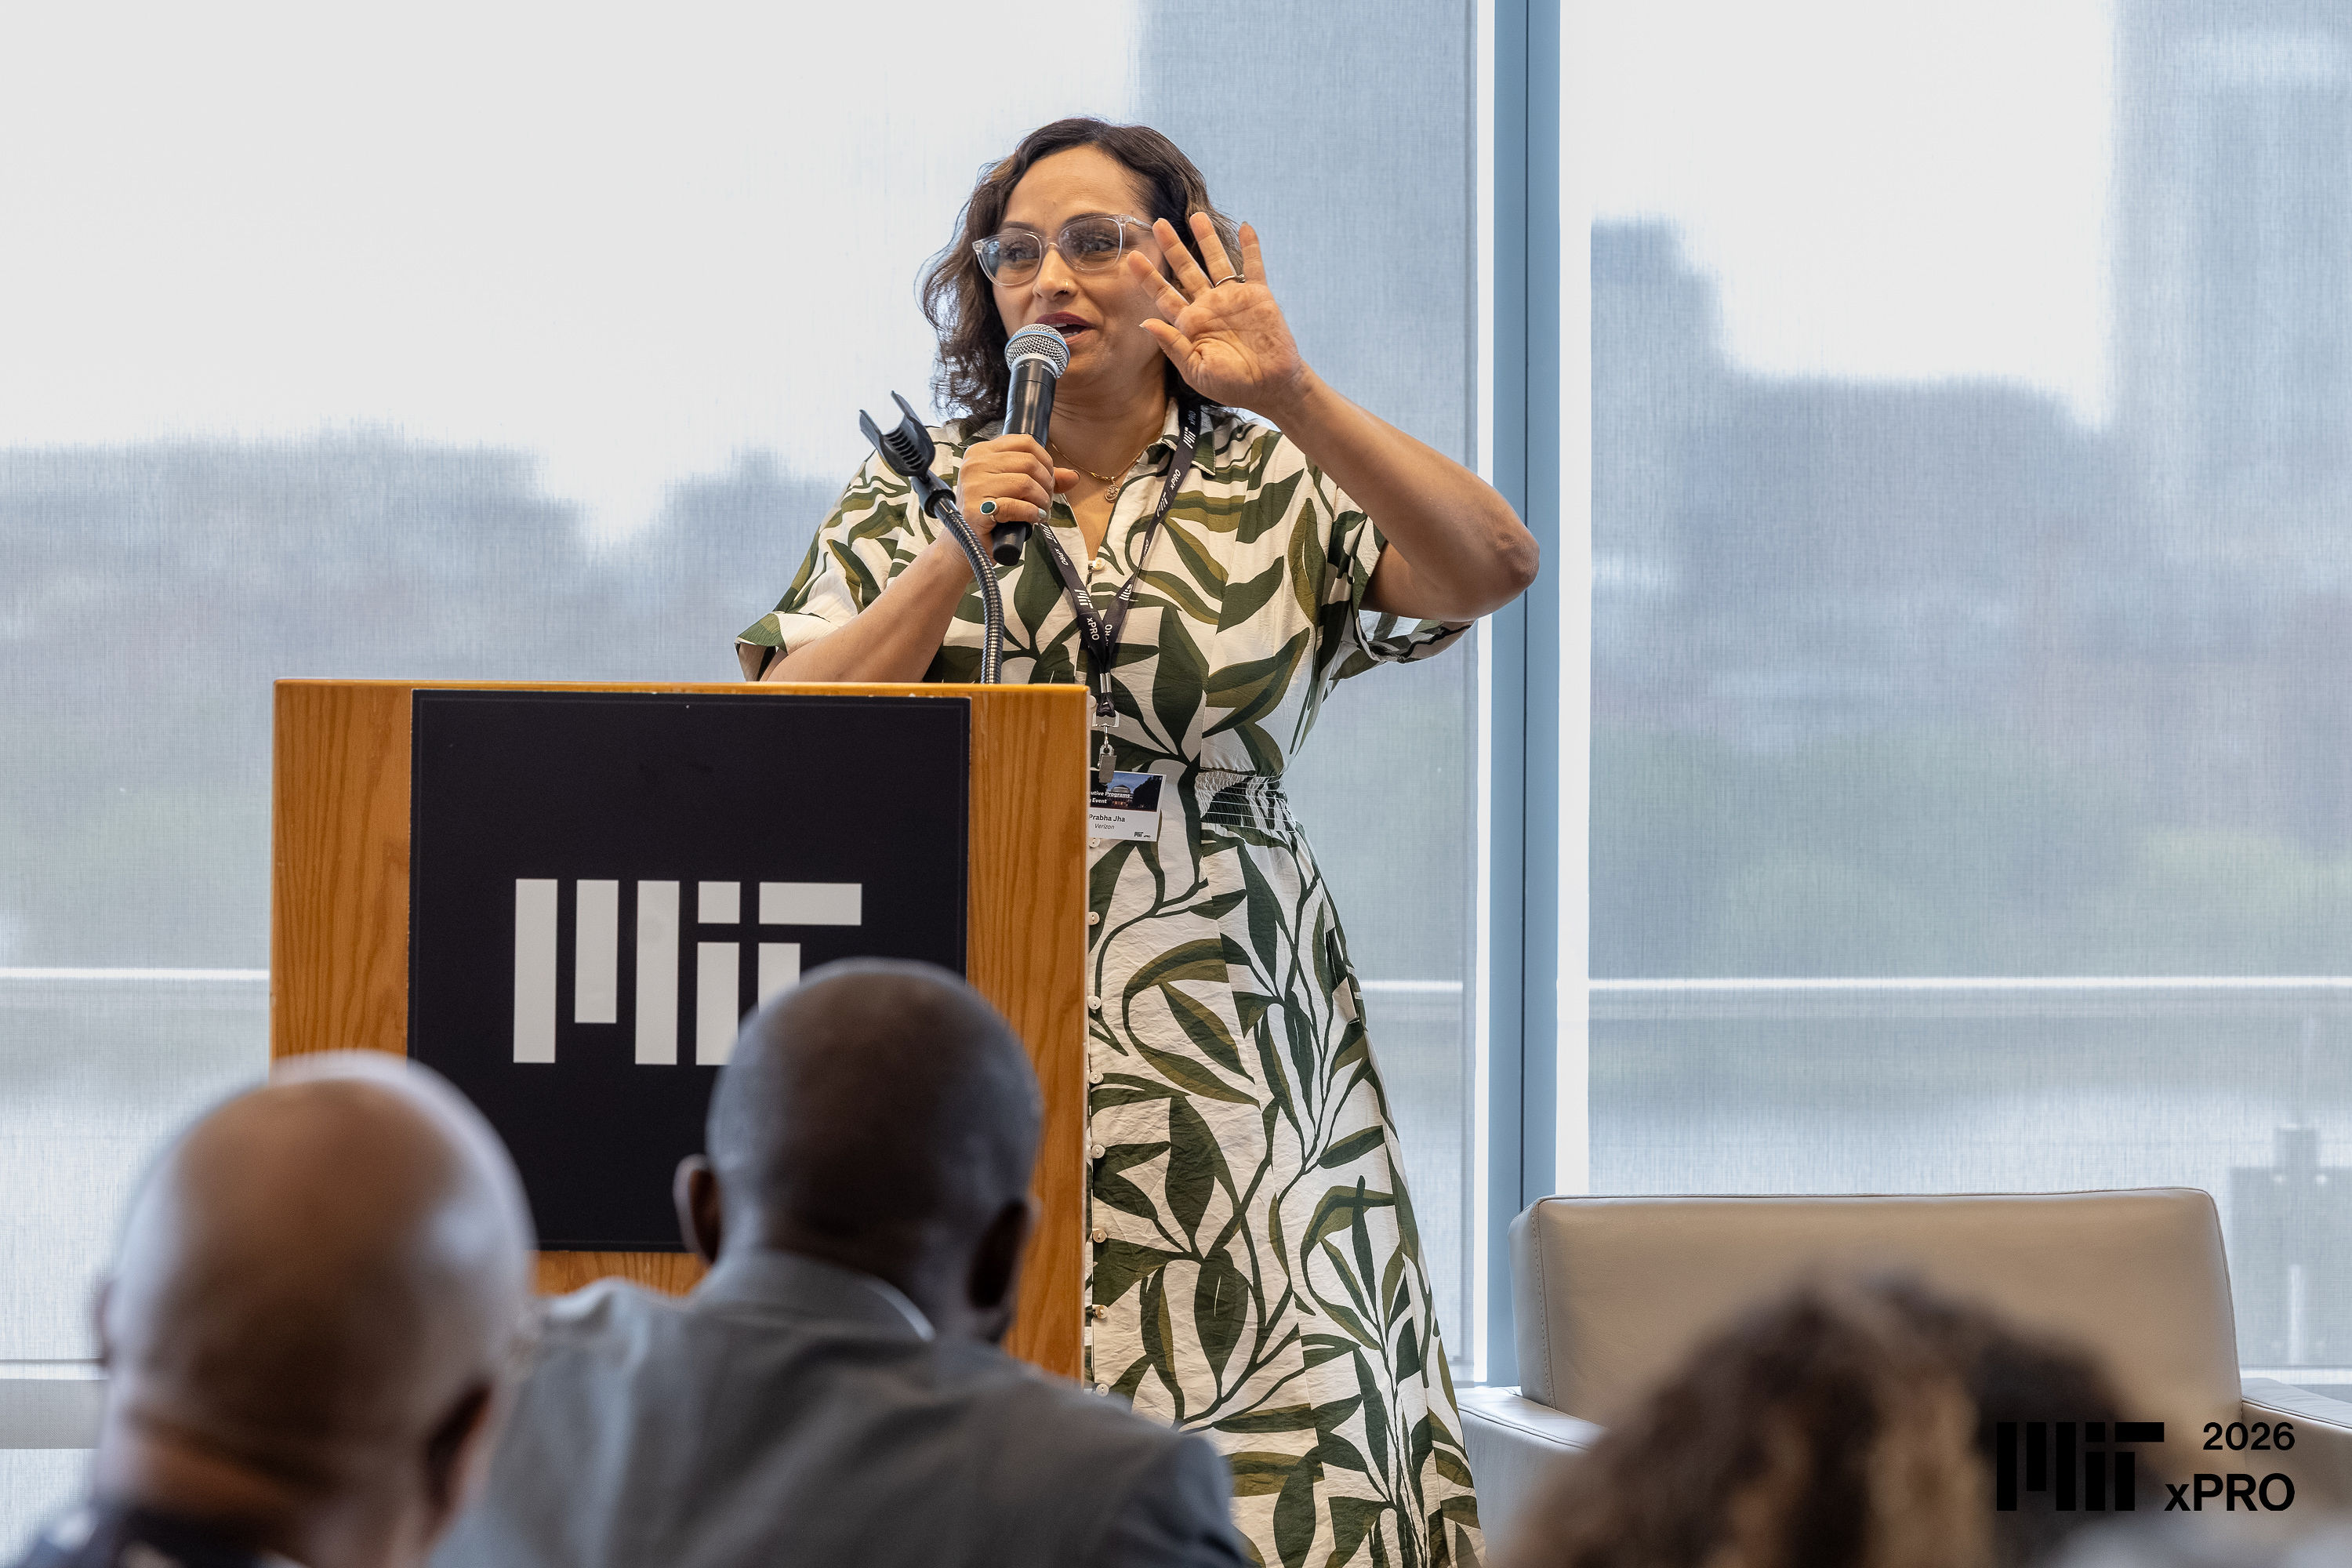
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.