Managed Pressure Drilling (MPD) increasingly relies on automated choke control software to safely manage narrow pressure windows. Verifying the performance, robustness, and stability of these control systems across diverse operational scenarios is vital to ensure well integrity. Flow-loop testing confirms hardware in...
T. El-Agroudi, G. Kaasa, J. Thain· IADC/SPE Managed Pressure Dr...· 0 citations
A runtime for agentic software testing in which a language model proposes tool calls but decides nothing. Every proposed call is classified against a manifest and resolved by an operator-owned policy table into execute, ask, or refuse; an unclassified operation is refused by default. Completion is decided by code that...
Vijay Prasad Javvadi· Zenodo (CERN European Organi...· 0 citations
Files and variables File: Data.zip Description: This directory contains the aggregated tabular information from scoring eSTZ data products, as well as a handful of other files used in post-processing datasets. File: scripts.zip Description: Scripts for creating figures used in this manuscript and in an earlier poster....
Reed Clark Benkendorf· Zenodo (CERN European Organi...· 0 citations
Files and variables File: Data.zip Description: This directory contains the aggregated tabular information from scoring eSTZ data products, as well as a handful of other files used in post-processing datasets. File: scripts.zip Description: Scripts for creating figures used in this manuscript and in an earlier poster....
Reed Clark Benkendorf· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
A runtime for agentic software testing in which a language model proposes tool calls but decides nothing. Every proposed call is classified against a manifest and resolved by an operator-owned policy table into execute, ask, or refuse; an unclassified operation is refused by default. Completion is decided by code that...
Vijay Prasad Javvadi· Zenodo (CERN European Organi...· 0 citations
Accelerometer-derived measures from wrist, thigh, and hip locations are strongly correlated and provide evidence to support pooled meta-analyses across wear locations and the development of location-agnostic processing software.
C. Zisou, B. Maylor, A. Acquah et al.· International Journal of Beh...· 0 citations
Abstract: We report the migration of AkbasCore's inference-time, multi-axis activation-steering kernel from a host-side C++ implementation to a GPU-native CUDA kernel, and the first capability-preservation benchmark of this method against real-world evaluation data. The steering framework combines a critically-damped,...
ceceli33· Zenodo (CERN European Organi...· 0 citations
Abstract Artificial intelligence and other advanced technologies are entering health research faster than the systems that oversee it can adapt. Two reform movements respond. A global movement runs through the World Health Organization’s action plan for clinical trial ecosystem strengthening and its good reliance pract...
Francis P. Crawley, Anton Rahardjo, Rita S. Sitorus et al.· Zenodo (CERN European Organi...· 0 citations
PatchRisk is constructed, a leakage-aware benchmark from Open Source Vulnerability advisories and deps.dev dependency graphs for npm and PyPI that improves AUPRC over the strongest TimeOnly baseline and remains stable across smaller scales and package-group shuffle robustness tests.
Ashfaq Ali Shafin, Khandaker Mamun Ahmed· 0 citations
Human evaluation provides a direct measure of the quality of LLM-generated web applications. However, fitting human judgments through automated evaluation remains challenging. Static benchmarks can credit functionality that exists in source code but is unreachable at runtime. Interactive benchmarks exercise the applica...
Chen-Xu Liu, Zi-Lu Zou, Pei-Zhong Gao et al.· 0 citations
Recent investigations of the July 2026 OpenAI--Hugging Face incident motivate two questions about agent behavior under task failure: when an assigned task becomes impossible, does an agent stop or escalate, and can observing another agent's behavior change that decision? We study these questions using seven ImpossibleB...
Recently, interdigitated electrodes (IDEs) have been applied in various industries because they are easy to fabricate and low-cost. However, the optimal electrode geometry for maximizing sensitivity remains unclear, as conflicting reports exist on the effects of finger width, spacing, and thickness under varying operat...
S. A. Abdul Hamid, Mohd Asyraf Mohd Razib, Marmeezee Mohd Yusoff· International Islamic Univer...· 0 citations
Is your company’s AI sovereign? A practical guide for CIOs on AI vendor lock-in, EU Data Act switching, cloud sovereignty, and testing your exit plan before you need it. The post Sovereignty Is the Option to Leave appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
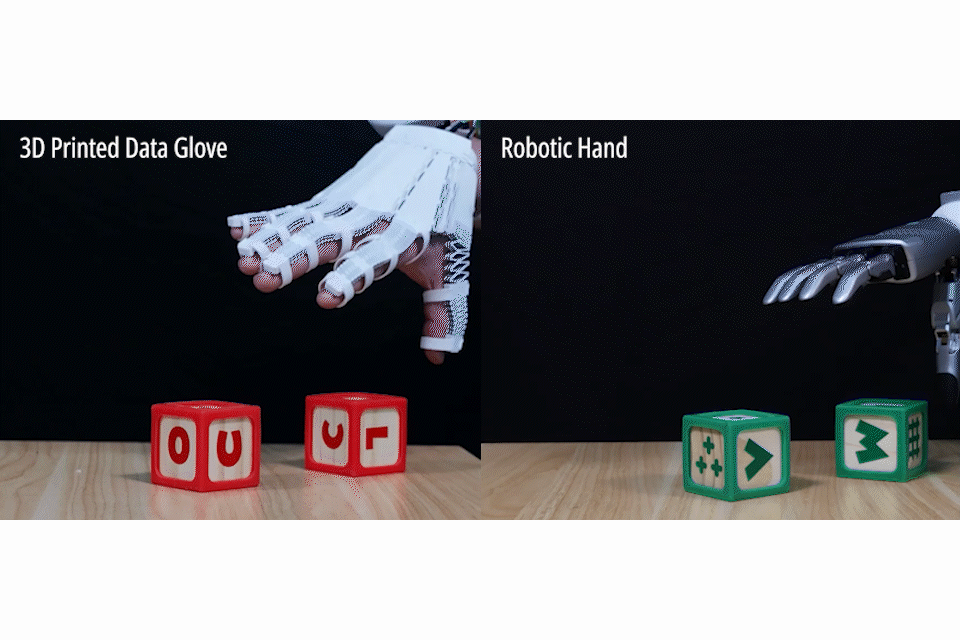
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.