Skip to content

Part Grounding, Not Action Knowledge: Locating the Bottleneck in VLM Affordance Prediction

Sep 2026 · 0 citations · 5 references
Computer Science

TL;DR

Part grounding is pointed to as the dominant bottleneck, a pattern that holds across all three model families and does not diminish with capability, so this bounds what a perfect part detector would offer rather than demonstrating a general model of mechanics.

Abstract

Benchmarks agree that vision-language models reason poorly about low-level manipulation, but an aggregate accuracy score does not say which step fails. We separate two steps that affordance questions conflate: identifying which part of an object to act on, and knowing what action that part requires. Across 19 articulated objects we asked eight models, spanning three developers, what motion a robot should apply. Under an open prompt, push was produced once in 64 evaluations where it was correct, despite being correct for 8 of 19 objects and appearing in the offered label set every time. Inspecting the outputs showed why: models described a different part than the one being scored, e.g. explaining how to pick up a camera rather than press its button. Naming the target part raises action accuracy by 0.32 to 0.63 for every model, from 0.158-0.474 to 0.684-0.947, and push recall from 0-1/8 to 7-8/8. No model beats a constant answer that ignores the image under the open prompt; once the part is named, all eight do. Asked to describe the same part in free prose with no label set, models produce pressing language for 6 to 8 of 8. These results are hard to reconcile with missing action knowledge, and instead point to part grounding as the dominant bottleneck, a pattern that holds across all three model families and does not diminish with capability. Naming the part supplies the grounding variable, so this bounds what a perfect part detector would offer rather than demonstrating a general model of mechanics. Two supporting results agree: on real photographs only three of eight models localize grasp points better than a constant baseline, and on rendered objects none do. We also document two measurement errors of our own, a threshold that let a constant baseline score 0.929 and a labelling rule wrong on 4 of 19 objects, both caught only by testing our numbers against trivial alternatives.

View source

Similar papers

Preprint Oct 2026

Instance-anchored interaction evidence: Grounding robot plans in human pointing and handling

A robot that assists people must often act on what a person has shown rather than said: which of several identical cartons was pointed at, or which box was handled. The plan is executed from the final scene, whereas the evidence occurs earlier, possibly on objects that have since moved. We propose instance-anchored int...

Xin-Wei Xiao, Bo-Wen Yang, Wen-Jing Zhang et al. · 0 citations
#artificial intelligence Review Sep 2026

ActionLens: Diagnosing Spatial-Temporal Binding Failures in Vision-Language Models

This work introduces ActionLens, a diagnostic benchmark of 6,701 multiple-choice video questions spanning five targeted diagnostics: transition detection, actor-specific identification, concurrent action binding, directed interaction reasoning, and gaze detection, and diagnostic measurements of these distinct failure m...

Gueter Josmy Faure, Min-Hung Chen, Hao-Ping Wang et al. · 0 citations
#artificial intelligence Preprint Sep 2026

FailBench: How Reliable are VLMs at Judging Robot Task Success?

This work introduces FailBench, a benchmark for robot failure detection comprising 2,197 manipulation attempts across 14 public sources (12 real-world, 2 simulated), and shows that input-level intervention--spatially localizing and cropping outcome-relevant regions--improves the top detector by 2.4 percentage points wi...

Zaruhi Navasardyan, Tatul Danielyan, Hrant Davtyan · 0 citations
Preprint Sep 2026

RoboIRGBench: Benchmarking Implicit Referential Grounding in Vision-Language-Action Models

Vision-Language-Action (VLA) models have shown strong capabilities in robotic manipulation, yet existing benchmarks typically assume that task-relevant information is explicitly specified in the instruction. In practice, however, humans frequently refer to objects, quantities, and relations implicitly, requiring robots...

Aernaer Akelijiang, Jian-Nan Li, Zhi-Neng Chen et al. · 0 citations
#small language model Preprint Sep 2026

Refusals That Bend: Measuring and Predicting Task Malleability in Embodied VLM Planners

Everyday objects, whether placed by an adversary or introduced by ordinary rearrangement of the environment, are thus sufficient to overturn a refusal, and susceptibility to safety bypass is called a property of the task, which it is shown that it can be predicted before the target is ever queried.

Leon Lin, Mikhail Kuznetsov, Muslum Ozgur Ozmen et al. · 0 citations

Related blog posts

Microsoft Research Blog Aug 11, 2026

Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement

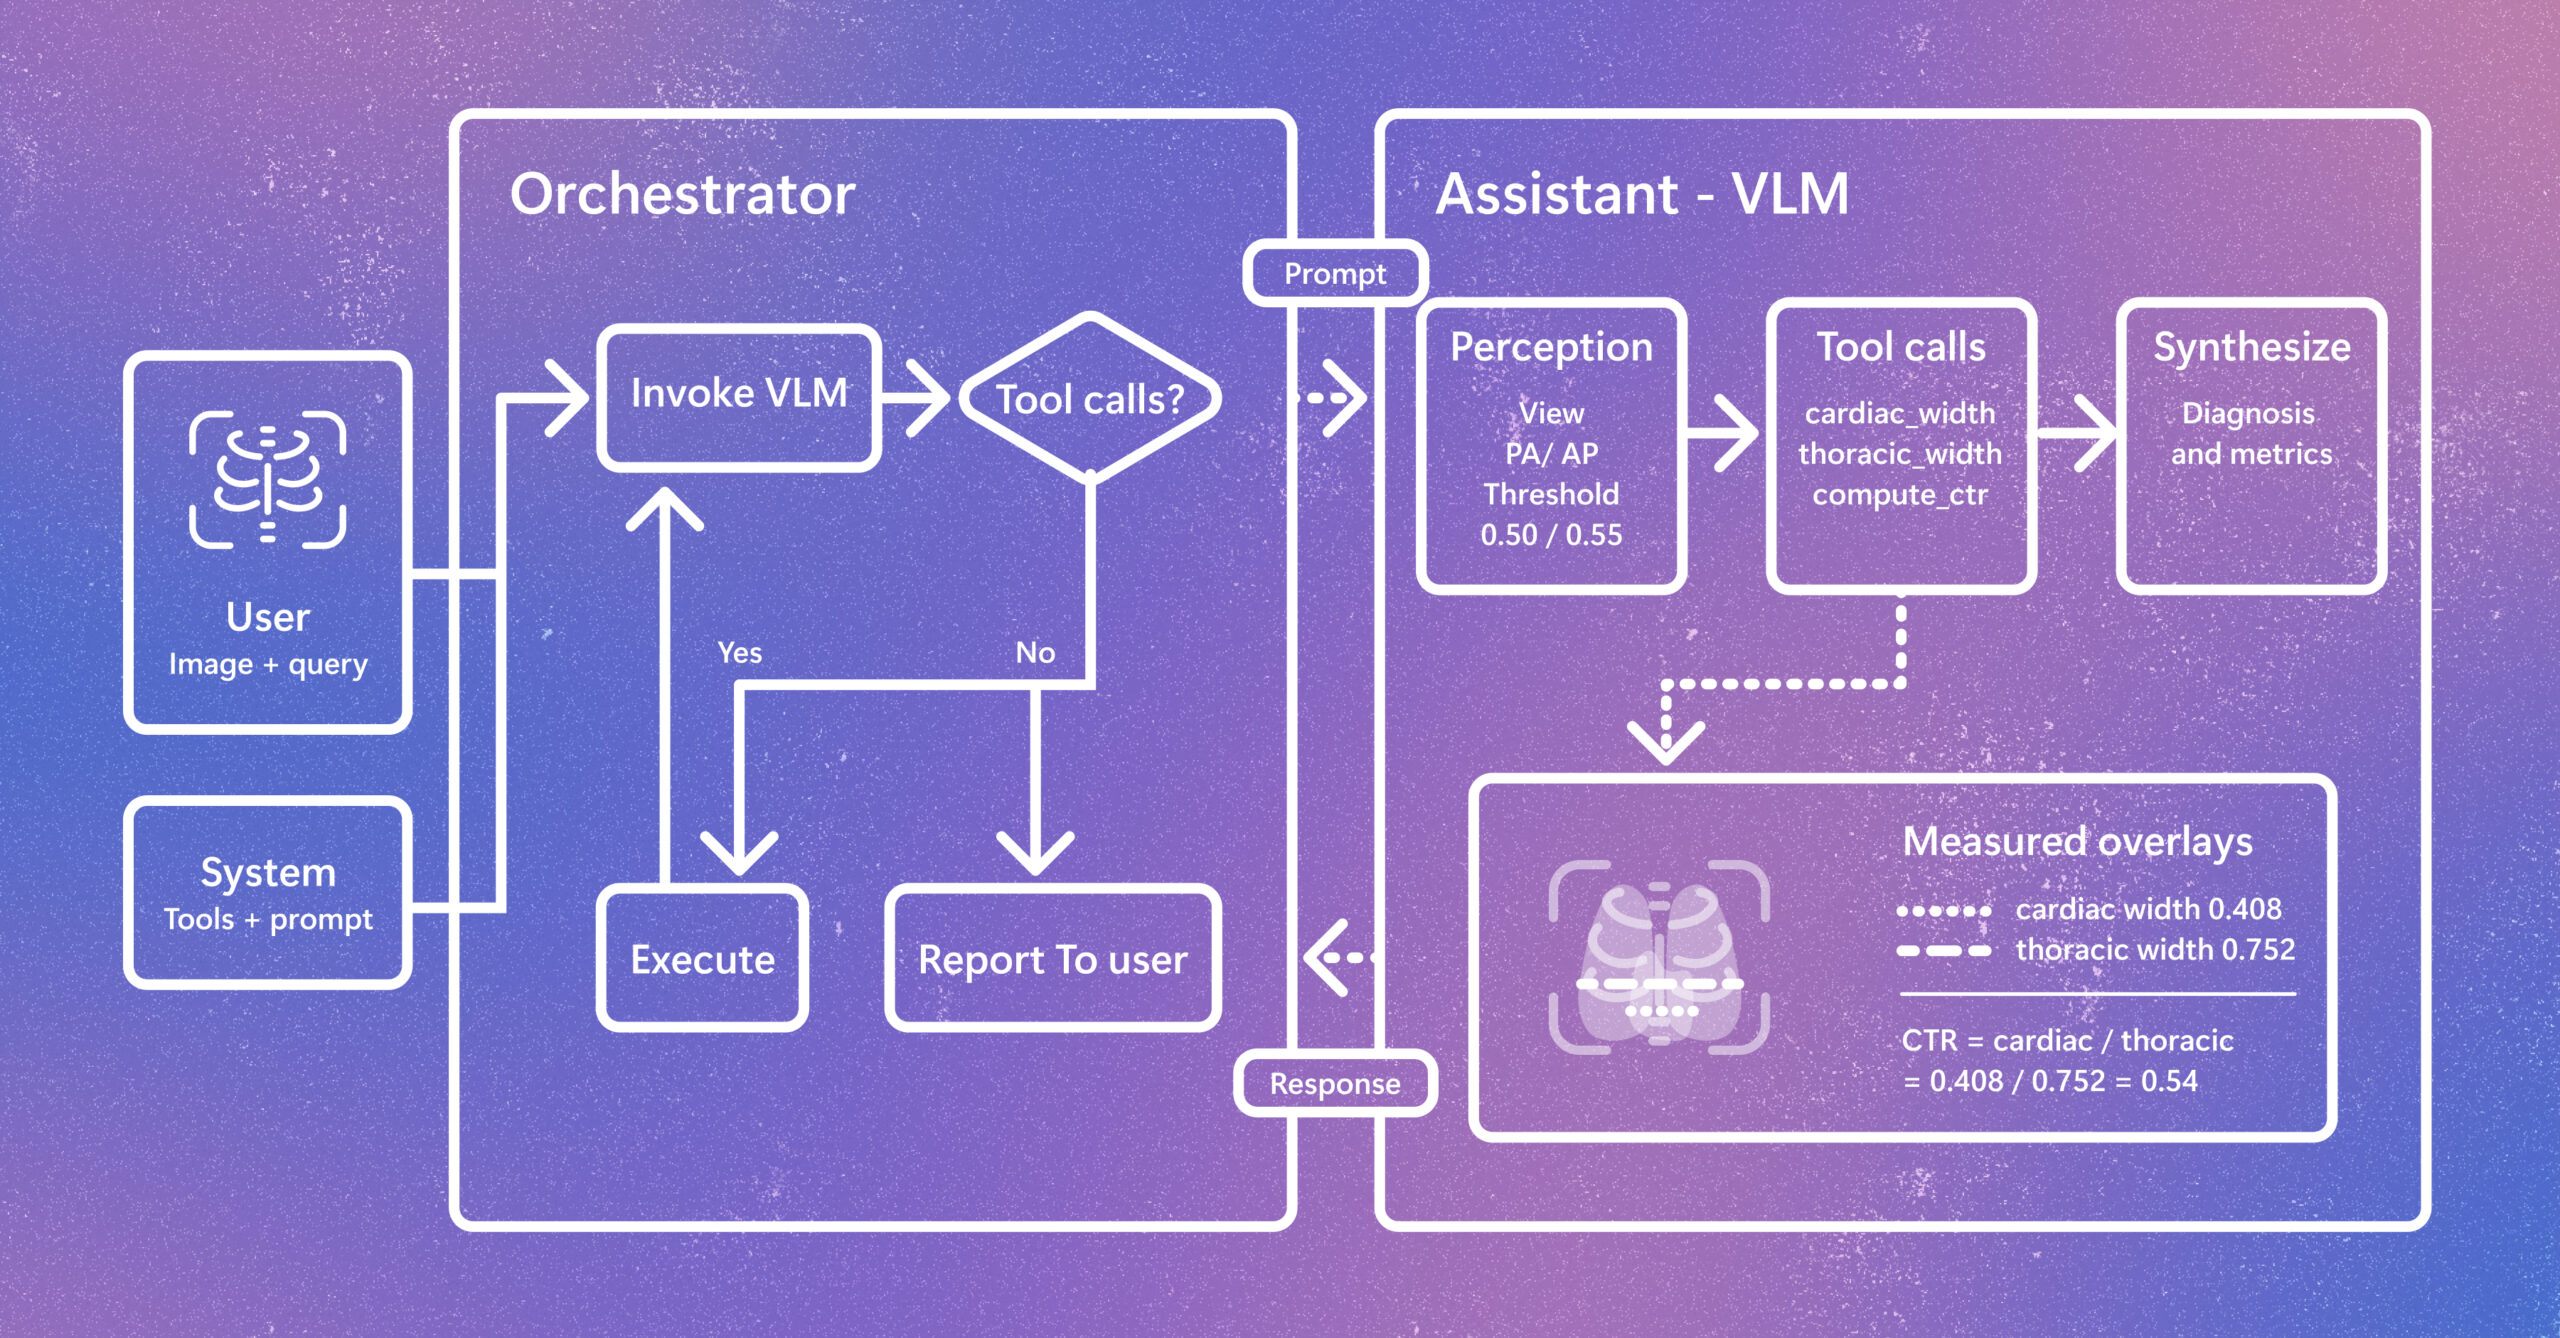
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.