This work proposes Ontology-Masked Reasoning Autoencoding (OMRA), a controlled intervention that masks and reconstructs over-explained spans while preserving stance, factual content, and coherence and reduces the measured gap between AI preference and real user engagement.
Abstract
Large language models are increasingly used to generate and evaluate online content, yet it remains unclear whether the qualities they associate with higher engagement match what real users respond to. We study this question using 1.17 million answers to 25,978 questions from Zhihu, Quora, and Reddit, comparing real platform answers and AI-generated answers across four within-question engagement levels. We introduce Ontological Preference Measurement, which represents answers along three dimensions: logic, affect, and expression. We find a systematic gap between AI preference and real user engagement: as target engagement increases, LLMs add more explicit logical structure, while real user engagement is more strongly associated with affective and expressive salience. We call this tendency logic overbinding. Based on this diagnosis, we propose Ontology-Masked Reasoning Autoencoding (OMRA), a controlled intervention that masks and reconstructs over-explained spans while preserving stance, factual content, and coherence. Across four LLM families, OMRA reduces the measured gap by an average of 54.4%. In human evaluation, OMRA wins 62.4% of pairwise preference judgments against matched real platform answers, even though the real answers are more often judged to be human-written.

An understanding gap is illuminated: user attributions are partly guided by epistemic orientation and experiential ascriptions that make sophisticated simulation appear as understanding, especially in affective interaction, raising urgent questions about epistemic trust, relational vulnerability, and the ethics of AI c...
Erez Firt, Rinat B. Rosenberg-Kima· AI & SOCIETY· 0 citations
Examination of undergraduate students in an operations management course who first solved a linear programming problem manually and then used GenAI on the same task shows that students can position GenAI differently within the same technical task, from receiving answers to verifying existing reasoning or seeking concep...
A. Jaiswal, Gaurav Nanda· International Journal of STE...· 1 citation
The intersection of psycholinguistics and cognitive science is proposed as the most productive starting point for modeling users as whole persons rather than collections of attribute preferences.
S. Maheshwari, Priyansh Singhal· Proceedings of the 20th ACM...· 0 citations
This work conducts a controlled human study of six reasoning formats across tasks of varying complexity, supported by a web-based framework that randomizes task domains, problem instances, and representation order.
This work analyzes ChatGPT and Gemini conversations, using repeated prompting and clarification following misunderstanding as behavioural indicators of cognitive difficulty, and finds that response characteristics such as length, readability and lexical diversity do not have fixed relationships with conversational diff...
Ying-Can Wang, I. Bilal, Q. Zaman· arXiv.org· 0 citations
This research examined how public communication about emerging technologies is shaped through platform-specific multimodal conventions and engagement dynamics on TikTok to provide insights for stakeholders who seek to promote responsible AI communication on video-sharing platforms where algorithms shape which content i...
Xi-Ran Liu, M. S. Schäfer· Emerging Media· 1 citation
Related blog posts
Microsoft Research Blog· microsoft.comNov 16, 2026
AI coding agents are increasingly help developers fix bugs and build features largely on their own, but every interaction with their models consumes tokens. In each session, an agent sends instructions, tool descriptions, and session history to its model. Most efforts to reduce this cost focus on individual tasks. Yet developers return to the same […] The post TokenEconomizer: Learning from Experience to Make AI Coding Agents More Efficient appeared first on Microsoft Research.
At ICSOB 2026 in Gothenburg, we presented TenderIntell, our work on multi-agent support for tendering. This post looks back at the conference, the idea behind a panel of three AI reviewers who score each proposal independently, and why evaluating agents reliably is the question we keep coming back to. The post TenderIntell at ICSOB 2026: Three Days in Gothenburg appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduNov 13, 2026
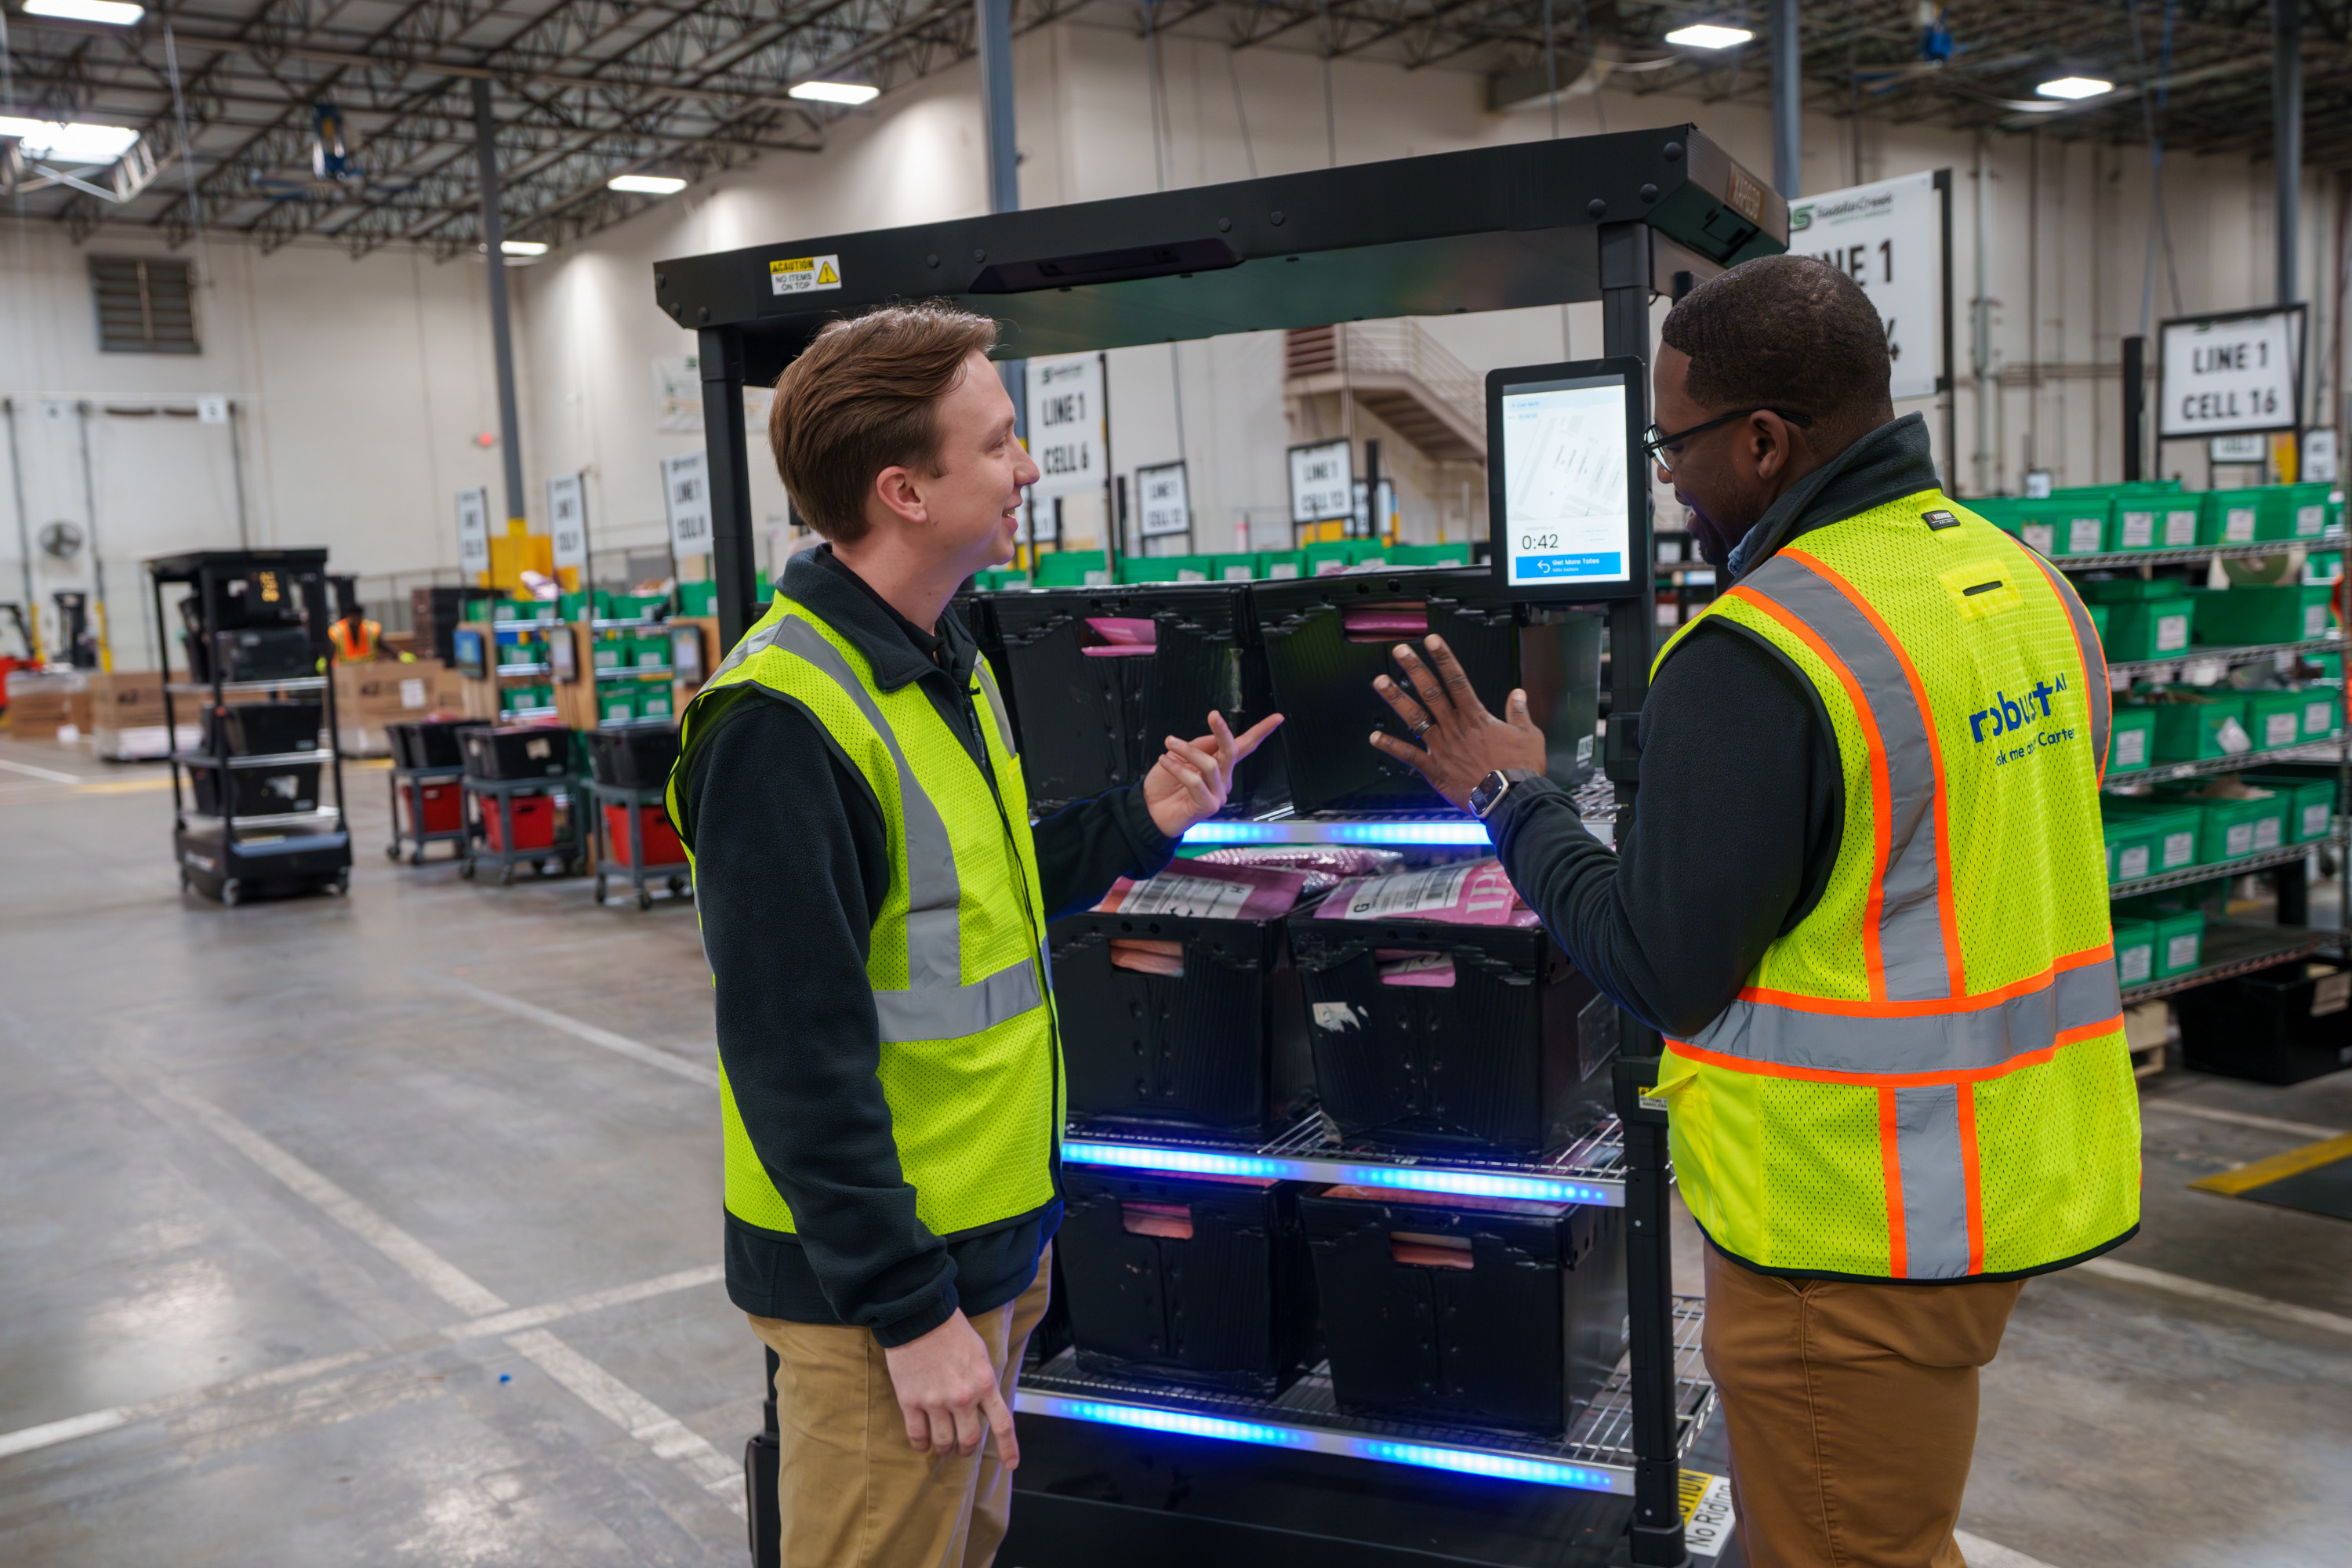
Founded by Anthony Jules ’92, SM ’92 and Professor Emeritus Rodney Brooks, Robust AI’s robots are designed to collaborate with humans in factories and warehouses.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.