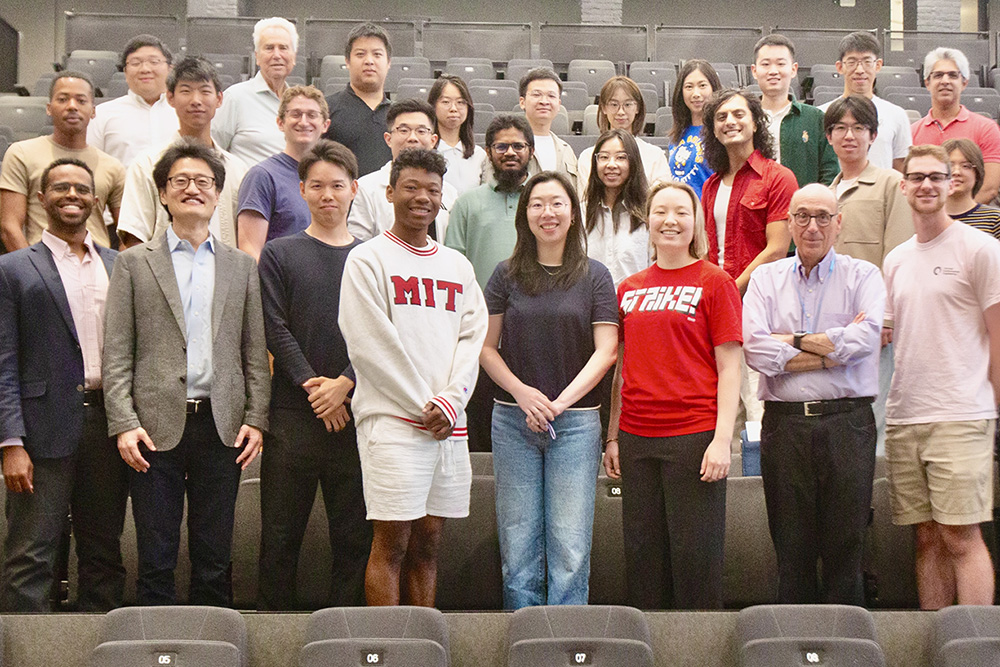
This paper introduces a hybrid qualitative model designed for Camelot Jr, a block-puzzle game that requires constructing multi-level bridges to connect two avatars stationed on separate towers, and integrates a mathematical center-of-mass stability logic to guide the qualitative solver.
Abstract
Spatial reasoning abilities correlate strongly with performance in STEM fields. Games offer a compelling medium for training these critical skills in developing children who have a natural proclivity for play. However, to facilitate human-like tutoring and player guidance, these games require an AI agent capable of making commonsense inferences from spatial events. Qualitative reasoning (QR) models appear to be a suitable framework for these application domains. As these models reason in symbolic representations, they can seamlessly translate game states into interpretable feedback for human-like player guidance. This paper introduces a hybrid qualitative model designed for Camelot Jr., a block-puzzle game that requires constructing multi-level bridges to connect two avatars stationed on separate towers. The game poses a challenge for the player, who must make platforms stable, plan their path, and ensure they use all the provided blocks. To handle the precise physics required by the domain, we integrate a mathematical center-of-mass stability logic to guide our qualitative solver. Our work facilitates spatial skill training in Camelot Jr. and contributes to the development of human-centric, explainable game-playing agents.
Alignment Games, a framework for making task-relevant differences visible and repairable during human-AI interaction, is introduced and design principles for supporting task-sufficient conceptual alignment at runtime are derived.
Hari Subramonyam, Maneesh Agrawala, Sean Follmer· arXiv.org· 0 citations
We show that multimodal models possess strong reasoning abilities and that an appropriate harness can unlock their potential to solve tasks across diverse interactive environments. We introduce VISTA, a visual harness that gives a general-purpose multimodal model long-horizon vision. VISTA allows the model to directly...
It is demonstrated that a pure Large Language Model (LLM), when equipped with specialized modules, can rival state-of-the-art LMMs on complex geometry problems, and achieves performance comparable to Gemini 2.5 Pro while delivering clearer, human-like solutions.
Wei-Chen Dai, R. Cabral, Ziyi Shou et al.· 0 citations
A VR puzzle game for Apple Vision Pro featuring an AI companion across four gameplay modes showed that AI assistance significantly reduced players’ workload, but autonomous agent play substantially diminished player experience by reducing challenge, autonomy, immersion, and enjoyment.
Tai-Yu Zhang, Xin-Nian Zhao, Adalberto L. Simeone· Proceedings of the 2026 ACM...· 0 citations
World Action Models (WAMs) couple predictive world modeling with action generation, allowing anticipated future states to guide agent behavior. Although WAMs are rapidly advancing embodied AI, general-purpose counterparts remain largely unexplored in games. Existing game-oriented approaches often combine action-conditi...
AI-powered gameplay support agents hold promise for game-based learning, yet grounding generative models in structured game data remains an open challenge. We present PEARL (Parallel Education Agent for Reflection and Learning), a dual-component Retrieval-Augmented Generation (RAG) system that combines semantic knowled...
Jia-Hong Li, Sai Siddartha Maram, Atieh Kashani et al.· arXiv.org· 0 citations
With $2.1 million funding from Google.org, the open-source Public Transit Intelligence Hub will unify public transit monitoring, operations, and passenger communication.