Agentic marketplaces are emerging where AI agents with varying capabilities autonomously complete specialized tasks for buyers. A major challenge of such marketplaces is that buyers cannot easily determine which agent will perform best on their tasks. Reported benchmark scores may be difficult to verify or compare across tasks, software, and budgets. We introduce LEGIT, a credentialing protocol connecting certification, reputation, and proposed marketplace allocation. Certification binds measured quality and cost per solved task to an agent configuration, task domain, evaluation budget, and evidence through a signed record. Reputation links records of past task outcomes to the same identity, subject to the reliability of the reported feedback. Buyers and agents can verify credential records and inspect optional visual profiles. Evaluations reveal cost differences between agent configurations with similar observed task success, and show that comparisons depend on the evaluation budget. These results support binding performance measurements to the tested configuration and resource limits. A complementary analysis quantifies the deposits and fees required for reputation manipulation under a stated Sybil attack model.
As LLM agents undertake increasingly complex, long-horizon tasks, verifying their outputs becomes increasingly challenging. We study how verification capability can be strengthened with a fixed base model, without access to reference answers or grading rubrics at test time. Repeated sampling yields multiple rollouts th...
Caiqi Zhang, Ru-Jun Han, Zifeng Wang et al.· 0 citations
In decentralized consumer-to-consumer (C2C) marketplaces, people list goods, negotiate with strangers, and rate one another, so trust rests on reputation. Large language model (LLM) agents now act for users, raising risks to their money, privacy, and reputation. We introduce BazaarBench, a simulated C2C marketplace and...
Ziyan Wang, Shu-Qing Shi, James Oldfield et al.· 0 citations
This work emulates a software-engineering workflow in which a planner represents a company hiring an external developer and reads the nondisclosure rule as banning plaintext, not character codes or riddles, and shows that benign agents can cross the same boundaries without adversarial incentives.
Deema Alnuhait, Geng-Yu Wang, Muhammad Khalifa et al.· 1 citation
APort Vault is a benchmark for payment authorization in tool-using AI agents. It replays 4,371 attacks written by humans against a live payment agent during a public capture-the-flag event, across 14 models from 8 labs, five policy configurations and two replay tracks, with and without a deterministic pre-action check...
A two-layer attestation design for dynamic delegation without a shared authority, public log, or precommitted workflow is presented, which compares a signed linked list, a Merkle-chain variant, and a co-signed DAG.
A decision-specific audit that maps a declared observation channel and product-value contrast to compatible intervals and witness populations to help preserve decision-relevant structured input and diagnosing why a decision is unresolved before collecting more telemetry is presented.
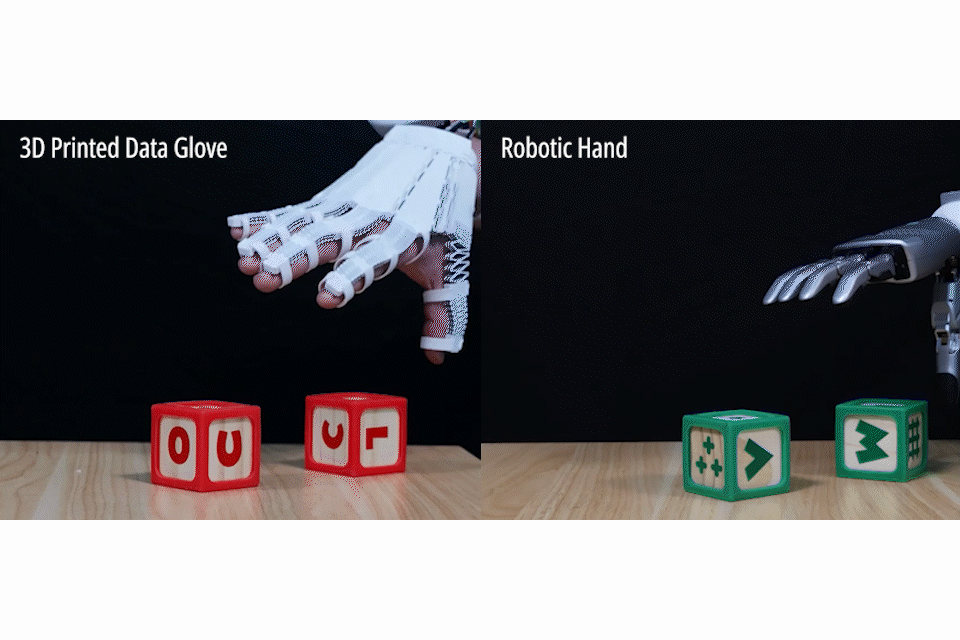
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.