May 2026· arXiv.org· Vol abs/2605.01017· 0 citations· 38 references
Computer Science
TL;DR
A controlled pilot shows that LLM-generated Xiaohongshu-style posts can shift perceived standing and comparison-related affect even when prompt-based detection of the same construct remains fragile.
Abstract
We introduce Xiaohongshu Social Comparison Reader Elicitation (XHS-SCoRE), a reader-grounded benchmark for detecting whether text-only Xiaohongshu (RedNote) posts elicit Upward, Downward, or Neutral/no clear social comparison from a first-person reader perspective. The task targets a socially meaningful relational, behaviorally real signal not reducible to sentiment. Across prompted LLM classifiers and supervised Chinese encoders, we find a consistent generation-detection mismatch: the signal is textually learnable in-domain, but not robustly accessible to prompt-based classification. Prompted LLM classifiers show stable failures, especially neutralization of comparison-eliciting posts and model-specific directional skew. A controlled pilot shows that LLM-generated Xiaohongshu-style posts can shift perceived standing and comparison-related affect even when prompt-based detection of the same construct remains fragile. XHS-SCoRE contributes a benchmark for reader-grounded comparison detection and a diagnostic framework for studying when socially meaningful relational cues remain only partially visible to prompt-based inference.

Moral language plays a central role in shaping online endorsement and the diffusion of information, yet existing moral foundation detection systems often suffer from poor cross-domain generalization, weak rationale grounding, and reliance on costly prompting-based large language models (LLMs). We introduce CHARM, a MAC...
Experiments across three LLMs show that Acmite effectively mitigates gender bias across complementary evaluation formats while maintaining competitive performance on bias-unrelated tasks.
Tian Lan, Xiao-Qing Cheng, Han Zhang et al.· 0 citations
A benchmark for evaluating whether LLMs can recover situated pragmatic meanings in Chinese online comments is introduced, and case analysis shows that models often recognize broad irony or playfulness while misidentifying the mechanism or interactional move.
Yin-Hong Shi, Jun-Jie Ma, Emma Jiren Wang et al.· 0 citations
This work introduces a minimal "observer-effect" prompting technique, which demonstrates that subtle social-facilitation cues can reliably activate higher vigilance in LLMs without the need for additional reasoning instructions.
: Large language models (LLMs) are reshaping social bot detection by decoupling automated intent from surface-level expression. This decoupling weakens a central assumption behind contemporary detectors: that an account’s textual persona, profile metadata, and graph position remain jointly stable across evaluation. An...
Zhen-Yuan Wang, Li-Xin Ji, Shu-Xin Liu· Computers, Materials & C...· 0 citations
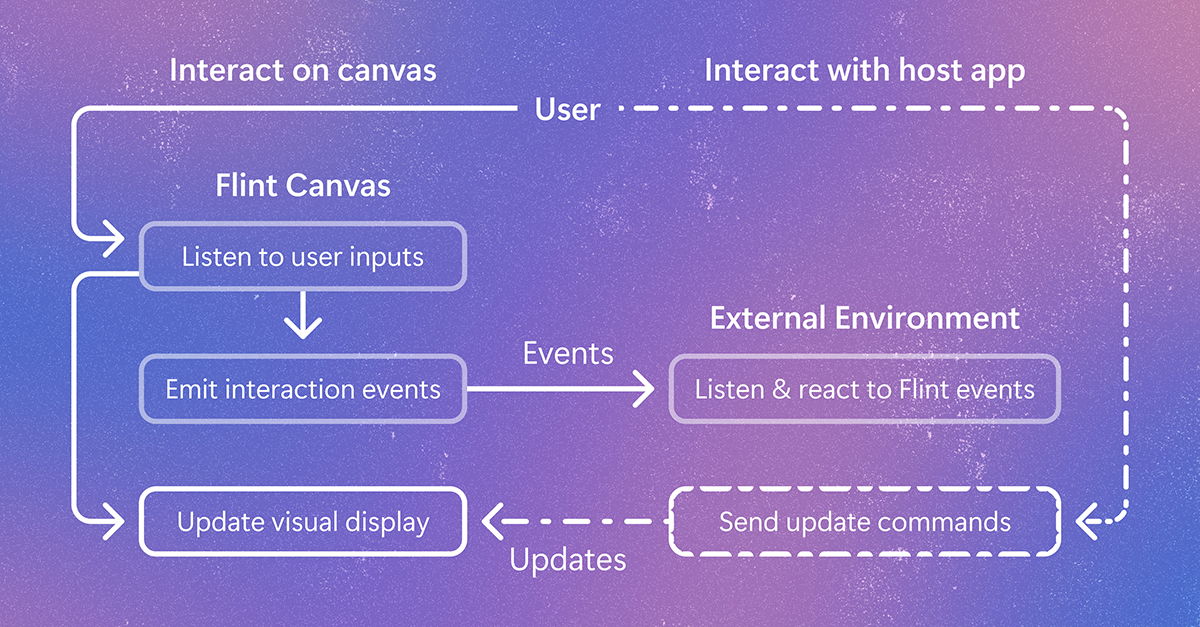
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.