A recurrent-style training strategy is proposed, which enables transformers to reuse their reasoning circuitry across input forms and substantially improves generalization on out-of-distribution two-hop queries.
Abstract
Large language models (LLMs) can solve complex multi-hop problems yet exhibit puzzling failures on simple two-hop queries: although a model may correctly store each individual hop, it often fails to combine them. To understand the internal mechanisms of this phenomenon, we train transformers from scratch in a controlled symbolic environment. Our experiments reveal a pattern in two-hop generalization: models generalize reliably when the second hop follows the training distribution, but always fail when it deviates. Through mechanistic analysis, we provide a complete explanation for these distinct generalization behaviors: in settings where models generalize successfully, performance is driven by the emergence of consistent intermediate representations for the same entities across contexts, whereas failures on settings where the second hop is out-of-distribution arise from a mismatch across layers: lower layers correctly construct these intermediate representations, but upper layers, while trained on corresponding atomic facts, primarily learn to map them to outputs rather than to reason over them. Driven by this insight, we propose a recurrent-style training strategy, which enables transformers to reuse their reasoning circuitry across input forms and substantially improves generalization on out-of-distribution two-hop queries. Our data and code are available at https://github.com/zzl-strong/two_hop .

A formal way to investigate global understanding in language and world models is provided and compositional training promotes information propagation and integration and demonstrates that compositional training promotes information propagation and integration.
For Your Eyes Only, a cooperative signalling game designed to evaluate can a model embed a signal in natural language that an independent instance of the same model can detect, without any shared memory or coordination-specific training is introduced.
This work studies activations from ensembles of prompts that require inferring relationships between three tokens corresponding to a cyclic concept to correctly predict the next token and finds a consistent layerwise progression in how the joint dependence among the tokens is geometrically organized and causally used.
Gurbir Arora, To-Ni J. B. Liu, Jiajun Bao et al.· 0 citations
Language models can now prove theorems, but people still decide which problems to pursue. We ask whether a model's internal representations can help identify promising mathematical connections. We develop LANTERN, a fast, cost-efficient pipeline that uses a classifier over pretrained-model activations to rank candidate...
Pavel Tikhonov, Elena Tutubalina, I. Oseledets et al.· 0 citations
It is argued that behavioral evaluation understates what models encode, while probing alone overstates what they deploy, in a three-level evaluation framework measured on the same items under the same binary decision.
The results show that different thinking mechanisms can learn distinct computational solutions, even at similar ID performance, and in this setting, latent recurrence supports a reusable forward-search algorithm that generalizes beyond the training depth.
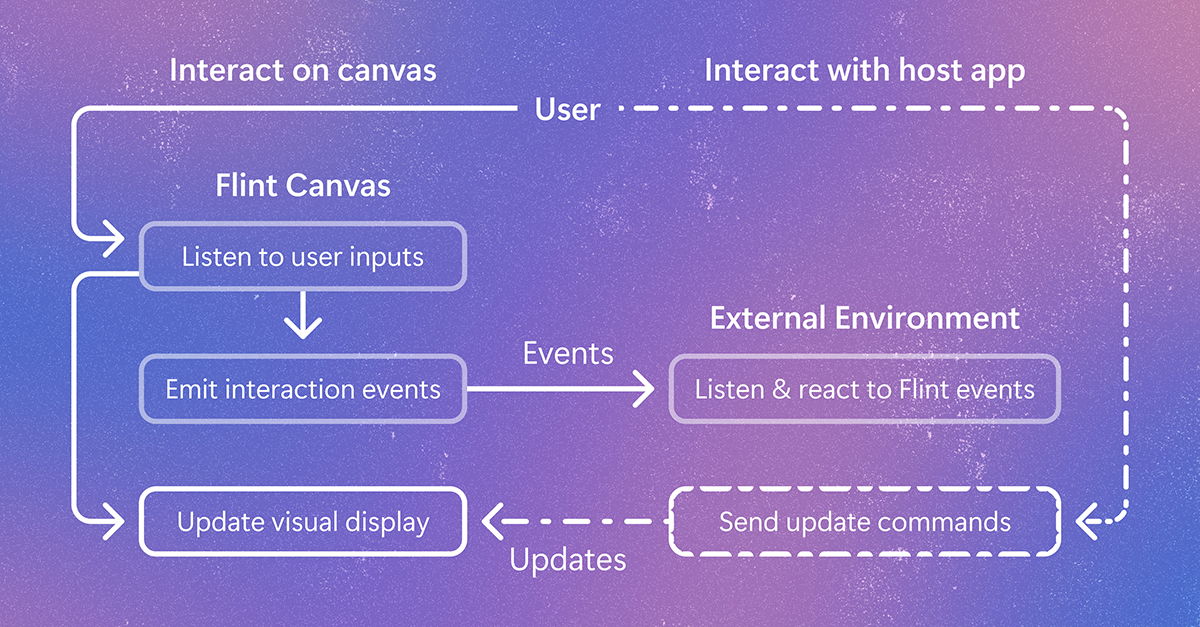
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.