GPU acceleration is now routine across robotics, but cloud-hosted GPU continuous integration (CI) runners are expensive, resulting in severe under-testing of GPU-accelerated code. We present pytest-gpu-proof, an open-source pytest plugin offering a practical middle ground. Tests can be run on a local machine, signed with a receipt of exactly what ran and what it produced, and integrated into standard CPU CI workflows (e.g., GitHub Actions). The tool is open source and on PyPI, and we are actively integrating it across our lab's software stack.
This work introduces Backline, a heterogeneous compilation and runtime framework built within PennyLane and Catalyst that allows researchers to write workloads in high-level languages that map to low-latency execution across diverse distributed target platforms, and demonstrates the compilation and execution of several...
Joseph K. L. Lee, M. Malekmohammadi, Hong-Sheng Zheng et al.· 0 citations
We propose PKDB, the first interactive debugger for GPU and multithreaded low-level kernels written in Python. Python is widely used in high performance computing (HPC), with frameworks such as PyKokkos translating Python-embedded domain-specific languages to native code that runs across OpenMP-threaded CPUs and variou...
Ivan Grigorik, Gabriel Kosmacher, G. Biros et al.· 0 citations
GPUPhysBench brings physical simulation workloads to coding-agent evaluation, testing both the ability to implement numerical methods correctly and the ability to make them run efficiently.
Yu-Chen Sun, Jin-Jin He, Si-Nan Wang et al.· 0 citations
This paper presents an OpenMP-style parallelism API for Uxntal, the stack-based assembly-style language for the Uxn platform, and demonstrates that exemplar code using this API can run at comparable performance even on an integrated GPU.
S. Li, Vladislav Brusokas, Andrei Ghita et al.· 0 citations
Cerium is a multi-GPU framework for large-scale FHE inference that combines a domain-specific language, an optimizing compiler, and a runtime system to automatically generate optimized GPU kernels, compress plaintext data, manage terabyte-scale memory footprints, and optimize multi-GPU communication.
Siddharth Jayashankar, Joshua Kim, Michael B. Sullivan et al.· Proceedings of the ACM SIGOP...· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
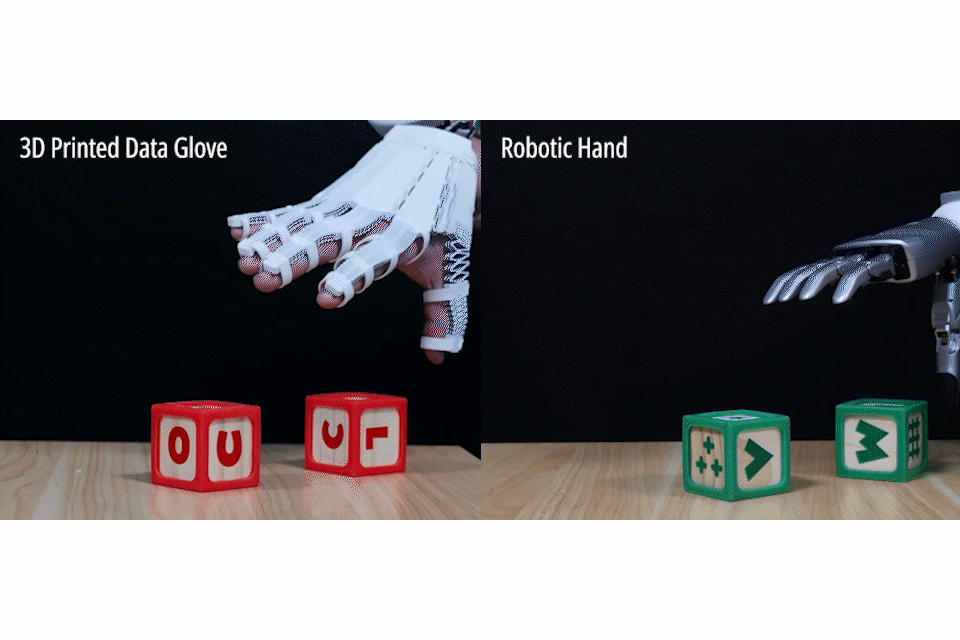
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.