Sep 2026· Zenodo (CERN European Organization for Nuclear Research)
Reinforcement Learning in Robotics
Abstract
Safe reinforcement learning requires balancing task performance against safety constraints, yet how different safety mechanisms interact when combined remains an open question. We present a systematic empirical comparison of four reinforcement learning algorithms, PPO, SAC, RCPO (with fixed λ), and Lagrangian PPO (LagPPO), each trained with and without a geometric keepout shield on the SafetyPointPush1-v0 benchmark. Our 4×2 factorial experiment across three random seeds reveals that safety mechanisms are not interchangeable and exhibit distinct trade-offs. RCPO achieves the lowest constraint violation rate throughout training but at significant cost to task return. SAC converges fastest in return but incurs high safety cost without explicit constraints. Because each seed fixes the hazard layout, conditions can be compared on matched geometry. Under that pairing, shielded LagPPO ends with a lower Lagrange multiplier than its unshielded counterpart in all three seed pairs, and unconstrained PPO intervenes more often than LagPPO in all three. Both orderings are consistent in direction but their marginal distributions overlap, so three seeds do not resolve their magnitude. No algorithm achieves zero violations within one million training steps, highlighting the difficulty of full constraint satisfaction under compute constraints. Our results suggest that safety mechanisms should be treated as composable components with distinct trade-offs, and that the appropriate choice depends on whether the priority is constraint satisfaction, task performance, or both. We also report an implementation defect discovered during analysis: the shield's position extraction returns sensor components rather than agent coordinates on this observation space, so the shield-on conditions should be read as an action-perturbation baseline rather than a geometry-aware keepout shield.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
It is found that roles of MVPs in startups were not fully aware by entrepreneurs, and entrepreneurs should consider a systematic approach to fully explore the value of MVP, as a multiple facet product (MFP).
Anh Nguyen-Duc, P. Abrahamsson· International Conference on...· 93 citations· ⚡9
It is found that what perceived as biggest challenges by software startups do vary across different life cycle stages, even though its significance decreases when the learning focuses of the startups move from problem to solution and their products mature.
Xiaofeng Wang, Henry Edison, Sohaib Shahid Bajwa et al.· International Conference on...· 62 citations· ⚡6
A comprehensive overview of how enhanced sampling methods are reshaping the field, with a particular focus on the data-driven construction of collective variables, is provided.
Kai Zhu, Enrico Trizio, Jintu Zhang et al.· Chemical Reviews· 58 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
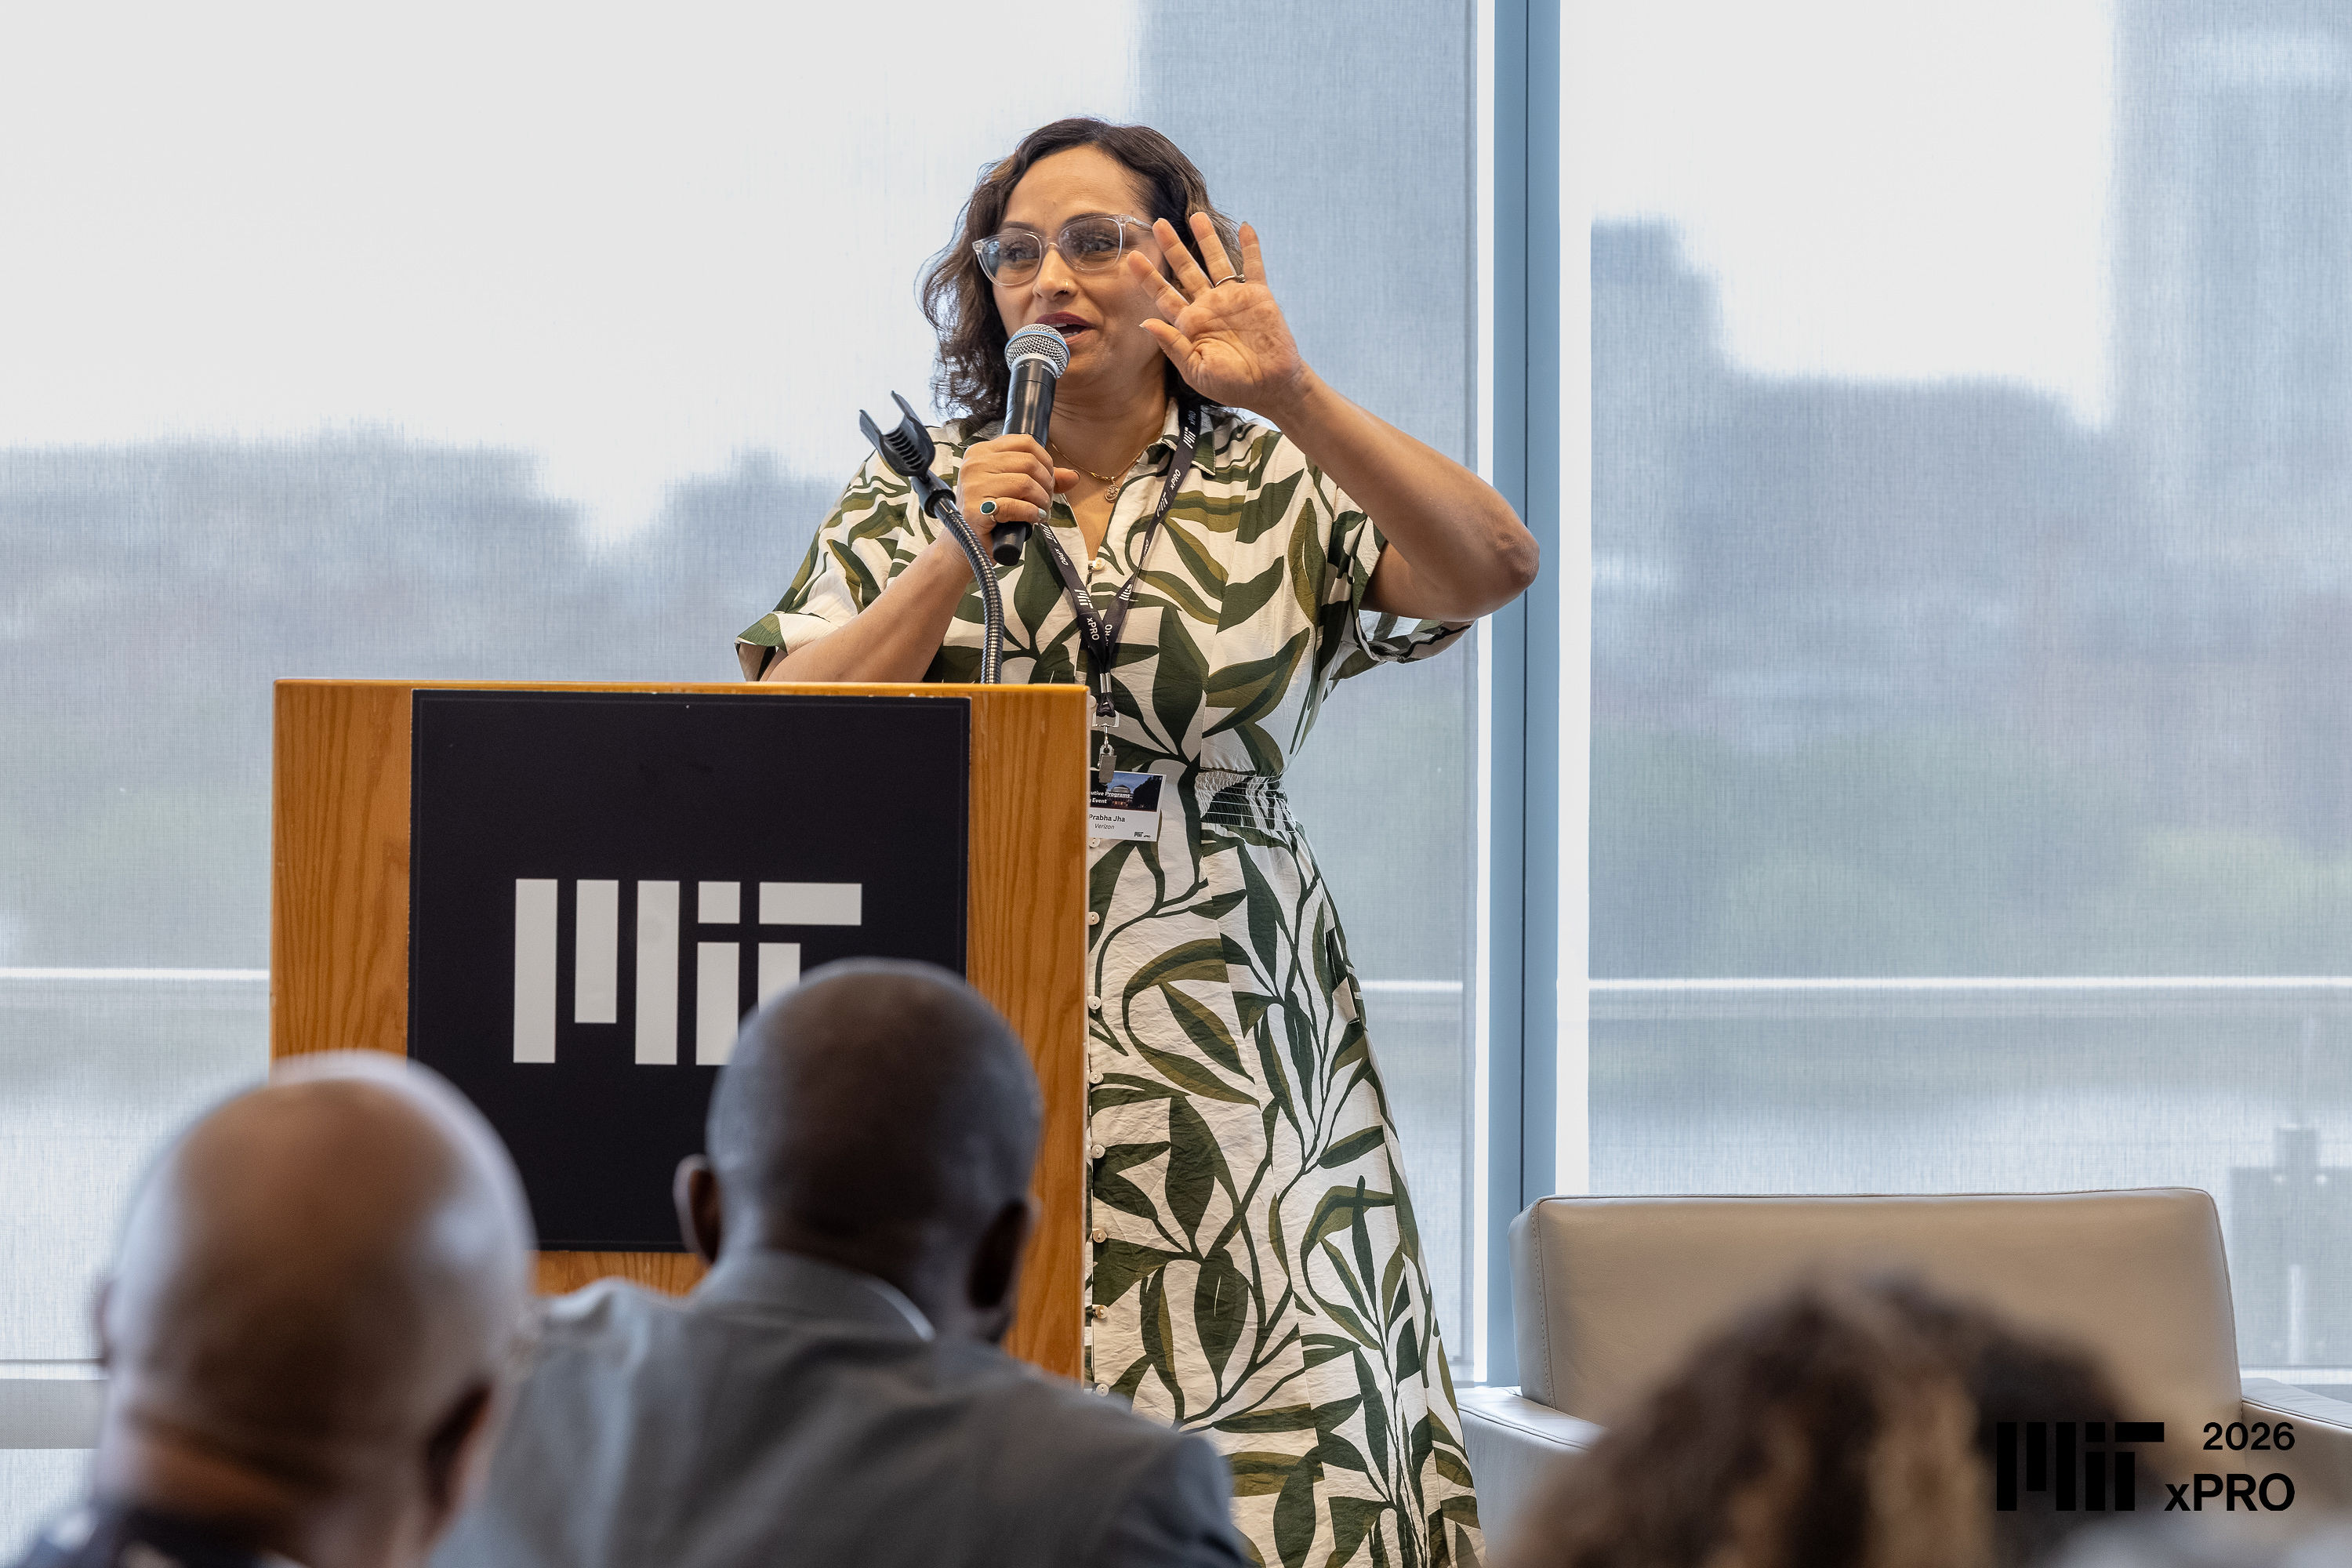
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

