The results invert the pre-registered prediction that most attention heads behave like Kohn-nearsighted insulators, pointing instead to critical, glassy or heavy-tailed regimes; the inversion is specific to the<= 350M scale tested, while the rank-face no-gain result held to 7-8B.
Abstract
We report a three-month autonomous research-agent program testing five solid-state-physics-inspired compression mappings on pretrained language models, with predictions committed to git before any pilot data and a 3-sigma gate deciding PASS or SHELVE. The common anchor -- area-law / Kohn-nearsighted decay of the one-particle density matrix -- has a distance face (P001 Wannier, P002 tight-binding) and a rank face (P003 DMRG-truncated MLPs, P005 Wilson-RG, P011 tensor-train embeddings). P005 was pre-empted at Phase 1; three of four Phase-3 pilots were falsified. On the attention face, GPT-2-medium attention-versus-distance is best fit by a stretched exponential in 12 of 16 median-layer heads once probe padding is excluded, and a tight-binding cutoff costs +96% perplexity (P002); on Pythia-160M the Wannier sparsity 0.054 +/- 0.004 is indistinguishable from PCA, random-Haar and identity baselines (P001). On the rank face, per-token tensor-train bond dimension does not track surprisal (r = 0.016 vs a pre-registered 0.65) and the format inflates rather than compresses (P011). P003 is mixed: its scaling claim shelved (r = -0.434), its MPO premise died at stage-0, and its cross-paper check, r = 0.523 as first written, collapses to 0.047 under the same correction, leaving both cross-paper checks null. The results invert the pre-registered prediction that most attention heads behave like Kohn-nearsighted insulators, pointing instead to critical, glassy or heavy-tailed regimes; the inversion is specific to the<= 350M scale tested, while the rank-face no-gain result held to 7-8B. We contribute the pre-registration + 3-sigma + cluster-framing + append-only-catalogue discipline -- including why our own enforcement gate was designed but not deployed -- four pre-registered negative results with full data release, and the inversion. The catalogue holds eighteen concluded studies, seventeen negative.

The results separate what physics structure preserves from what TinyML deployment must measure explicitly, as structure improves Burgers accuracy and antisymmetry at a given footprint rather than automatically shrinking hardware requirements.
Sorin Liviu Jurj· Machine Learning and Knowled...· 1 citation
PINN-Phase is introduced, a physics-informed neural time integrator that advances the full multiphase field from its initial condition and enforces phase bounds and unit sum at every step; on the reported explicit multiphase-field benchmarks, post-initial-condition reference states serve only for evaluation.
Seifallah Elfetni, Sascha Thinius, P. Seeberger et al.· 0 citations
The enormous recorded data at high-energy physics (HEP) colliders make the accurate identification of physics objects a bottleneck in disentangling event topologies, where machine learning has become a standard tool for jet tagging. In this work, we examine whether Vision-Language Models (VLMs) can provide a common int...
Pretrained machine-learning interatomic potentials, so-called universal or foundation models offer an appealing starting point for atomistic simulations, but their accuracy for material-specific observables often remains limited without additional reference data (fine-tuning). Here, we systematically quantify how much...
These results establish recipe-dependent interactions and identify concrete precision assignments, rather than universal layer-sensitivity rules, rather than universal layer-sensitivity rules for vision-language-action models.
Jiu-Yi Xu, Qing Jin, Mei-Da Chen et al.· 0 citations
We implement the machine-learned Skala exchange-correlation (XC) functional natively in CP2K using its Gaussian and plane-wave (GPW) and Gaussian and augmented-plane-wave (GAPW) methods. A joint one-centre reconstruction of density, density gradients, and kinetic-energy density before functional evaluation preserves mi...
Johann Pototschnig, Franz Pöschel, Jürg Hutter et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
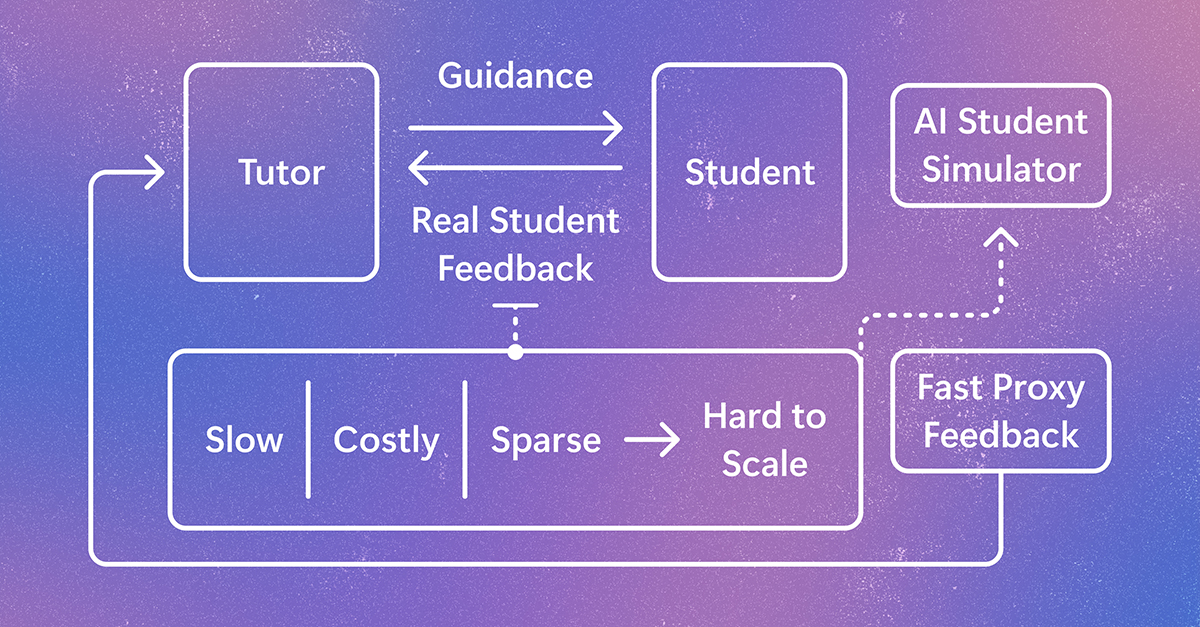
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.