It is found that applying textual guidance too early can limit its ability to identify answer-relevant visual regions, whereas text-to-visual attention becomes more informative at intermediate decoder depths.
Abstract
Visual token pruning has been widely studied as a practical approach to reducing the computational cost of large vision-language models. However, it struggles to preserve essential visual information, which can lead to substantial performance degradation. In particular, image-based token selection can overlook task-relevant details, while text-guided token selection may fail to capture the text--visual relationships needed for complex reasoning. We find that applying textual guidance too early can limit its ability to identify answer-relevant visual regions, whereas text-to-visual attention becomes more informative at intermediate decoder depths. This finding motivates our training-free method, which separates early vision-guided pruning from deferred text-guided reselection. We first prune visual tokens using vision-encoder attention, retain additional candidates until the decoder midpoint, and then use text-to-visual attention to determine the final visual-token set. Across eight benchmarks and three models, our method outperforms the best-performing baselines by an average of 11.10 and 16.84 percentage points in performance recovery at 80% and 90% pruning, respectively, with comparable or lower LLM-prefill latency than most baselines. The source code is publicly available at https://github.com/kmc3661/DeFT

TReVS is proposed, a training-free framework that combines textual relevance with vision-encoder saliency for pre-LLM pruning and leverages high-variance attention heads to remove task-irrelevant tokens at shallow-to-intermediate layers of the LLM.
Large vision-language models (LVLMs) have recently been extended to handle multiple input images, but this extension dramatically increases the visual token budget, making visual-token pruning not merely an efficiency option but a practical necessity. Existing visual-token pruning methods, primarily designed for the si...
Dong-Jin Lee, Eunju Lee, Jinhee Jang et al.· Proceedings of the 35th ACM...· 0 citations
Large vision-language models (LVLMs) represent images and videos as long visual-token sequences, substantially increasing inference costs. These costs motivate visual-token pruning, whose effectiveness depends on both what signal is used for selection and when that signal becomes available. Our analysis reveals complem...
Intaek Shin, Geuntaek Lim, Sungjune Park et al.· 0 citations
Large Vision-Language Models achieve strong VQA performance, but processing high-resolution, information-rich images requires substantial computation, motivating visual token reduction. However, existing methods often prune individual tokens or rely on fixed-size cropping, limiting their ability to preserve spatially s...
Large Vision-Language Models (LVLMs) often process hundreds or thousands of visual tokens, resulting in substantial computational and memory overhead during inference. Existing training-free pruning methods typically estimate token importance using language-model attention, visual attention, or feature similarity. Howe...
Zi-Hao Qi, Zhi-Bo Zhang, Miao-Xin Zhang et al.· 0 citations
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
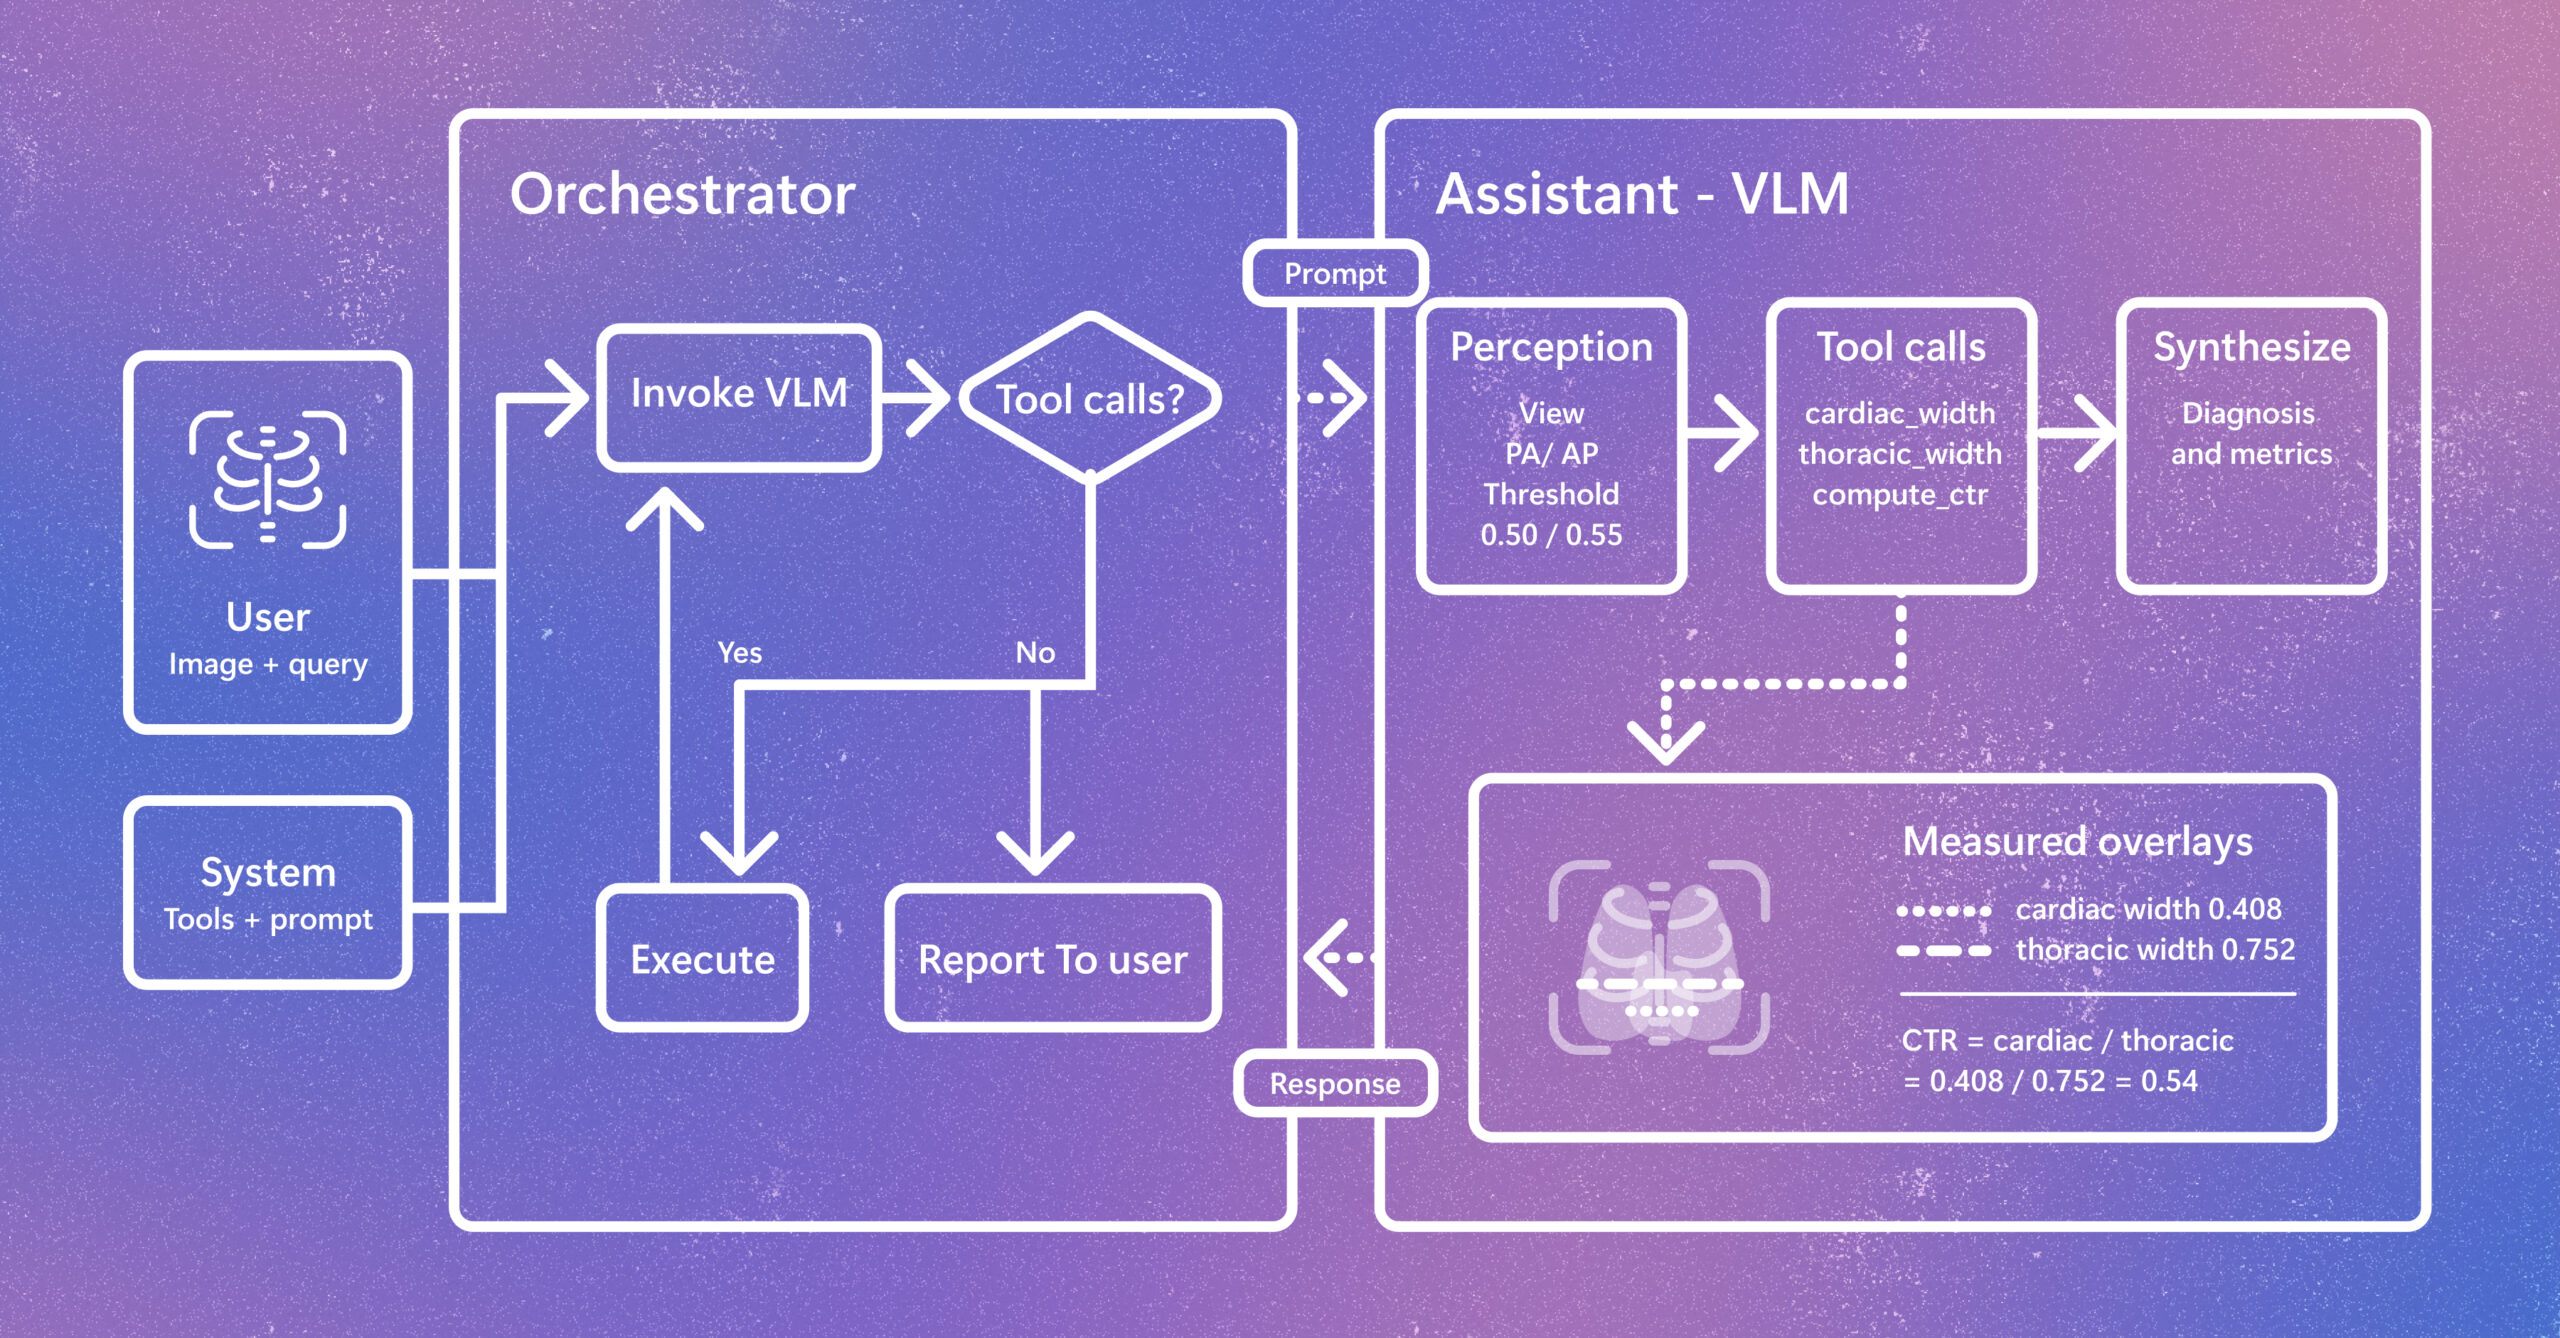
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.