Across four base/RL-teacher pairs spanning different scales, architectures, and pre-training lineages, RIDE approaches or exceeds the RL-trained teacher on every pair and is the only method whose mean does so, and it consistently outperforms output-space extrapolation, which degrades the student whenever the teacher is close to its base.
Abstract
On-policy distillation (OPD) trains a student to match the teacher's next-token distributions on the student's own trajectories and has yielded substantial empirical gains. Generalized variants allow the student to surpass the teacher by extrapolating an implicit reward in output space. The language-model head, however, attenuates this change anisotropically: much of the change encoded in the teacher's hidden states reaches the logits at a small fraction of its weight, and the sampled-token log-probability ratios on which output-space extrapolation relies inject noise that the extrapolation amplifies, making training unstable. We observe that reinforcement learning (RL) shifts a model's internal representations relative to its base checkpoint, and that the direction of this shift can be measured at every layer. Motivated by this observation, we propose RIDE (RL-Induced Direction Extrapolation), which extrapolates the RL-induced change directly in representation space: at every layer and token position, RIDE computes the residual between the teacher and its pre-RL checkpoint and regresses the student's hidden states toward targets displaced beyond the teacher along this residual. Conditioned on a sampled trajectory, this regression is equivalent to maximizing a linear directional reward defined by the residual under a quadratic penalty centered at the teacher, which makes explicit how the objective moves the student along the RL-induced direction while limiting its deviation from the teacher. Across four base/RL-teacher pairs spanning different scales, architectures, and pre-training lineages, RIDE approaches or exceeds the RL-trained teacher on every pair and is the only method whose mean does so, and it consistently outperforms output-space extrapolation, which degrades the student whenever the teacher is close to its base. Project page: https://github.com/xixixixixxxx/RIDE.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.
Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al.· IEEE Transactions on Softwar...· 178 citations· ⚡14
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.
M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al.· e-Informatica Software Engin...· 157 citations· ⚡17
Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.
What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduAug 18, 2026
A new method for surgically removing training examples from a model reveals that as datasets grow, the link between what a model learns and what it produces dissolves.
Microsoft Research Blog· microsoft.comJul 30, 2026
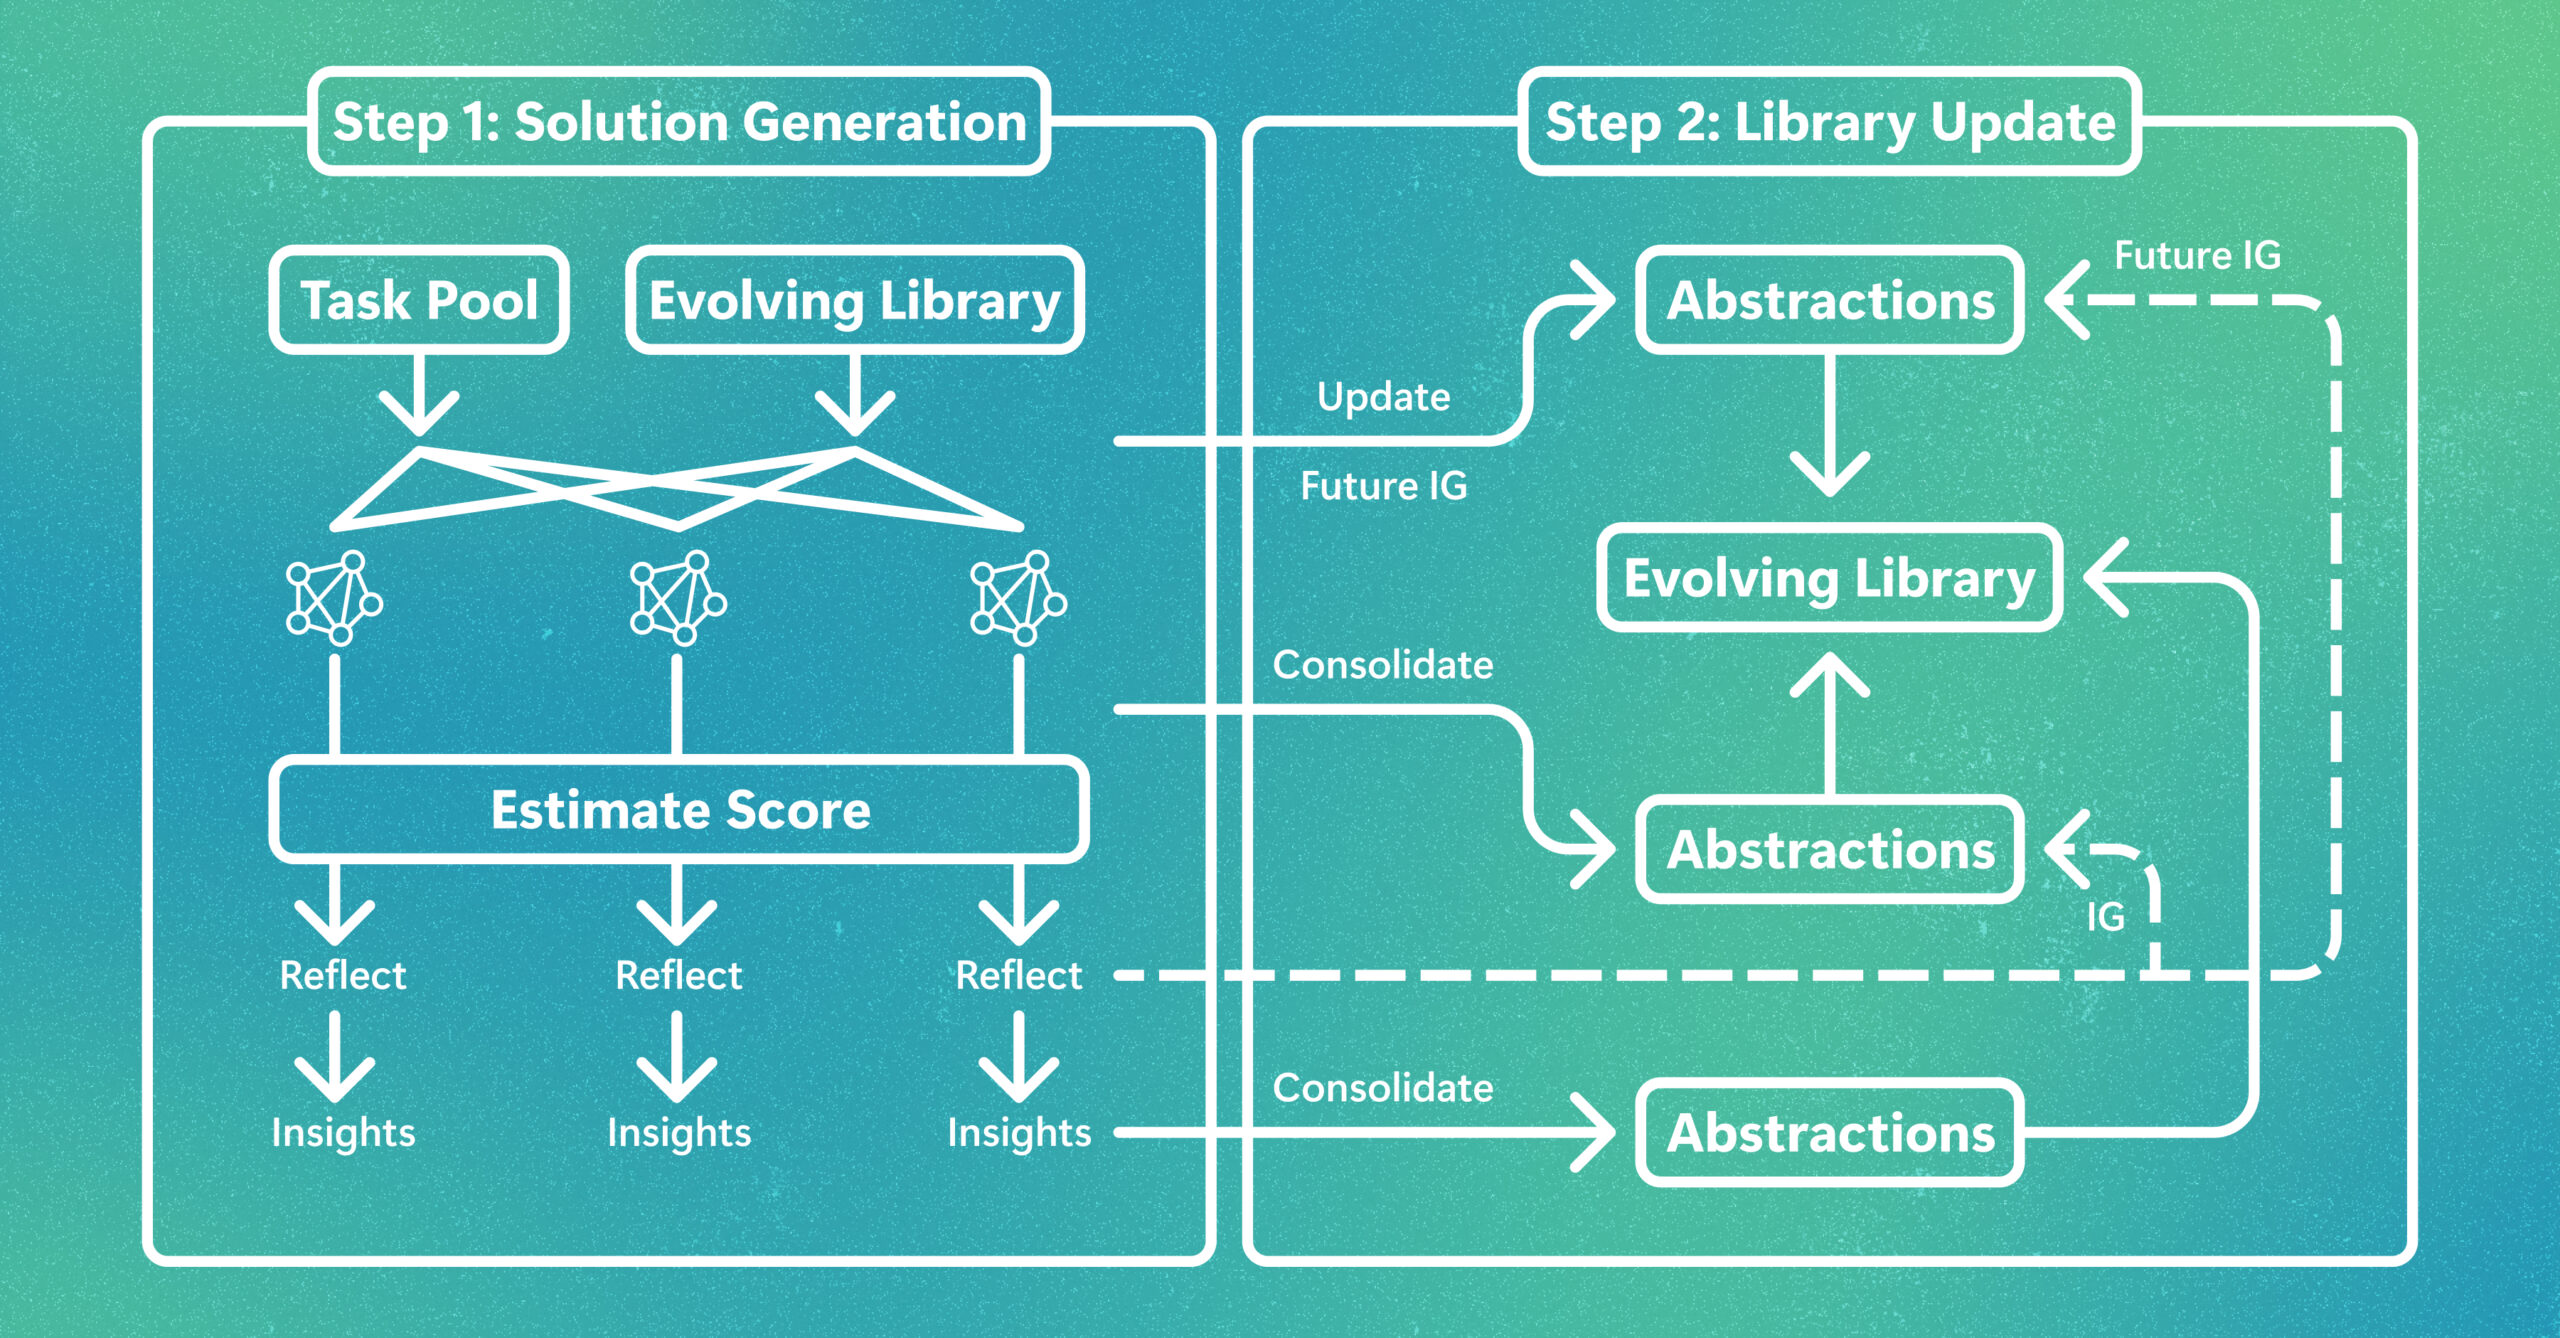
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.