Sep 2026· Zenodo (CERN European Organization for Nuclear Research)
Abstract
Reliability Beyond Accuracy in Crop Classification Benchmarks (Supplementary Materials)Introduction: Near-perfect crop-label accuracy can conceal uncertainty, perturbation sensitivity, and weak explanations. This study evaluates these reliability dimensions without treating benchmark classification as agronomic recommendation. Materials and Methods: Ten classifiers were evaluated using five matched stratified fitting, validation, and test partitions on a 2,200-record crop-label benchmark and an independent 3,810-record rice-grain benchmark. A Calibrated Selective Forest combined Random Forest, validation-fitted temperature scaling, and confidence-based abstention. Analyses included feature and component ablations, probability calibration, Gaussian input perturbations, computational cost, and explanation fidelity. Results: Mean crop-label accuracy was 99.59% for Random Forest, 99.23% for XGBoost, and 98.32% for FT-Transformer. Random Forest calibration reduced mean expected calibration error from 0.0449 to 0.0038. At a 0.95 threshold, calibrated selection retained 98.59% of predictions with 0.091% mean selective error. Under perturbations of 0.20 training standard deviations, its accuracy fell to 86.96% and selective error rose to 4.29%. On rice grains, Random Forest accuracy was 91.71%, and calibration did not improve every probability metric. Local explanation rankings were often stable despite a median neighborhood weighted R² of 0.293 under the specified local interpretable model-agnostic explanations (LIME) configuration. Conclusions: Accuracy, calibration, selective reliability, and explanation fidelity are distinct properties. The composite pipeline provides an auditable benchmark procedure, not a new learning algorithm or a validated farm recommendation system. Geographic and temporal agronomic validation remain necessary.
This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
This publication proposes a definition and a classification of agile software development approaches and analyses ten software development methods that can be characterized as being "agile" against the defined criterion.
P. Abrahamsson, O. Salo, Jussi Ronkainen et al.· arXiv.org· 727 citations· ⚡54
Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...
O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al.· Zenodo (CERN European Organi...· 465 citations
The study shows that agile practices improve both informal and formal communication, but indicates that, in larger development situations involving multiple external stakeholders, a mismatch of adequate communication mechanisms can sometimes even hinder the communication.
M. Pikkarainen, Jukka Haikara, O. Salo et al.· Empirical Software Engineeri...· 401 citations· ⚡48
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
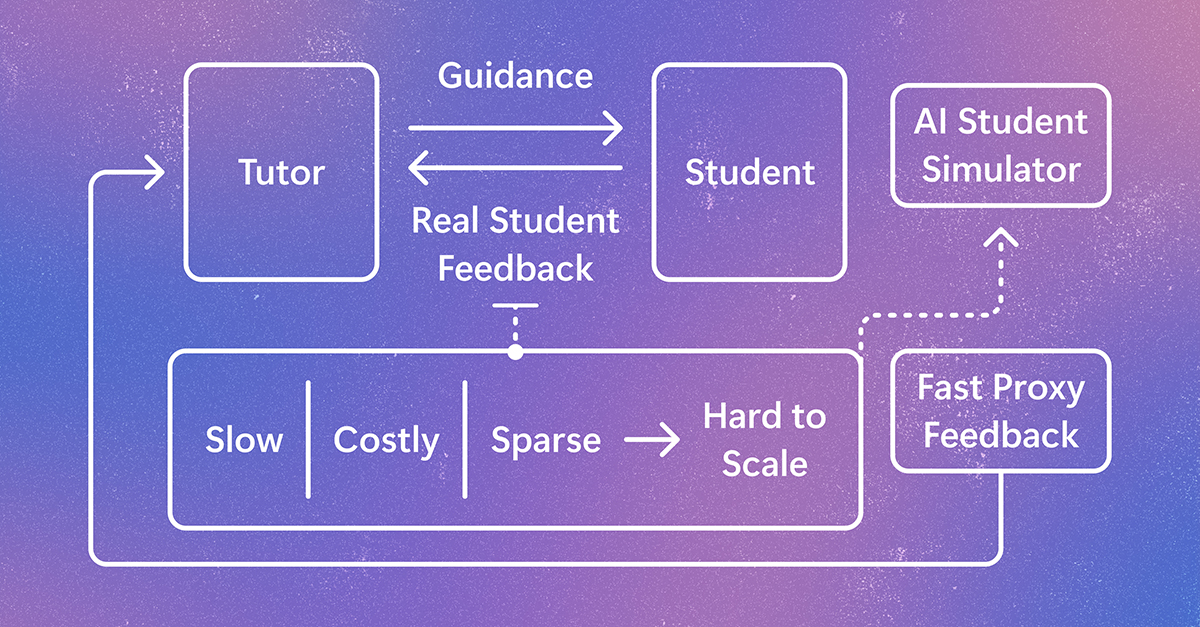
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comJul 30, 2026
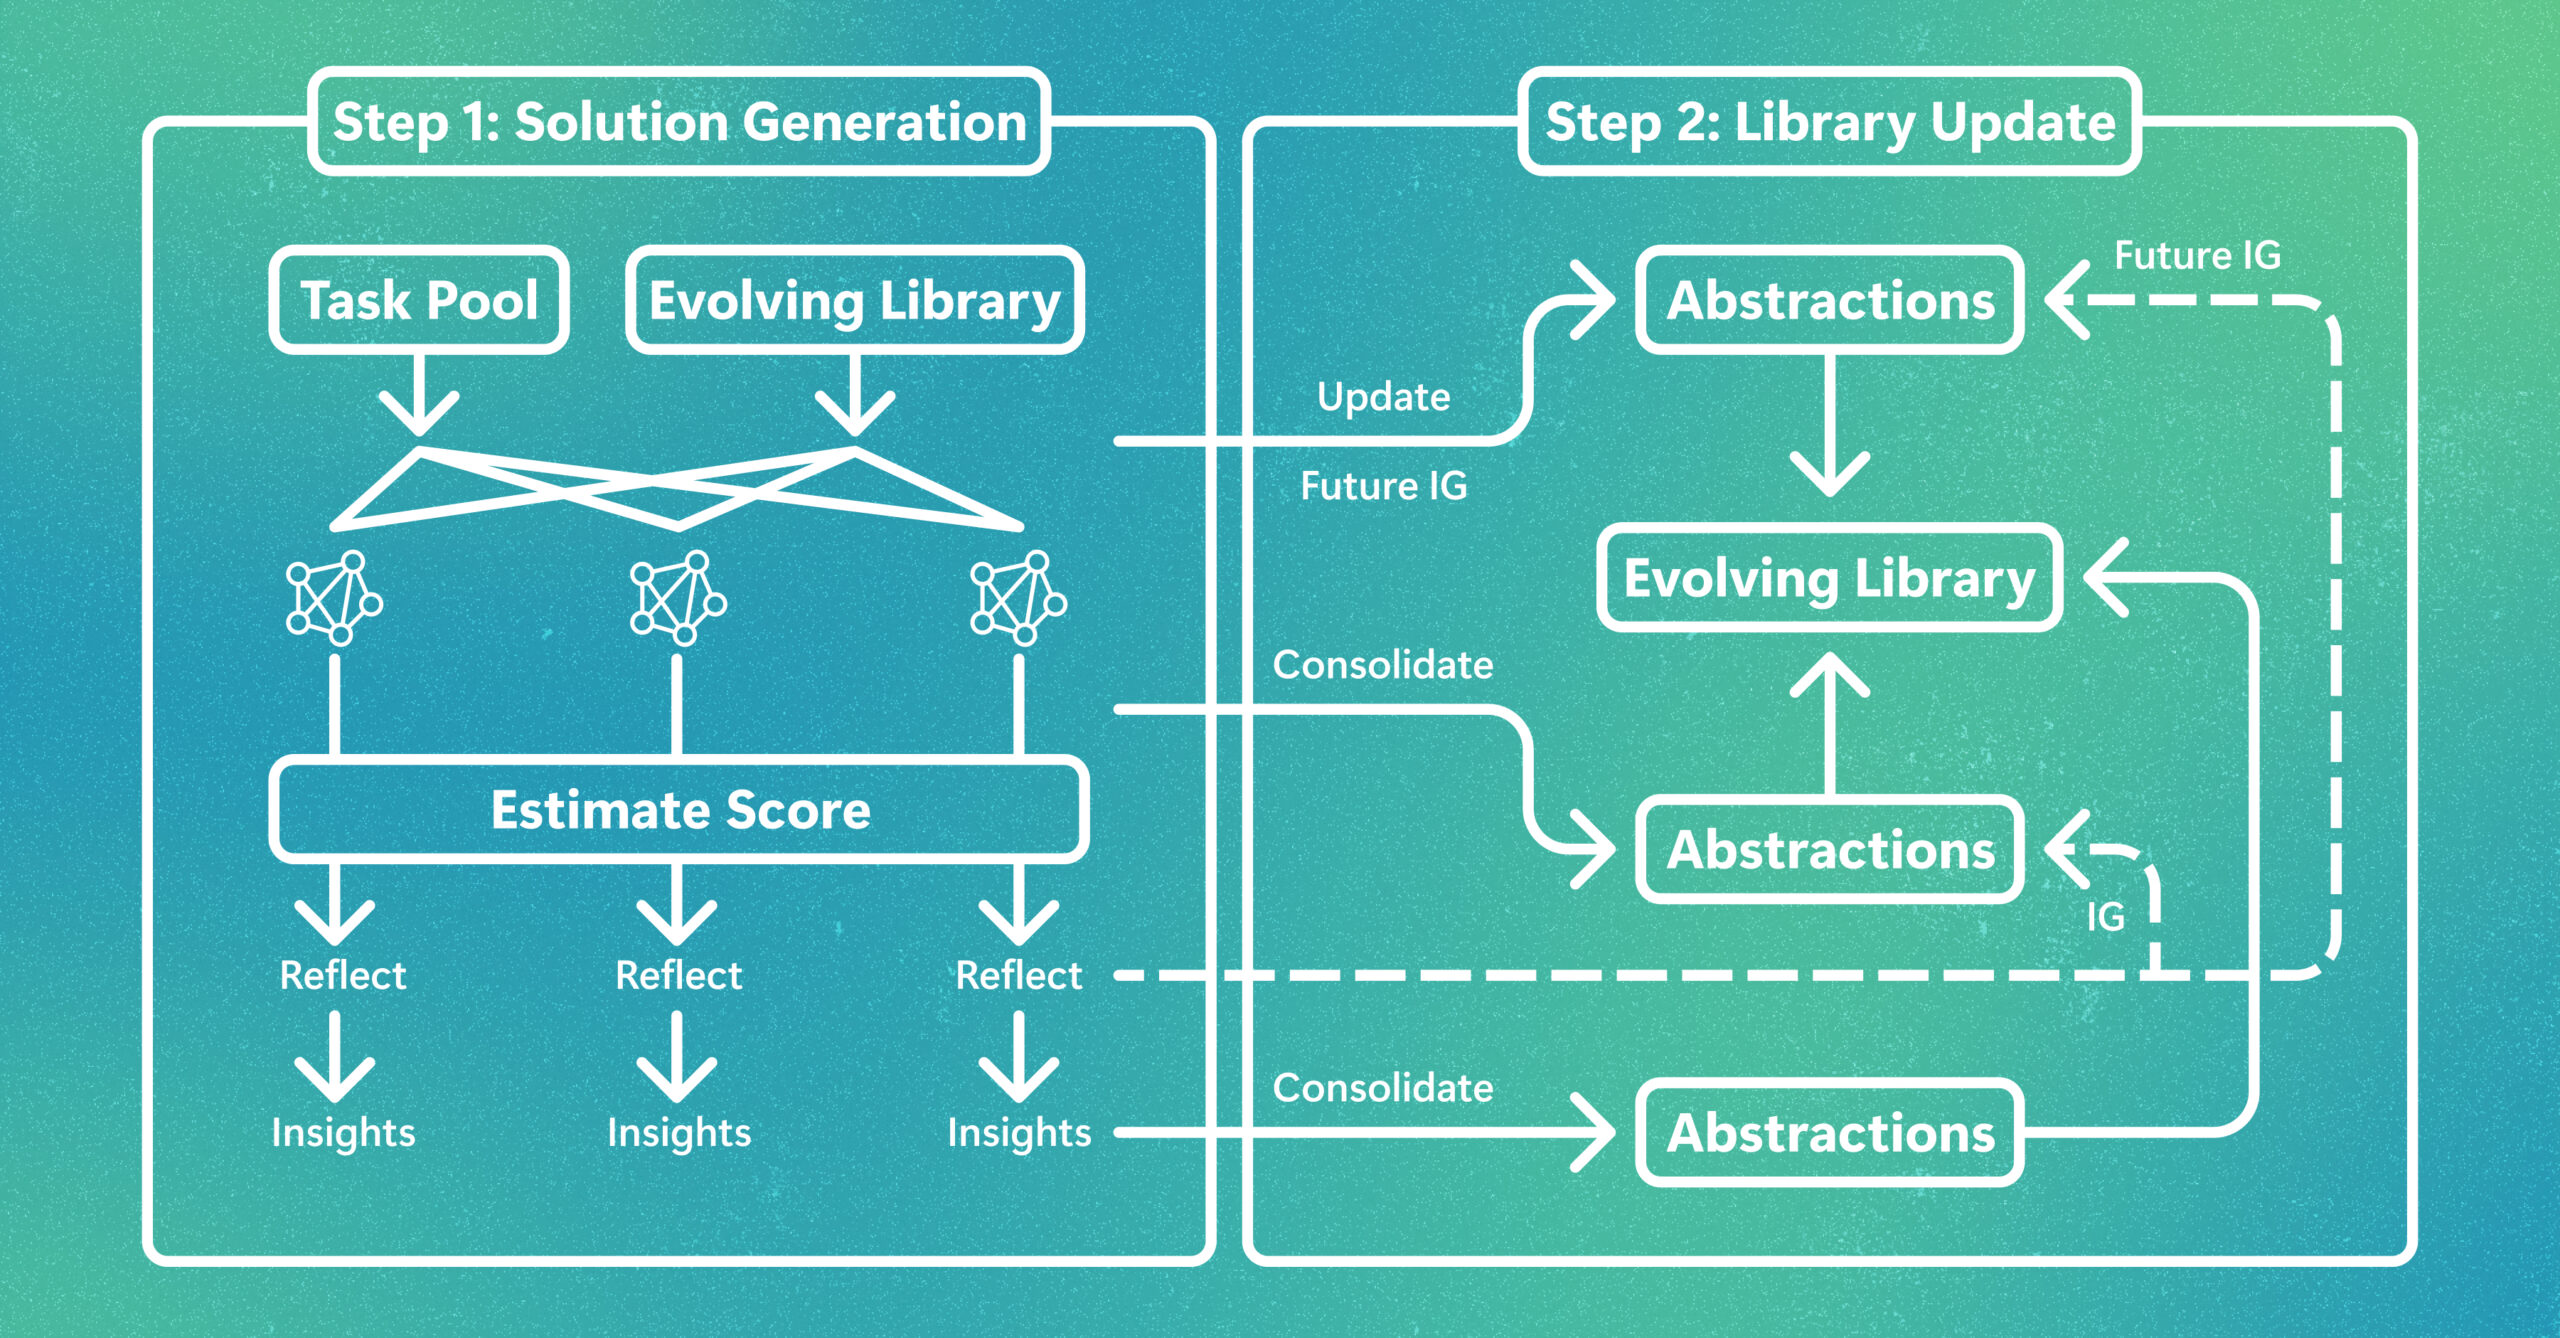
LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.