Language models increasingly serve prompts that carry private data, and secure inference under homomorphic encryption lets a client outsource the computation without revealing the prompt. Existing secure inference systems run a forward pass without consuming a token under encryption, and generating text with them requires a client round trip at every generated token. Keeping the loop on the server instead requires selecting and consuming a token under encryption, and placing bootstraps for a loop body that grows with the context. We build AR-HE, which runs the whole loop on the server, selects each token under encryption, retrieves its embedding, and writes it back into the encrypted state. The client sends one prompt and remains offline until the output. One rule places every bootstrap in the run, without search, so the bootstrap cost of a token is a formula in the context length that is known before the run starts. The schedule skips work whose result cannot reach the output, packs bootstraps that share an operand, and keeps the keys and values of past positions in an encrypted cache. With every optimization applied, generating a GPT-2 small token costs 544 seconds on one NVIDIA H100, down from 4715 seconds without optimization. The prompt step before it costs 4630 seconds. The cache alone takes a generated step from 11751 bootstraps to 1072. The formula predicts every step we measured, including steps of a model it was not derived from.

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...
O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al.· Zenodo (CERN European Organi...· 465 citations
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
An algorithm is proposed which leverages disentangled semantic factors to generate adversarial perturbation by altering controlled semantic attributes to fool the learner towards various "adversarial" targets.
Haonan Qiu, Chaowei Xiao, Lei Yang et al.· arXiv.org· 208 citations· ⚡17
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
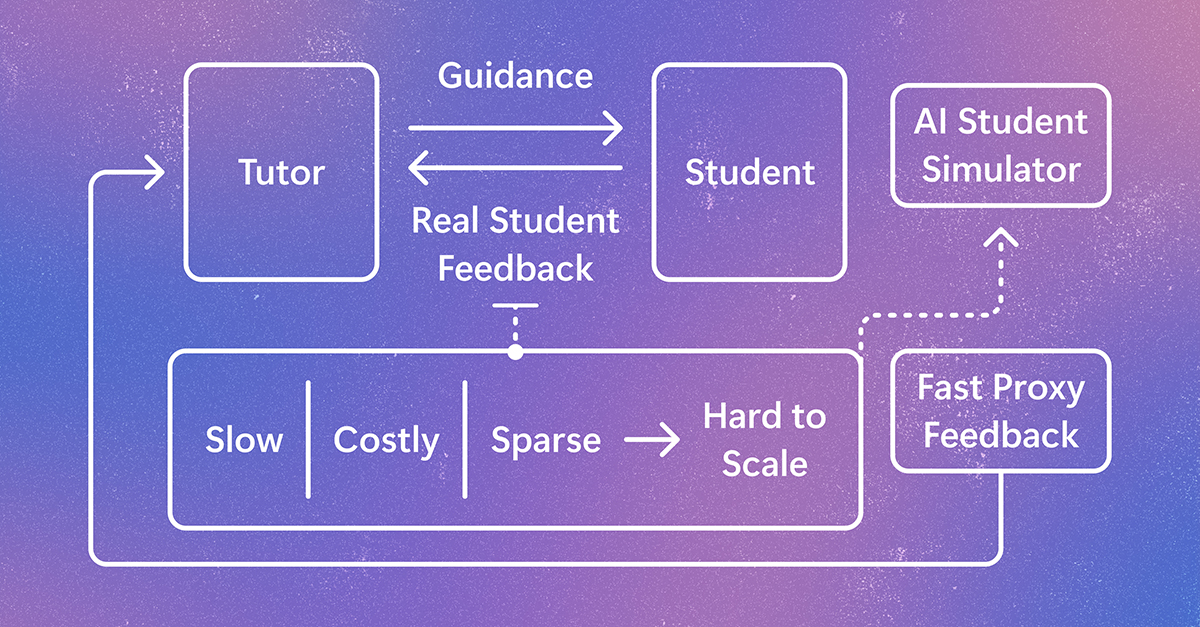
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.