With explosive data-driven application growth and increasing complexity of contemporary computing environments, conventional static cache management methods fall short more and more. This chapter discusses how reinforcement learning (RL) and deep learning (DL) models are disrupting cache optimization by making caching strategies adaptive, predictive, and context-sensitive. It first discusses basic cache structures and their shortcomings in mobile, cloud, and multicore systems. The discussion then goes on to how RL models such as Q-learning and deep Q-networks learn dynamic optimal cache replacement policies through interaction with the environment, and DL approaches such as long short-term memory, convolutional neural networks, and transformers augment prefetching and eviction prediction based on sequential and pattern recognition abilities. The chapter also points toward online versus offline learning models, feature engineering within cache-aware datasets, and simulation frameworks to measure model accuracy. Real-world case studies and benchmarks demonstrate the hard improvements in hit ratio, latency reduction, and energy efficiency. With the convergence of the power of RL and DL, the chapter highlights a new paradigm of smart cache management that can address the needs of next-generation computing workloads.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
It is found that roles of MVPs in startups were not fully aware by entrepreneurs, and entrepreneurs should consider a systematic approach to fully explore the value of MVP, as a multiple facet product (MFP).
Anh Nguyen-Duc, P. Abrahamsson· International Conference on...· 93 citations· ⚡9
It is found that what perceived as biggest challenges by software startups do vary across different life cycle stages, even though its significance decreases when the learning focuses of the startups move from problem to solution and their products mature.
Xiaofeng Wang, Henry Edison, Sohaib Shahid Bajwa et al.· International Conference on...· 62 citations· ⚡6
A comprehensive overview of how enhanced sampling methods are reshaping the field, with a particular focus on the data-driven construction of collective variables, is provided.
Kai Zhu, Enrico Trizio, Jintu Zhang et al.· Chemical Reviews· 58 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 27, 2026
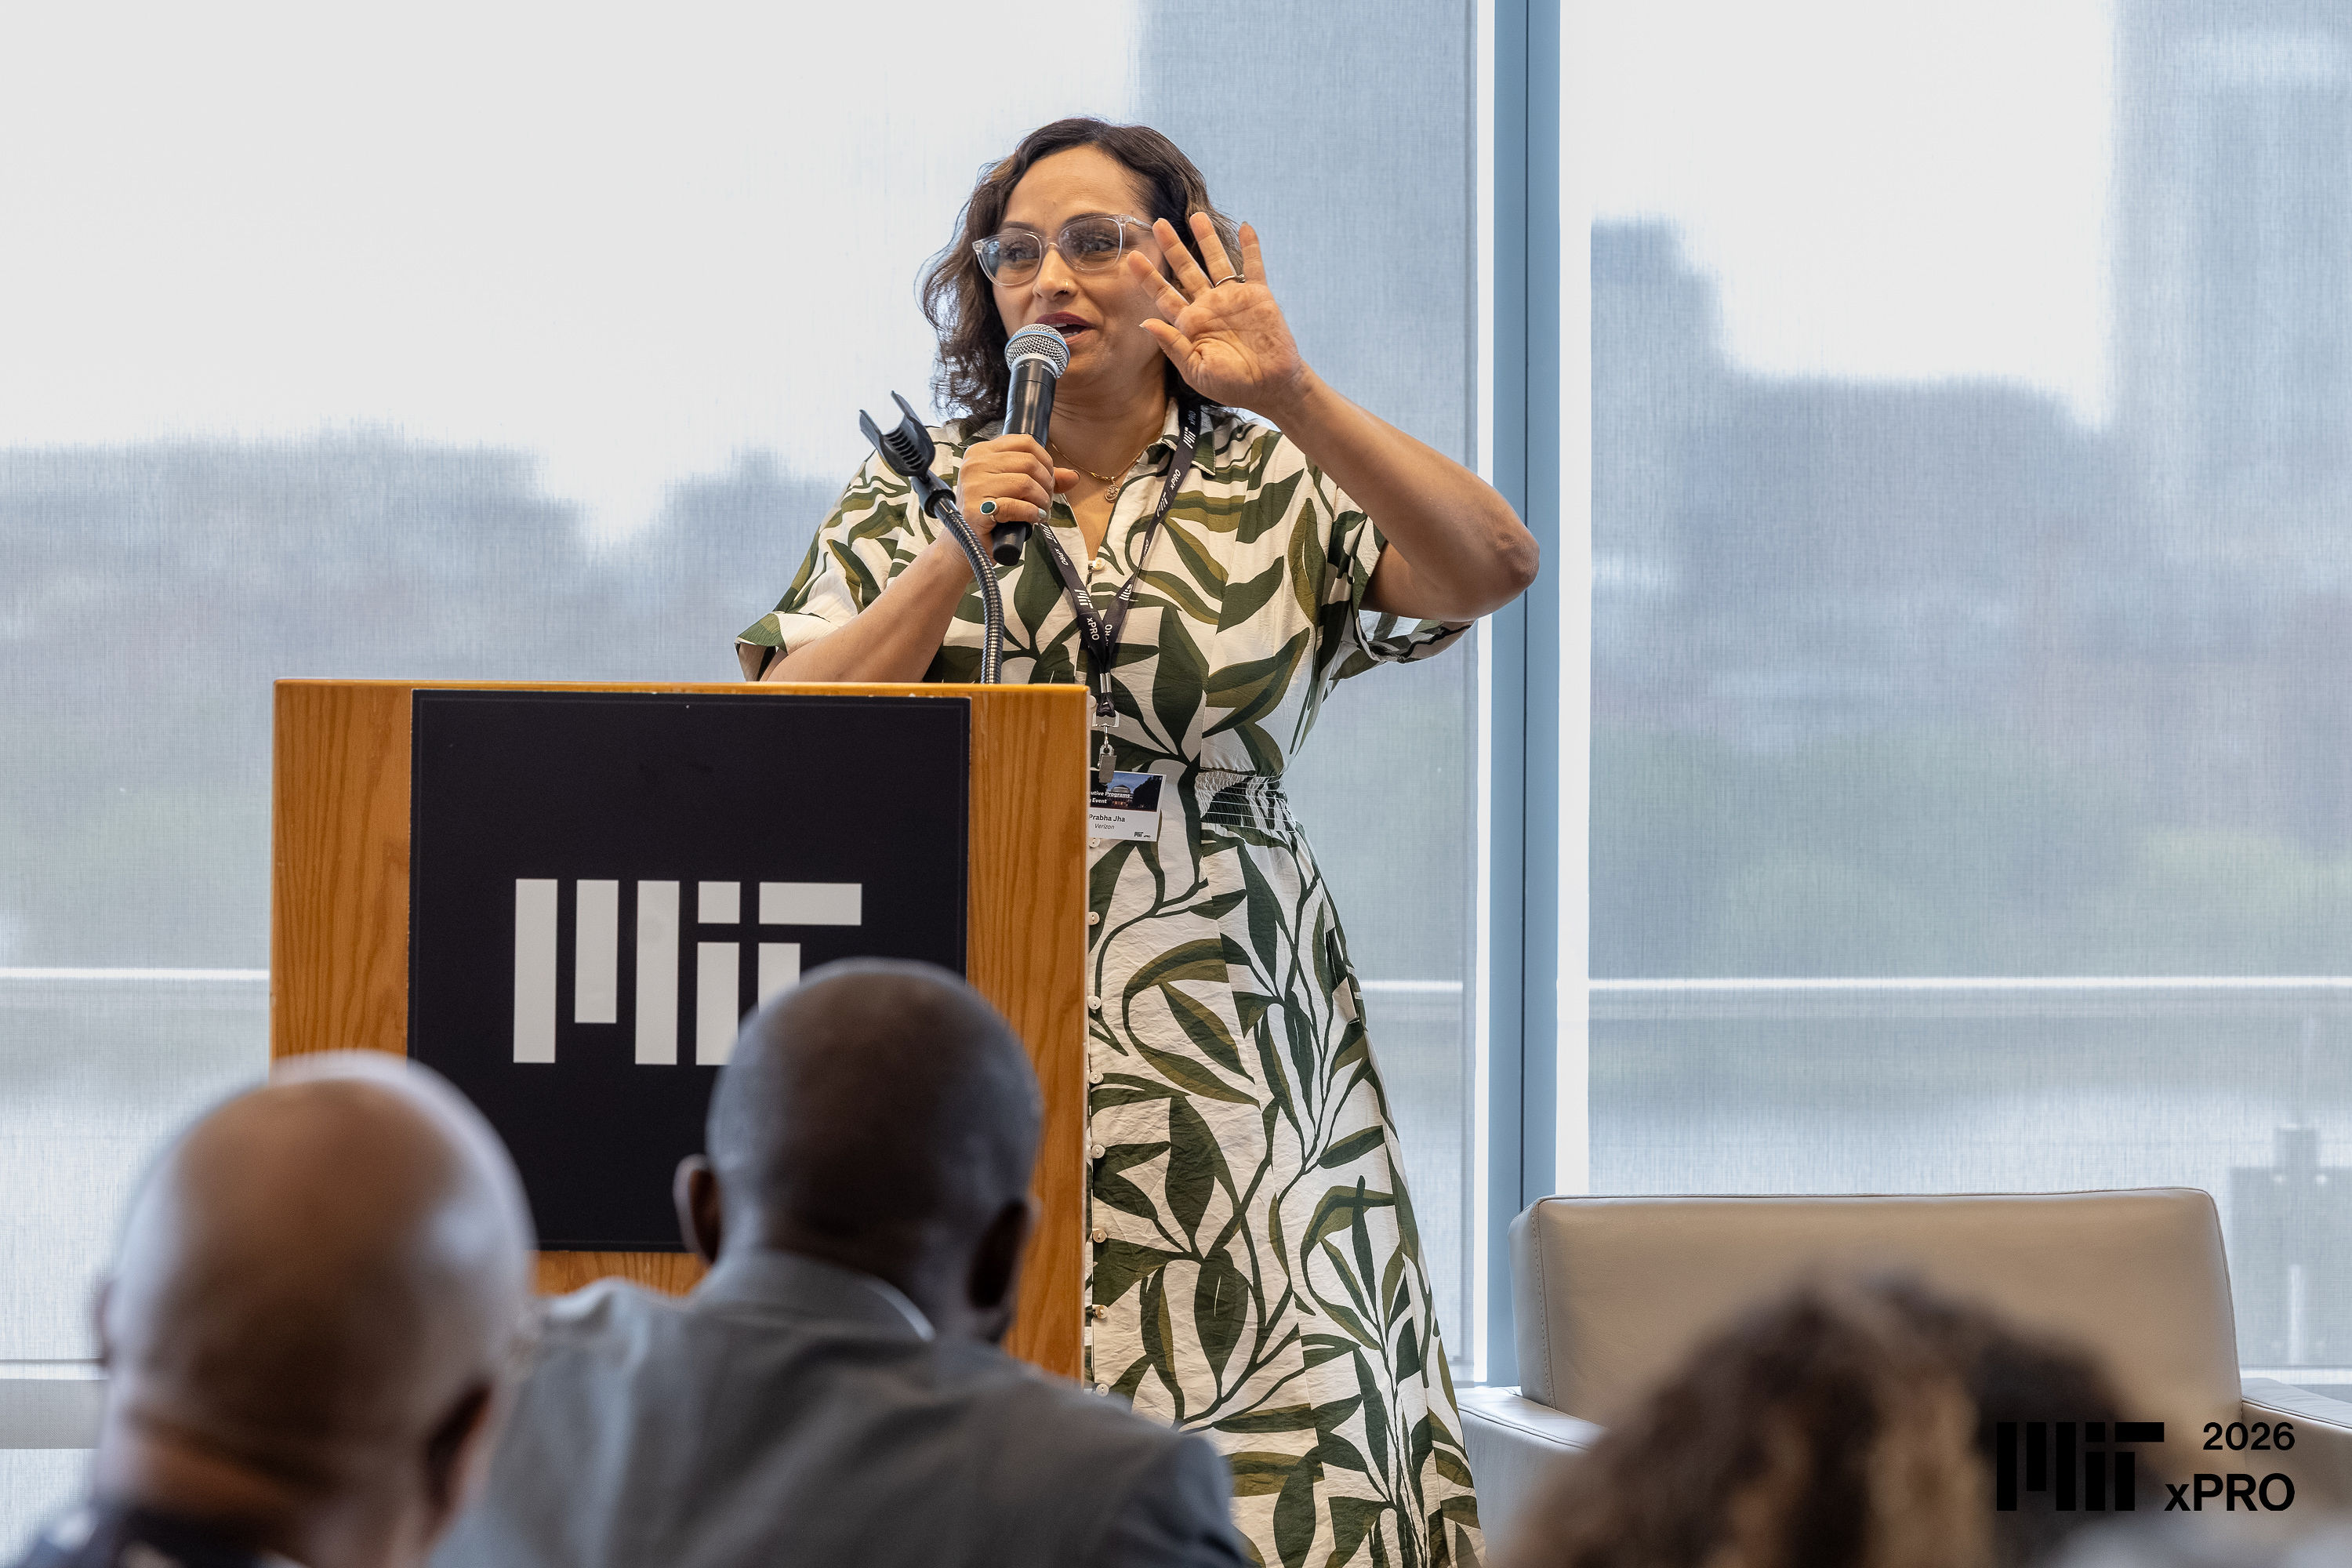
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

