Skip to content

Spectrally Targeted Muon

Oct 2026 · 0 citations · 19 references
Computer Science

Abstract

The Muon optimizer orthogonalizes each update matrix, setting all of its singular values to one, and has proven highly effective for training large language models. It remains unclear, however, whether this success comes from amplifying small singular directions that gradient descent neglects or from suppressing large, degenerate directions that disrupt training. We introduce Spectrally Targeted Muon, which orthogonalizes only the singular values above or below a threshold $\tau$, so that varying $\tau$ interpolates between normalized SGD and Muon. It isolates the relevant singular subspaces with projections computed by Newton-Schulz iteration on a shifted Gram matrix, so no SVD is needed. We evaluate these variants on the CIFAR-10 and NanoGPT speedruns, tracking the effective rank of gradient, update, and weight matrices and a new metric, the alignment of updates with the tangent space of the weight matrix's isospectral manifold. We find three things. First, the small singular values of the momentum are not noise. Orthogonalizing everything except the few largest singular values of each matrix nearly matches Muon while touching only a small fraction of the momentum, whereas orthogonalizing only the top falls well short even though it holds almost all of it. On language models every momentum singular value is far below one, so targeted orthogonalization can only amplify, and Muon wins by making directions that are too small to train on at their raw scale trainable. Second, shrinking the largest singular values is what keeps the parameter spectrum flat; this is cheap, and it is not what drives the loss. Third, AdamW differs from Muon mainly in how slowly it builds structure, which explains its slower start and why warmup helps AdamW but only hurts Muon.


View source

Similar papers

#artificial intelligence Conference Open access Jun 2018

Gibson Env: Real-World Perception for Embodied Agents

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.

F. Xia, Amir Zamir, Zhi-Yang He et al. · 1,069 citations · ⚡112
#small language model Dataset Open access Oct 2026

Socratic guiding questions in synthetic arithmetic data: matched LoRA runs (revision v2)

Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...

O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al. · 465 citations
#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60

Related blog posts

MIT News · Artificial Intelligence Oct 23, 2026

Q&A: How AI came to model the “messy” human mind

Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.

Microsoft Research Blog Oct 12, 2026

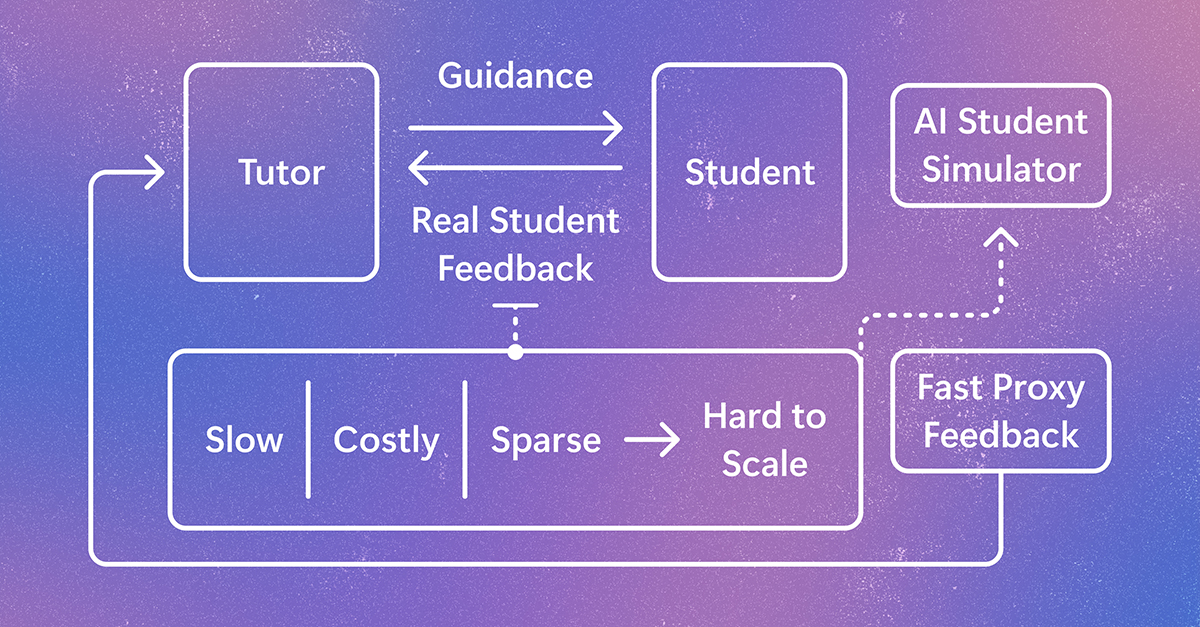
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.