SingProbe is introduced, a lightweight intrinsic runtime guard that directly reuses hidden states produced during LLM inference and operates alongside autoregressive decoding and extends this paradigm to medical generation through SingProbe-Med, which selectively activates risk-directed decoding interventions only when clinically relevant risks emerge.
Abstract
Runtime guardrails are essential for reliable large language model (LLM) deployment, yet existing approaches typically rely on independent, external models that introduce additional inference cost, delayed safety signals, and a capacity mismatch with increasingly capable base models. To address these issues, we introduce SingProbe, a lightweight intrinsic runtime guard that directly reuses hidden states produced during LLM inference and operates alongside autoregressive decoding. Within a unified framework, SingProbe continuously predicts query intent, response safety, and hallucination risk at the token level with negligible additional guardrail inference overhead, offering a"free-lunch"solution. We further introduce SingStreamBench, a benchmark designed to assess whether streaming guardrails remain inactive on benign prefixes while promptly detecting emerging unsafe content. Extensive experiments show that SingProbe achieves competitive or superior performance compared with substantially larger standalone guardrails and specialized hallucination detectors, with only $\approx$2M parameters and $<0.5\%$ extra overhead. Beyond passive detection, we also show that SingProbe scores can anticipate future generation risk and guide constrained safe decoding. We further extend this paradigm to medical generation through SingProbe-Med, which selectively activates risk-directed decoding interventions only when clinically relevant risks emerge. Together, these results demonstrate that internal model representations provide an effective and efficient interface for generation-time monitoring and control.

Modern text-to-speech (TTS) systems are rarely deployed as unchanged pre-trained models. They are often adapted through supervised fine-tuning (SFT) or preference optimization such as DPO and GRPO. This raises a practical question for audio deepfake forensics: do fingerprints learned from a foundation generator remain...
A reproducibility study of the HateBench paper, investigating whether existing hate speech detectors, typically trained on human-authored data, generalize to LLM-generated hateful content, and evaluating whether their reported weaknesses are stable over time and robust to evolving components.
Ole Becker, Tobias Jongen, Philip Kolbe et al.· 0 citations
Guardrail models are classifiers deployed to screen malicious prompts and responses in LLM-based services. To meet latency constraints, many lightweight guardrails adopt compact Transformer backbones (e.g., DeBERTa) that are trained with short context windows (typically 512 tokens) and rely on bucketed relative positio...
Xu He, Chih-Hsuan Lin, Hung-Mao Chen et al.· 0 citations
BERM is introduced, a lightweight framework that performs in-situ detection by modeling a host LLM’s internal representations extracted during prefill, adding negligible overhead and reducing incremental inference overhead to near-zero.
Maihao Guo, Chaoyang Zhao, Jin-Qiao Wang· Proceedings of the Thirty-Fi...· 1 citation
Decoding-Level Taboo is introduced, a zero-prompt diagnostic stress test that intervenes directly in logit space at runtime, forcing models out of their nominal paths by dynamically masking primary candidate tokens at word boundaries, forcing machine circumlocution.
T. Kamijo, Ori Rottenstreich, Javier Conde et al.· 0 citations
This work proposes a masked diffusion language model, fine-tuning LLaDA-8B-Instruct with a class-conditional reconstruction objective using LoRA and requiring no architectural changes beyond the base model, which leads on average rank against discriminative baselines trained on stronger backbones across seven held-out...
Gert Lek, Abele Malan, Chao-Yi Zhu et al.· 0 citations
Research Manager Mike Walker reflects on a career spanning hacker culture, cybersecurity, and AI, sharing lessons about trust, teamwork, leadership, and why solving difficult problems requires curiosity, judgment, agility—and an understanding of the rules. The post Learn the rules: The hacker mindset appeared first on Microsoft Research.
Machine-learning networks can learn without detailed instructions from a designer. Those that do may offer insight into how the brain reorganizes itself during learning.
MIT News · Artificial Intelligence· news.mit.eduSep 29, 2026
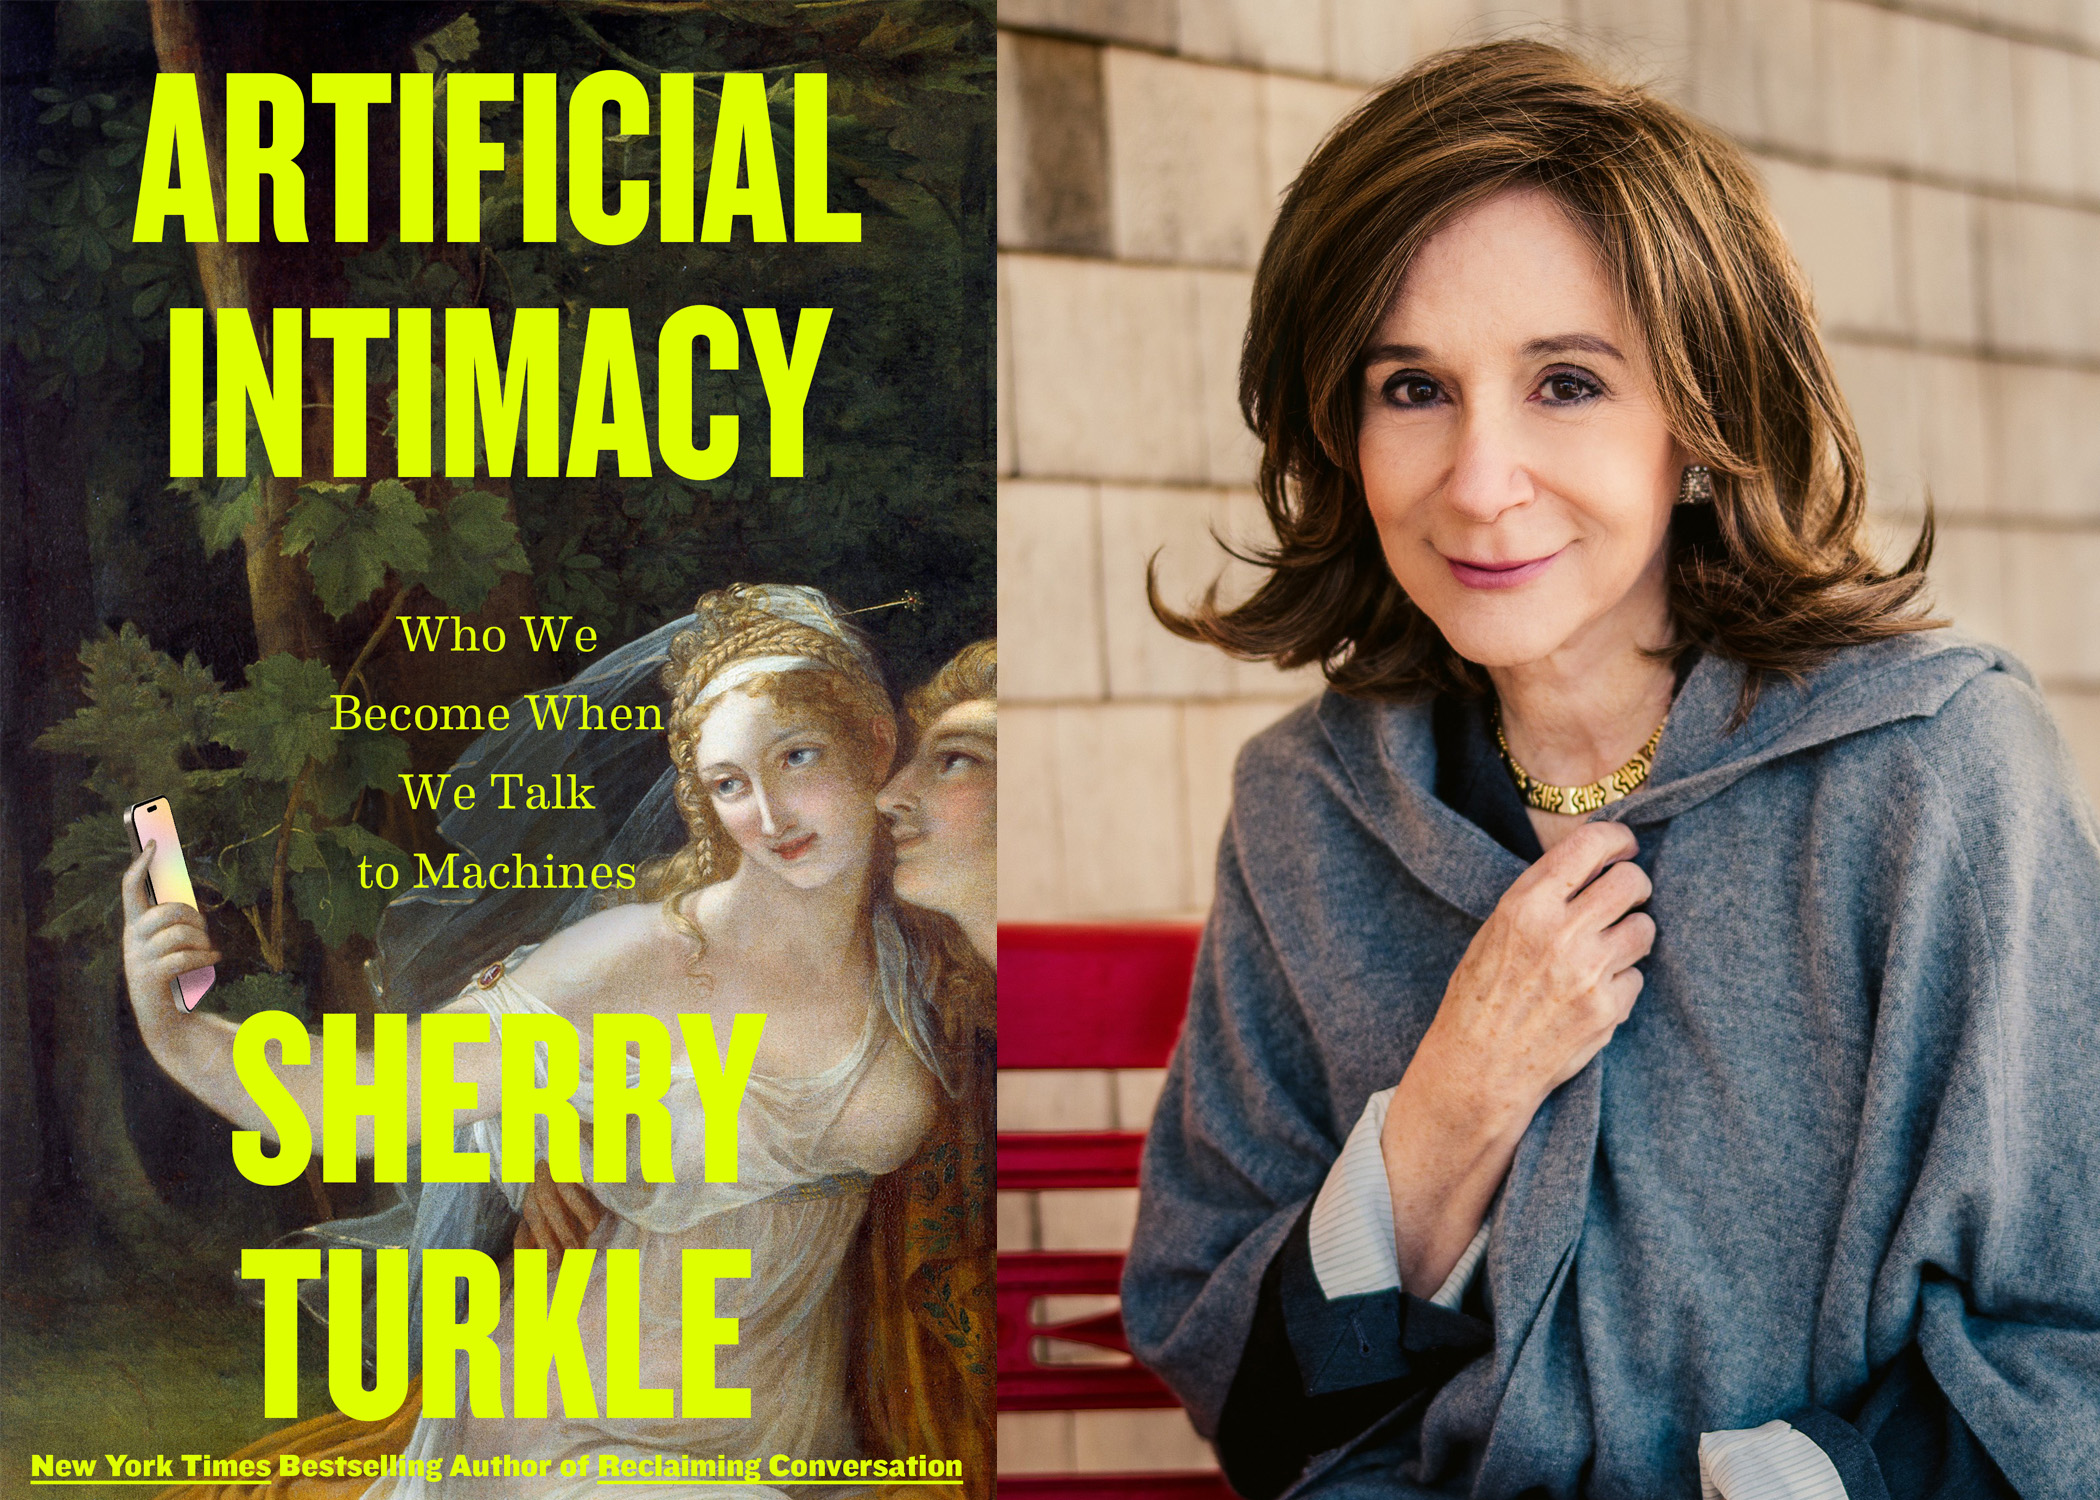
Professor Sherry Turkle’s new book, “Artificial Intimacy,” offers a withering critique of chatbots and the antisocial dynamics she believes they encourage.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.