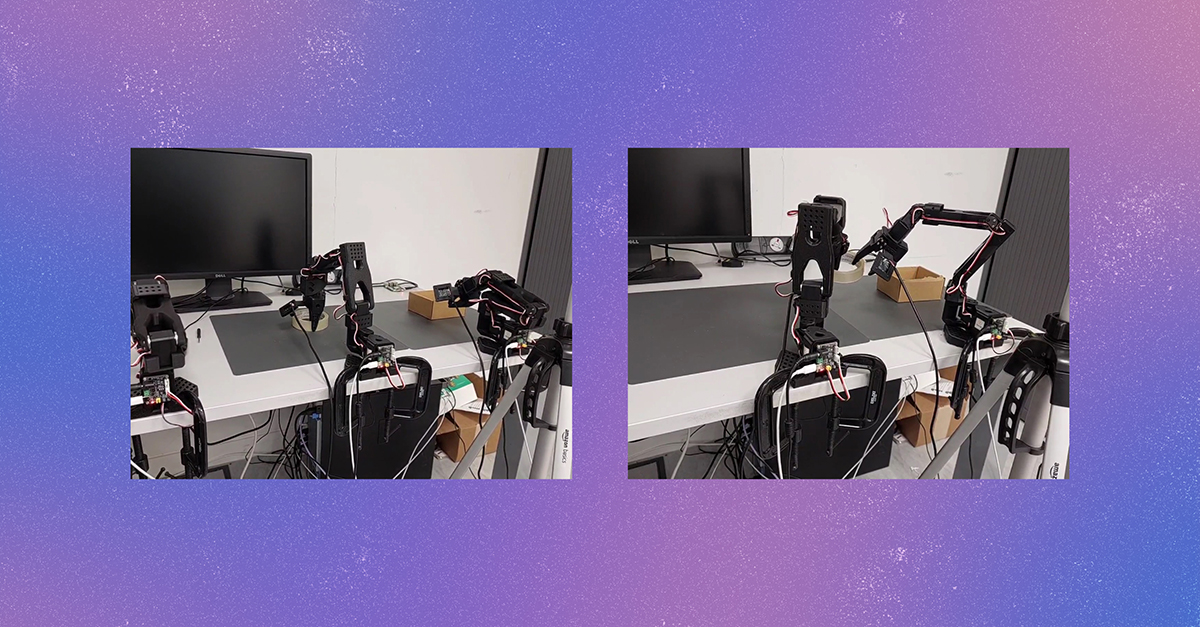
Vision-Language-Action (VLA) models have achieved impressive performance on diverse embodied tasks. However, deploying VLA models on low-power onboard devices, such as the Jetson Orin, remains challenging due to their high computational complexity, which leads to substantial inference latency and low control frequency. Asynchronous inference can partially mask this latency by parallelizing action execution and subsequent inference, but it introduces two critical issues: perception-execution misalignment and long reaction time. In this paper, we propose Jetson-PI, a method for efficient VLA deployment on onboard devices via Foresight-Aligned Asynchronous Correction. To address misalignment, we train a lightweight future correction module that predicts future environment representation conditioned on committed actions, enabling the action expert to directly predict actions from the future time step. To reduce reaction time, we introduce confidence-based scheduling optimization that adaptively balances VLM and action expert invocations, complemented by system-level accelerations including CUDA graph reuse, GPU-resident intermediate buffering, and flow unrolling. Extensive experiments demonstrate that Jetson-PI achieves 8.66x and 5.41x improvements in control frequency compared with naive PyTorch and vla.cpp on NVIDIA Jetson Orin, while outperforming VLASH by 14.8\% in average success rate on the LIBERO benchmark. The code of our asynchronous algorithm is available on https://github.com/PKU-SEC-Lab/Jetson-PI, and our efficient llama.cpp-based inference engine is available on https://github.com/PKU-SEC-Lab/Jetson-PI-Edge.
Comprehensive evaluations on OpenVLA and RDT across LIBERO and ManiSkill benchmarks show that SpecVLA reduces end-to-end latency significantly while preserving task success rate, and achieves real-time robotic manipulation with both high efficiency and reliability.
Chunyu Qi, Zhuoran Song, Jian Weng et al.· 0 citations
This paper proposes FutureRTC, a plug-and-play adaptation framework that predicts execution-time observations and states for asynchronous VLA control without modifying the underlying policy, and introduces a policy consistency loss to align the action chunks generated from predicted contexts with those produced under t...
Hai Jiang, Yi Zou, Binbin Liang et al.· arXiv.org· 1 citation
FluxVLA Engine is presented, an open, configuration-driven platform that turns heterogeneous embodied-policy components into a reproducible data-to-deployment workflow and targets the engineering bottlenecks separating promising embodied-learning algorithms from reproducible evaluation and dependable deployment.
Yin-Hao Li, Wei-Xin Mao, Zi-Han Lan et al.· 3 citations
This work instantiates Real-Time EXPO-FT, an RL framework for finetuning real-time VLA policies that meets the real-time control requirements of dynamic real-world manipulation, demonstrating rapid, sample-efficient adaptation to challenging real-world dynamics.
Perry Dong, Kuo-Han Hung, D. Sadigh et al.· 1 citation
NebulaVLA is presented, an asynchronous dual-frequency architecture that decouples high-level semantic reasoning from low-level action control, optimizing computational resources and modularity and introduces GESTURE-7, a unified language-grounded action representation.
Congyu Zhao, Shuai Tian, Xu Zhang et al.· 0 citations
Factory work is a promising early scenario for embodied AI: assigning repetitive manual jobs to robots has clear economic payoff, and a structured station keeps the jobs tractable for current policies. Vision-Language-Action (VLA) models now dominate as the policy paradigm for these robots. The inference latency of VLA...
Kai-Jun Zhou, Zhi-Yang Li, Le Chen et al.· 0 citations
Robots are getting smarter, but how can their hardware match that growth? New Microsoft Research findings show that moving AI inference beyond the robot can improve task success, boost efficiency, and support more advanced physical AI workloads. The post Offloaded inference for real-world physical AI robotics appeared first on Microsoft Research.