Evidence for reliable cross-subject five-vowel decoding is limited within this dataset and protocol, and the benchmark provides a reproducible chain from source rows to retained epochs, predictions, participant-level metrics, multiplicity-adjusted inference, and bounded diagnostic analyses.
Abstract
Objective. We evaluated cross-subject five-vowel perception decoding from auditory-evoked EEG with explicit trial definitions, participant-grouped validation, complete prediction coverage, and participant-level inference. Approach. We parsed all Study 2 event tables from OpenNeuro ds006104 version 1.0.1 and analysed the consonant–vowel (CV) pair task. Marker–stimulus pairing converted 7680 event rows into 3840 independent CV trials. Excluding active-condition trials left 1280 eligible control trials. A 400 μV maximum across-channel peak-to-peak criterion rejected 186 epochs, retaining 1094 epochs from 16 participants and 61 EEG channels. Thirteen unique implementations underwent leave-one-subject-out testing. Participant metrics came from 36 102 trial predictions across 33 complete replicas. Descriptive analyses assessed deep-model stability across five seeds, class-resolved errors, and retention sensitivity. An exploratory MDM analysis comprised 9616 genuine model refits across training cohorts of 3–15 participants. Main results. Two independent cohort-construction implementations preserved the same ordered 1094 trials and labels (maximum tensor difference, 4×10⁻¹² V). Thus, corrected accounting changed the reported exclusion decomposition but not the analysed cohort or model inputs. Random Forest achieved the highest mean balanced accuracy: 21.474% (95% participant-bootstrap interval, 19.526%–23.482%; five-class chance, 20%). The one-sided Wilcoxon, Bonferroni-adjusted, and sign-flip p values were 0.090 897, 1.000 000, and 0.092 791, respectively. All 13 implementations remained non-significant after multiplicity correction. Deep-architecture means were near chance, with substantial within-participant seed ranges and low trial-label agreement for several architectures. Across 3–15 training participants, refitted MDM means ranged from 20.553% to 20.922%, without a monotonic increase. Significance. This dataset and protocol provide limited evidence for cross-subject five-vowel decoding. Explicit trial units, participant-grouped validation, complete seed reporting, prediction-level traceability, and multiplicity-adjusted inference sharpen the interpretation of small-cohort EEG benchmarks.
Neural speech tracking is stronger for attended speech, yet its common correlation-based readout is scale invariant, so interpreting this effect only as response gain is incomplete. We tested whether attention improves representational fidelity, defined here as scale-invariant agreement between a speech envelope and it...
This study presents a transparent baseline investigation of a multi-class imagined speech EEG dataset under a strictly subject-independent evaluation framework, providing a strong basis for future brain-computer interface studies targeting improved cross-subject generalization in EEG-based imagined speech decoding.
Frederik Møllskov Trier, Xiao-Peng Mao, S. Puthusserypady· 0 citations
Objective: To compare electroencephalography (EEG)-based subject-identification and open-set rejection performance across experimental paradigms while examining model robustness and cross-session generalization. Methods: The M3CV database was analyzed across resting state, transient sensory stimulation, steady-state se...
Cai Chen, Dan-Yang Lv, Jia-Zheng Sun et al.· Italian National Conference...· 0 citations
Non-invasive decoding of rapidly evolving cognitive and motor states is limited by trade-offs between temporal precision, spatial fidelity and tolerance to natural movement. We present a modality-matched benchmarking framework that evaluates optically pumped magnetometer magnetoencephalography (OPM-MEG) against electro...
Objective electrophysiological markers are often proposed for speech-in-noise assessment, but their validation targets are not always explicit: a marker may calibrate with intelligibility, distinguish acoustic conditions, decode attention, or predict an individual speech reception threshold (SRT). We used three public...
Li Guo, Yang Li, Jun-Lin Wang et al.· Hearing Research· 0 citations
Decoding perceived speech from non-invasive brain recordings has garnered significant attention in recent years due to its wide range of potential applications. However, existing methods face considerable challenges in cross-subject decoding, primarily due to limited generalizability and the absence of explicit mechani...
Ao-Ke Zhang, Bo Wang, Xihong Wu et al.· 1 citation· ⚡1
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
A new machine-learning framework aims to improve the success rate of computational protein design while moving away from results that reproduce sequences found in nature.
Microsoft Research Blog· microsoft.comAug 11, 2026
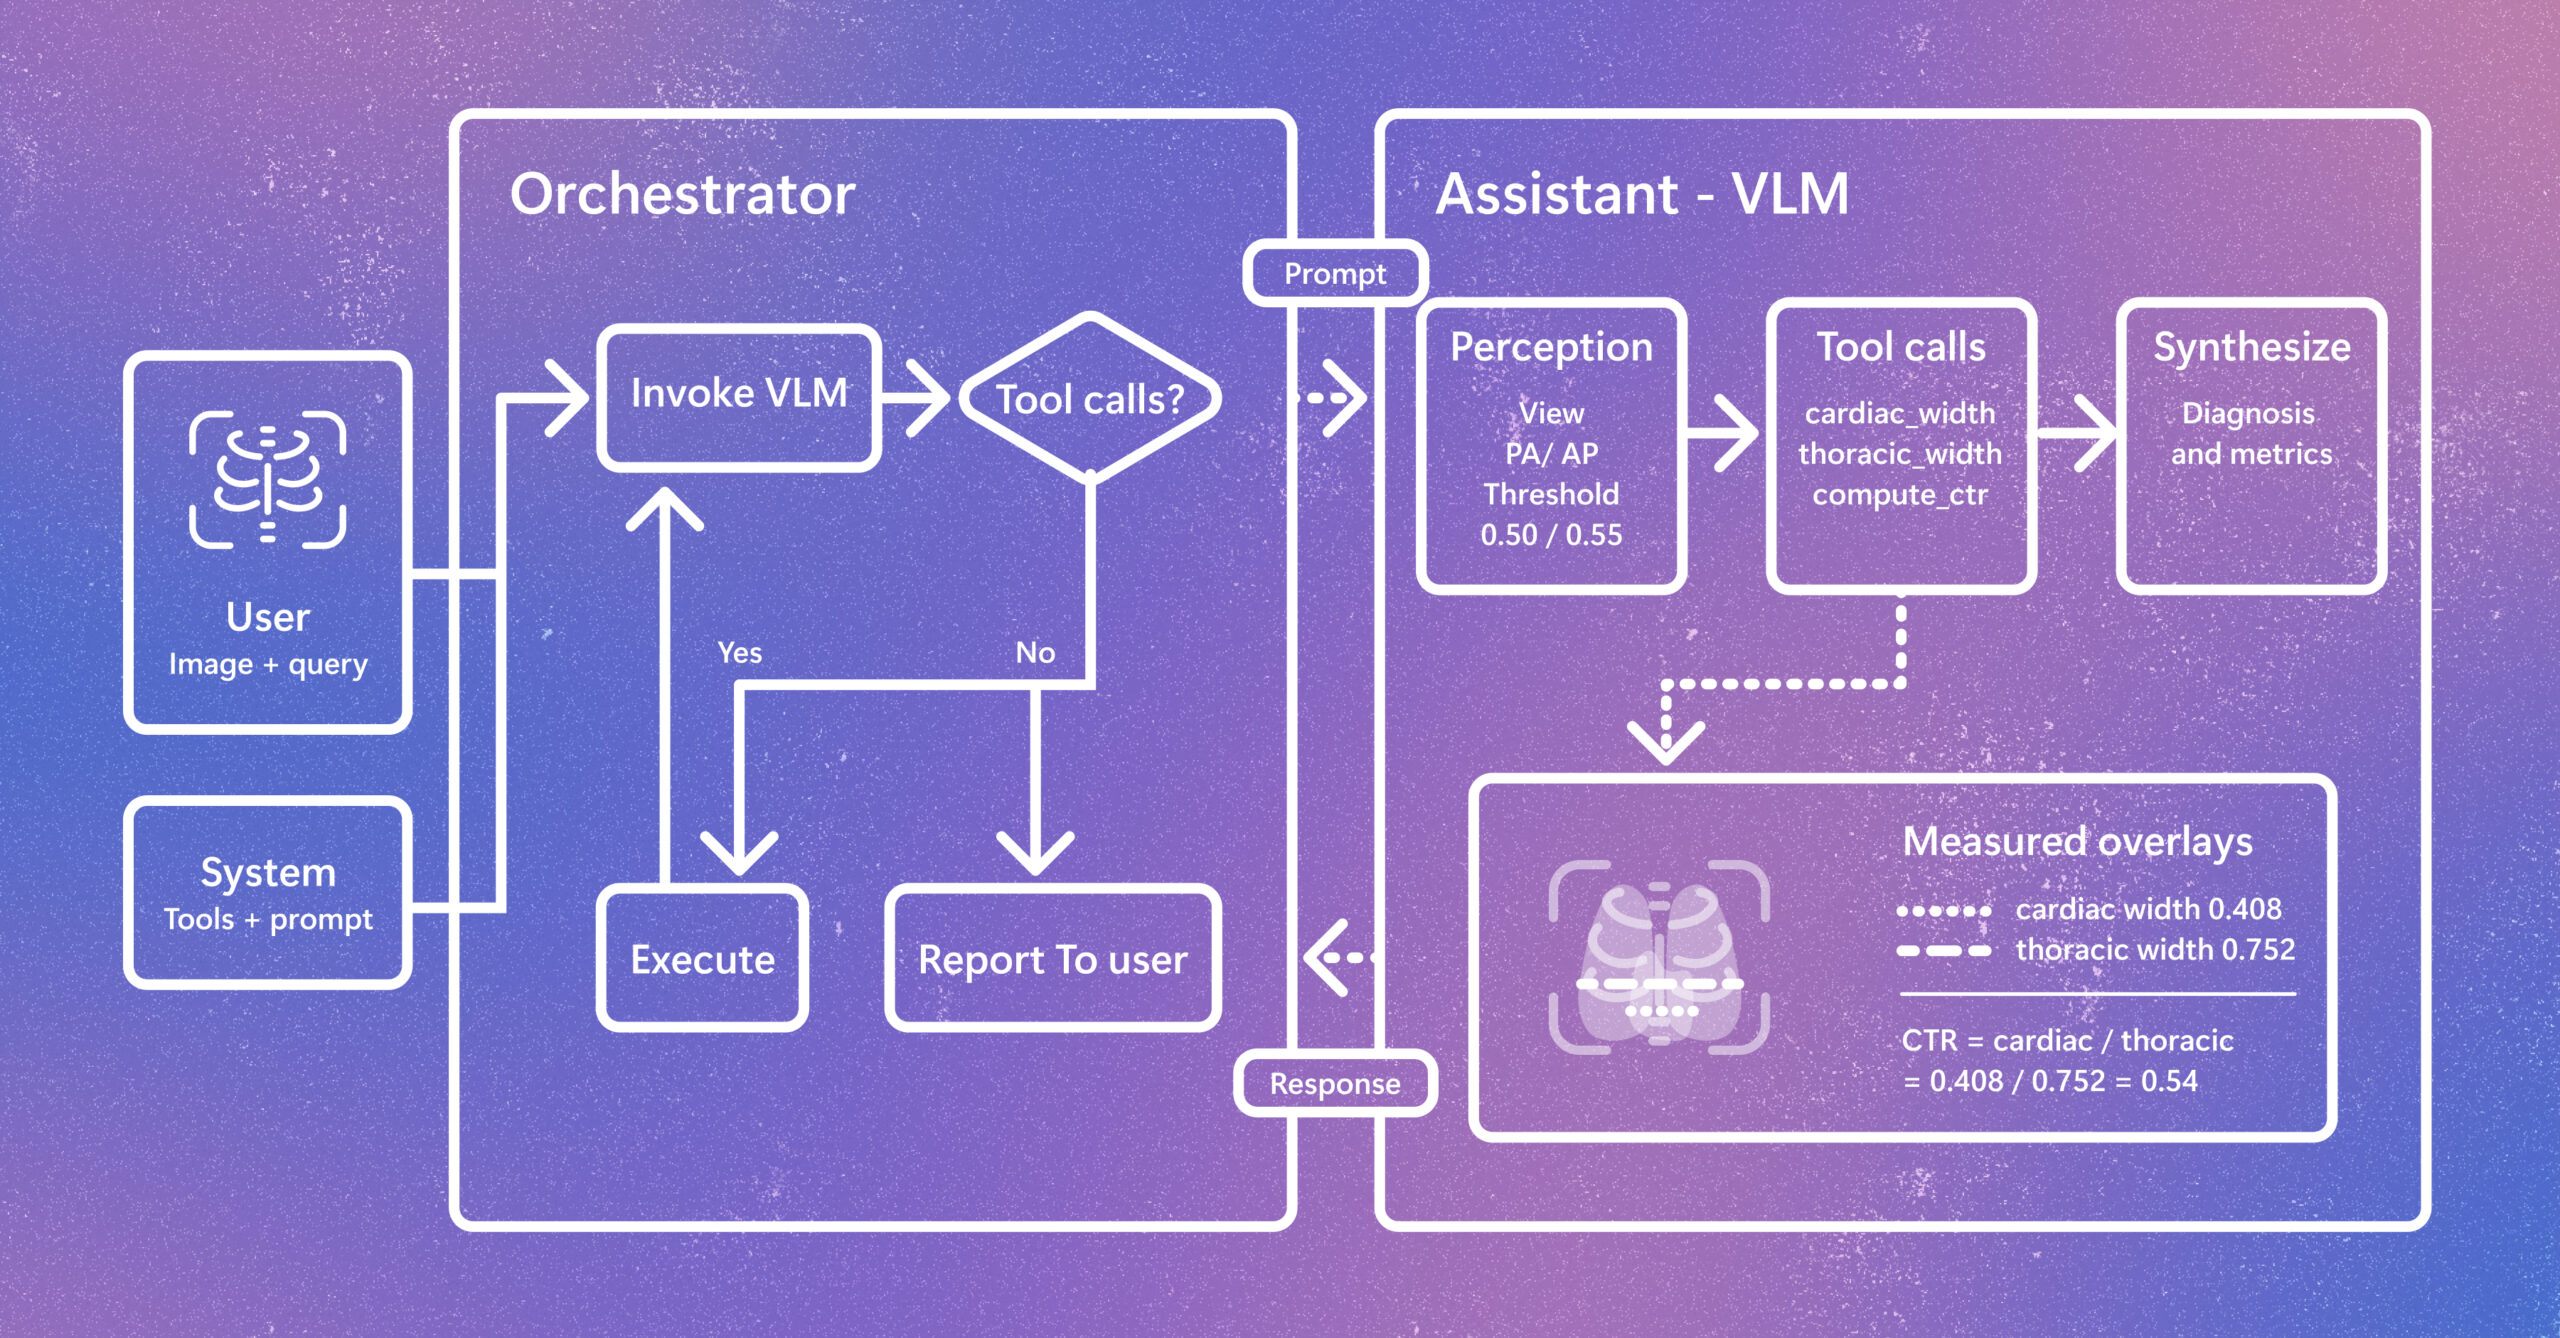
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.