Results indicate that near-optimal performance can be achieved even when rationales are provided for only a subset of the training data, and that shorter explanations are often sufficient.
Abstract
This paper investigates an efficient approach for distilling Large Language Models (LLMs) into smaller, application-specific models using zero-shot Chain of Thought (CoT) rationale generation and Optimization by Prompting (OPRO). To address the challenges of deploying computationally intensive generative AI for narrow tasks or resource-constrained environments, the approach leverages LLM reasoning capabilities to generate both labels and natural language explanations for unlabeled data. By reducing reliance on human-generated annotations, the approach substantially lowers annotation requirements and prompting costs while maintaining comparable performance in the evaluated settings. We formulate distillation as a multi-task learning problem in which student models are trained to jointly predict labels and learn from teacher-generated rationales, with the goal of improving data efficiency and generalization. Building on established zero-shot Chain of Thought (CoT) prompting and the OPRO prompt optimization technique, we use teacher-generated rationales to reduce annotation token requirements and examine the associated performance and efficiency gains. Additionally, we systematically investigate how explanation properties affect distillation efficiency. Across natural language inference and question answering benchmarks, results indicate that near-optimal performance can be achieved even when rationales are provided for only a subset of the training data, and that shorter explanations are often sufficient. These findings provide practical insights into the trade-offs between rationale generation cost and student model performance. Overall, this work contributes empirical evidence on the effectiveness and cost characteristics of rationale-based distillation for training compact, task-specific language models with minimal human intervention.
SOLID is proposed, a novel framework for self-improving OR language models without verified answers or external evaluators that improves solution accuracy for both general-purpose and OR-tuned models over outcome-only group-relative training.
Rui-Chen Zhu, Ming-Long Cao, Chen-Yu Zhou et al.· 0 citations
On-policy distillation (OPD) combines student-generated rollouts with dense token-level supervision from a teacher. Existing work has mainly studied its algorithmic behavior, leaving the role of training data unclear. We examine this role at the data-minimal limit by training on a single query. One-shot OPD keeps impro...
Large Language Models (LLMs) are increasingly used to enrich user queries in information retrieval (IR) so that a standard retriever such as BM25 can bridge vocabulary gaps with the target corpus. Any single LLM, however, is limited by its training data and architectural biases, and its enrichment behavior depends on h...
Tzu-I Ho, Yung-Yu Shih, Shang-Yu Su et al.· 0 citations
Self-Play Search Distillation (SPSD), a framework for generating superhuman synthetic data via self-play of MuZero-like networks trained on board games, offers an annotation-efficient way to create high-quality synthetic data for improving LLM performance in reasoning tasks.
Lorenzo Molfetta, Wai-Chung Kwan, Giacomo Frisoni et al.· 0 citations
While large language models (LLMs) have achieved impressive gains in commonsense reasoning, they often fall into “associative shortcuts,” failing to distinguish correct answers from plausible but constraint-violating hard negatives. This reliance on semantic priors rather than specific situational constraints limits th...
Xin Guan, Jiu-Xin Cao, Biwei Cao et al.· IEEE Transactions on Audio,...· 0 citations
Tabular foundation models (TFMs) achieve strong predictive performance through in-context learning, yet repeatedly conditioning on labeled data makes inference expensive. Knowledge distillation can reduce this cost by transferring their predictive ability to lightweight, dataset-specific students. However, the dependen...
Minho Jeong, Dooho Lee, Jin-Mo Lee et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Microsoft Research Blog· microsoft.comOct 22, 2026
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 19, 2026
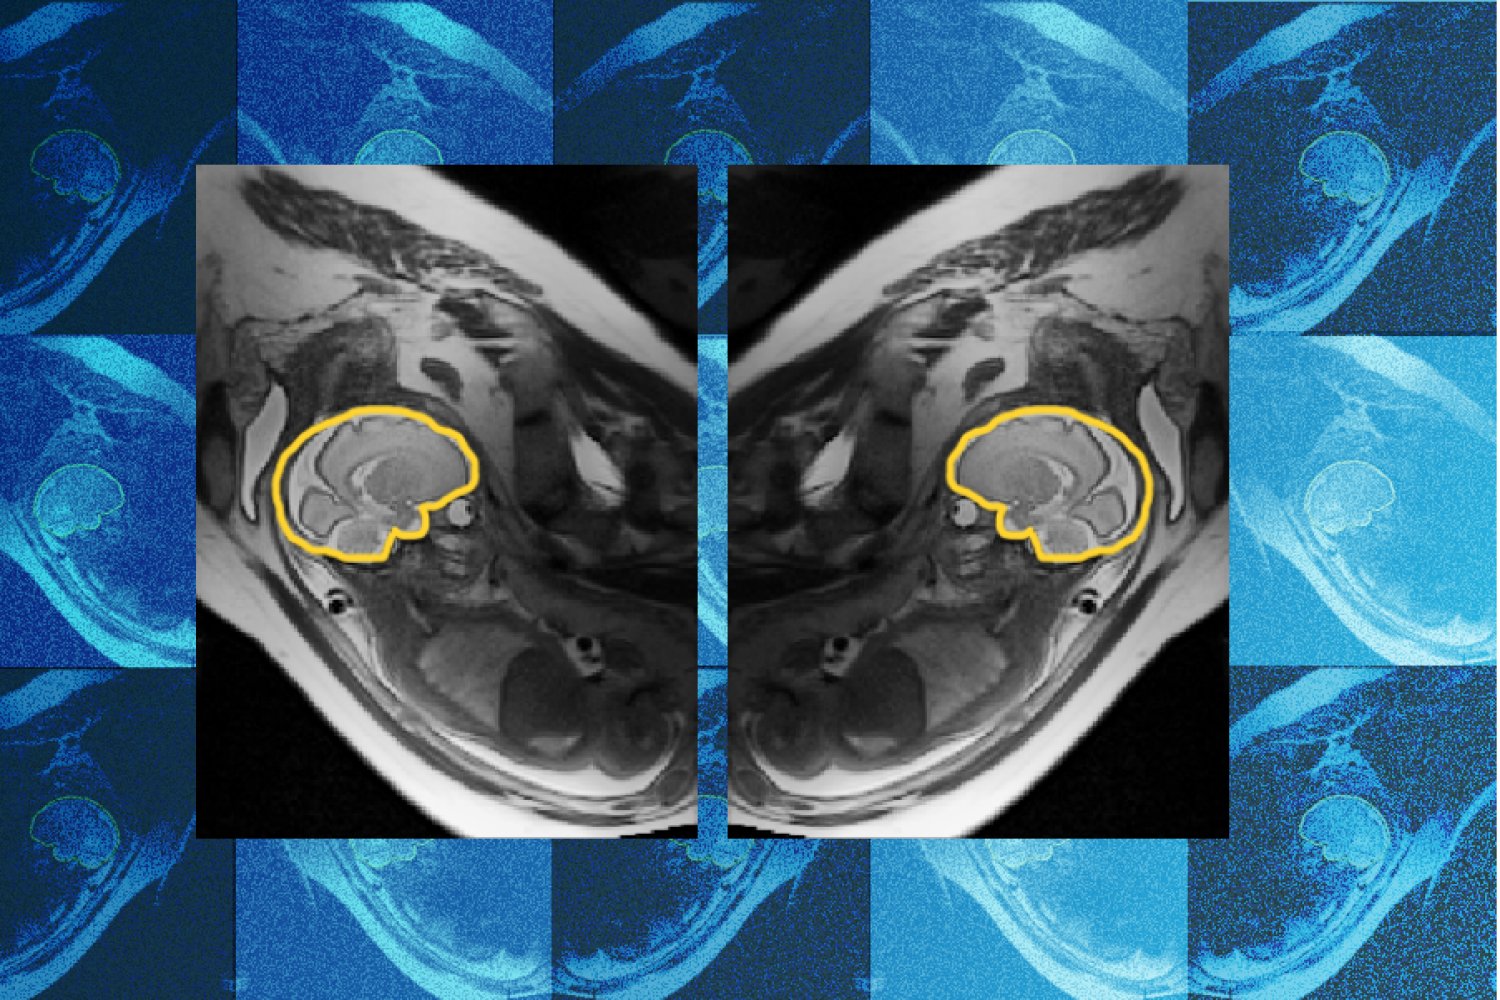
A model developed by researchers at MIT and Boston Children's Hospital adjusts scans on the fly to track fetal movement, potentially sparing families repeat hospital visits.
MIT News · Artificial Intelligence· news.mit.eduOct 18, 2026