Skip to content

ALRA: Adaptive Local Relational Alignment for Logit-Based Pre-training Distillation of Autoregressive Language Models

Sep 2026 · 0 citations · 38 references
Mathematics Computer Science

TL;DR

This work proposes Adaptive Local Relational Alignment (ALRA), a position-specific framework combining student proposals with teacher guidance, which replaces the teacher-mass coefficients of the two conditional terms with unit coefficients, preventing either term from being downweighted solely because its region has low teacher probability.

Abstract

Logit-based knowledge distillation for autoregressive language models usually aligns teacher and student next-token distributions over the entire vocabulary. However, this global objective overlooks relative preferences among likely token alternatives. Existing local approaches often select candidate tokens from either the teacher or the student alone. Teacher-only selection can miss tokens that the student considers likely, while student-only selection can rely on an inaccurate ranking early in training. We propose Adaptive Local Relational Alignment (ALRA), a position-specific framework combining student proposals with teacher guidance. At each valid prediction position, the student proposes likely tokens, while the teacher's most probable token is included as an anchor. ALRA adjusts the number of selected tokens according to how broadly the teacher distributes probability within this candidate set relative to the current batch. Adaptive Local Divergence retains the mass-matching term and separately matches the relative token distributions within the selected and remaining vocabulary regions. Unlike the exact full-vocabulary decomposition, it replaces the teacher-mass coefficients of the two conditional terms with unit coefficients, preventing either term from being downweighted solely because its region has low teacher probability. Student-Weighted Pairwise Relational Alignment emphasizes high-probability token pairs with small student probability gaps and gives less weight to unlikely or clearly separated pairs. Experiments on The Pile with randomly initialized 200M- and 500M-parameter students across nine zero-shot benchmarks yield average accuracies of 36.62% and 37.40%. ALRA exceeds the strongest competing distillation baseline by 0.94 and 0.83 percentage points and improves over pre-training without distillation by 2.31 and 2.91 points, respectively.

View source

Similar papers

#artificial intelligence Preprint Sep 2026

Dual-Vocabulary Language Model for Cross-Tokenizer Distillation

On-policy distillation (OPD) bridges teacher supervision and student behavior, but different teacher-student tokenizers introduce misalignment in both input tokenization (#1) and output logits (#2). Existing approaches address the former by matching same-text spans or converting tokens to bytes, often losing fine-grain...

Ke-Di Chen, Chen Lin, Yutao Sun et al. · 1 citation
#machine learning Preprint Sep 2026

Inductive Feedback for Mixed-Policy Distillation

This work treats verbal feedback as evidence for or against the hypothesis that a particular token comes next at a given prefix, and adopts a probabilistic confirmation framework which uniquely determines an ordering over the vocabulary based on the teacher's predictions before and after it receives feedback.

Amir Moeini, Huai-Jiang Zhu, Daniel Havir et al. · 0 citations
#artificial intelligence Preprint Oct 2026

Rethinking Cross-Tokenizer On-Policy Distillation: From Alignment Coverage to Supervision Reliability

On-Policy Distillation (OPD) trains a student on its own generations using teacher feedback. With different tokenizers, comparing teacher and student predictions requires alignment at both sequence and vocabulary levels. In this paper, we examine whether expanding this alignment coverage improves learning. Across three...

Bing-Xi Hou, Guochao Jiang, Guo-Feng Quan et al. · 0 citations
#machine learning Preprint Sep 2026

Look Before You Select: Rethinking Vocabulary Sparsification in On-Policy Distillation

On-policy distillation (OPD) uses teacher correction on student-generated responses. Full-vocabulary correction can provide important corrections even for tokens that the student assigns low probability, but backpropagating through all token logits becomes memory-intensive for long sequences. Existing memory-saving app...

Yongliang Miao, Shuang Liu, Yan-Guang Liu et al. · 0 citations
#machine learning Preprint Oct 2026

Latent-MOPD: Latent Multi-Teacher On-Policy Distillation

On-policy distillation (OPD) trains a student on the responses it generates. Existing LLM multi-teacher OPD transfers what specialists predict through their output distributions. We introduce Latent-MOPD, to our knowledge the first representation-level multi-teacher OPD method for LLMs. It integrates existing specialis...

Zheng-Yu Fang, Seoyeon Hong, Jie Yang et al. · 0 citations
#machine learning Preprint Sep 2026

Better Supervision Is Nearby: Neighborhood On-Policy Self-Distillation

On-policy self-distillation (OPSD) trains mathematical reasoning models using a privileged teacher that sees a reference solution and supervises student-sampled prefixes. Standard OPSD uses one fixed parameter setting at every state, but nearby settings may offer additional supervision. We find that local parameter per...

Xin Wei, Yi-Fan Ding, Yoshua Y. Li et al. · 0 citations

Related blog posts

Microsoft Research Blog Oct 22, 2026

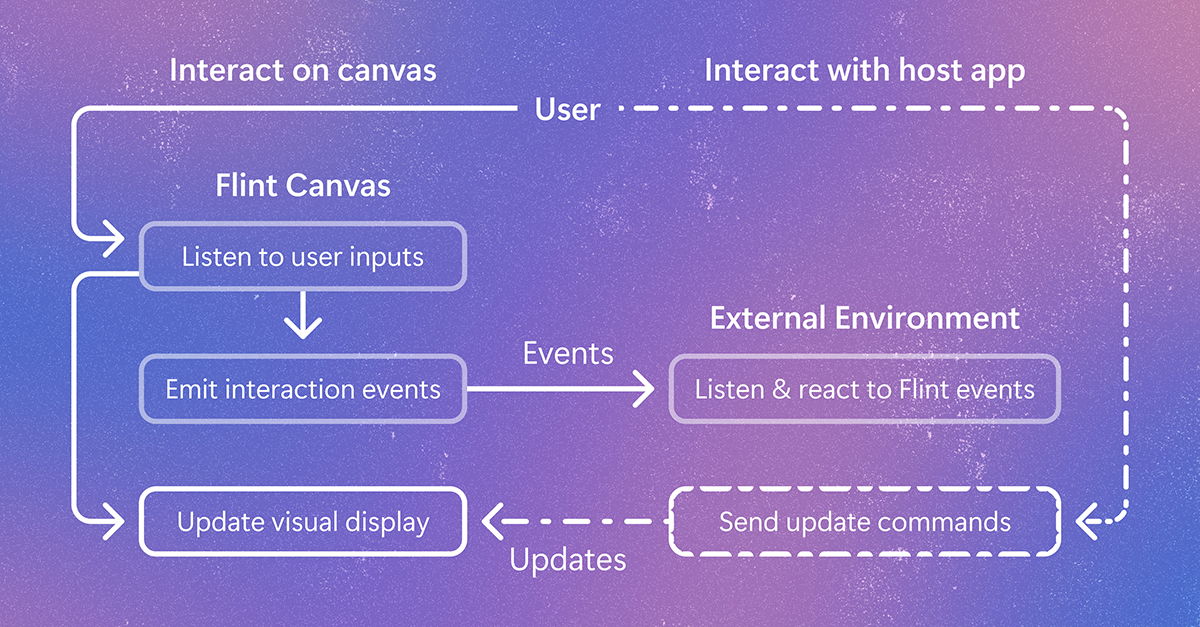
Flint-interactive: A language for creating interactive data visualizations

Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.

Microsoft Research Blog Oct 15, 2026

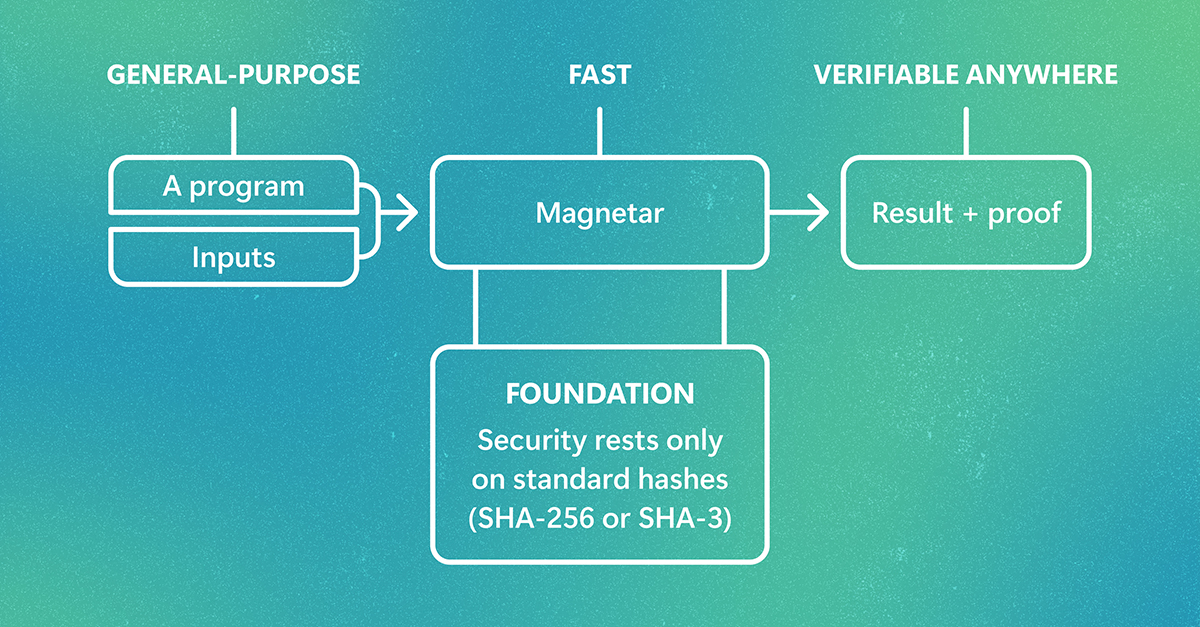
Proof-based general-purpose computing with Magnetar

Zero-knowledge proofs can verify computing results without rerunning workloads or exposing sensitive data. Magnetar helps bring them into the mainstream with support for standard programming languages, major speed gains, and quantum-resistant security. The post Proof-based general-purpose computing with Magnetar appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.