Sep 2026· ACM Transactions on Software Engineering and Methodology· 0 citations· 105 references
TL;DR
This work proposes tHinter, an automated approach that frames translation error localization as a differential testing task, and integrates mixed-factorial user studies, expert validation, and SWOT-based strategic analysis to assess the perceived helpfulness and resilience within the rapidly evolving LLM landscape.
Abstract
Code translation, as a challenging and fundamental task, is increasingly relying on large language models (LLMs). However, LLMs often give seemingly plausible but fallacious translations, misleading and even deceptive to debugging developers. We propose tHinter, an automated approach that frames translation error localization as a differential testing task. By fuzzing and a novel Bayesian-inspired algorithm that integrates developer heuristics into SBFL, tHinter thoroughly exposes translation errors and effectively pinpoints functionality-twisting errors. We evaluate tHinter in a Python to C++ scenario, a representative and challenging task for migrating high-level logic to performance-critical systems. Experiments show that tHinter achieves the highest F1 in localizing translation errors, outperforming all baselines. When debugging LLM-translated code with human efforts, it averagely reduces 71% lines developers need to review. Furthermore, we provide a comprehensive evaluation reference beyond traditional fault localization metrics. We integrate mixed-factorial user studies, expert validation, and SWOT-based strategic analysis to assess the perceived helpfulness and resilience within the rapidly evolving LLM landscape, offering a methodologically rigorous example for researchers in the context of AI-augmented software engineering.
While LLM-rewritten messages significantly improved subjective evaluations, with pragmatic messages rated as clearer and less cognitively demanding, these perceived gains did not translate into statistically significant improvements in objective debugging performance.
Alexandru-Radu Moraru, Shreyan Biswas, U. Gadiraju· 0 citations
Trivet is presented, a framework combining large language models (LLMs) and Lean for automated translation validation of LLVM transformations, which generates structured proof scaffolds based on source and target functions, automatically discharges obligations amenable to deterministic reasoning, and delegates transfor...
Chun-Feng Liao, Hong-Xu Xu, Xin-Tong Zhou et al.· 0 citations
The results show that previous conclusions from Python may be sensitive to benchmark construction, feedback representation, and tooling ecosystem, motivating more controlled multilingual benchmarks, and confirm key trends under a partially controlled replication of LLMbased repair systems.
L. Lalonde, Wassim Keddache, Thomas Perron Touchette et al.· 0 citations
The findings suggest that hidden states are a robust and informative resource for estimating functional code correctness, supporting a two-stage workflow that combines response-level risk screening with targeted line-level prioritization.
A novel empirical study targeting three domain- specific languages for transformation rules, namely Comby, GritQL, and Ast-Grep, which shows great potential for LLMs to generate sound, correct, generalizable, and reusable rules.
Axel Allain, Aymeric Blot, D. Khelladi et al.· Proceedings of the 41st IEEE...· 1 citation
This paper presents a formal mathematical model for categorizing the outcome of generated-tests into four classes, a couple of basic metrics: Bug-Revealing Rate (BRR) and Bug-Validating Rate (BVR); and two basic statistical tests to ensure that the results are rigorous.
Zeyad Farooq Lutfi· Al-Noor Journal of Engineeri...· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comNov 12, 2026
What's new in research at Microsoft? Host Anson Ho explores the latest, including AI-powered universal translation, a breakthrough in a 31-year-old mathematics challenge, and advances making AI coding agents faster and more efficient. The post Microsoft Research Focus – Edition #98 appeared first on Microsoft Research.
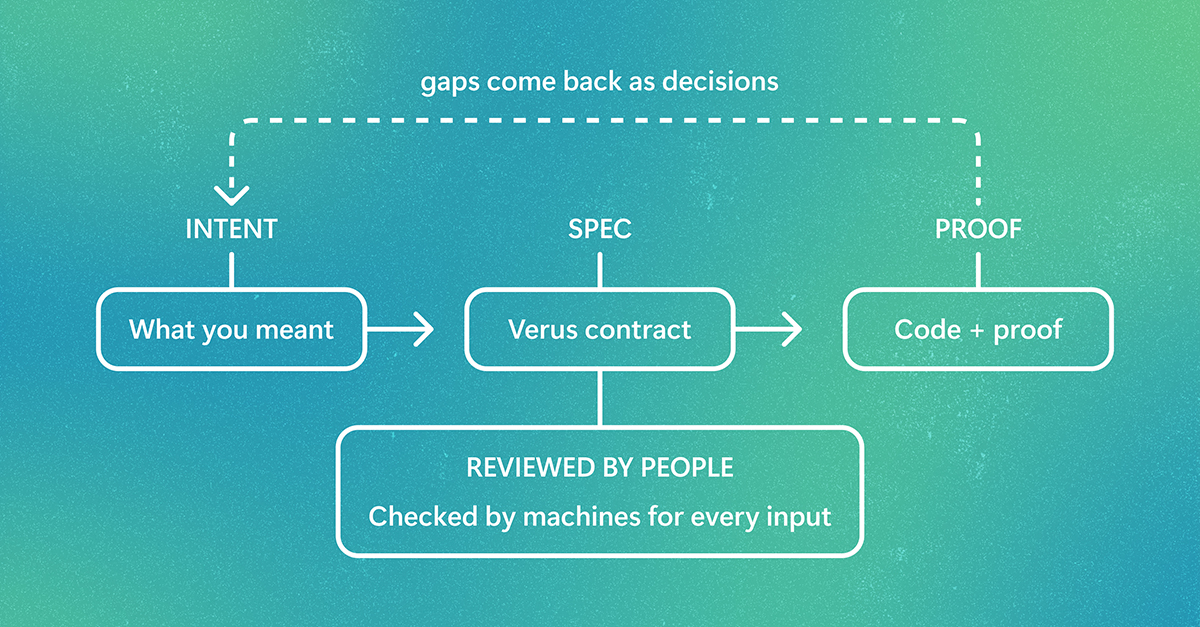
AI agents can generate code at a scale that’s hard for humans to review line-by-line. PDD Kit helps ensure the code is doing what the developer intended by creating formal specifications and testing against them. It converts developer intent into a Verus specification, proves AI-generated code meets it for every input, and uses tests where proofs aren't practical. Developers review intent, not every line. The post Formally verifying agent-written full-stack web apps with PDD Kit appeared first o…