Sep 2026· International Journal of Current Educational Studies· Vol 5, pp. e2026007· 0 citations· 46 references
Artificial Intelligence in Healthcare and Education
TL;DR
The findings reveal a paradox of fluent unreliability: AI-generated errors are often indistinguishable from accurate content, and this risk is inversely distributed with student competence.
Abstract
Generative AI (GenAI) has introduced reliability risks in education, including hallucinations, fabricated citations, factual inaccuracies, overreliance, and threats to assessment validity. Empirical evidence on these risks has not been systematically synthesized. This review synthesizes that evidence and its consequences for learning and assessment across four research questions. Following PRISMA 2020, Web of Science and Scopus were searched. After duplicate removal, 155 records were screened by two independent doctoral researchers (Cohen's κ = .847). Thirty-five empirical studies were included; 32 (91.4%) were rated high quality using the Mixed Methods Appraisal Tool (MMAT). Thematic synthesis identified four themes: (1) hallucinations and factual inaccuracies taken up as misinformation, moderated by domain expertise; (2) reliability limitations in automated essay scoring, classroom observation, and AI detection, with fairness disparities for EFL learners; (3) overreliance and cognitive offloading, with preliminary evidence of cognitive atrophy; and (4) malleable trustworthiness perceptions, protected by domain knowledge and metacognitive accuracy. The findings reveal a paradox of fluent unreliability: AI-generated errors are often indistinguishable from accurate content, and this risk is inversely distributed with student competence. The themes are integrated into an Epistemic Reliability Framework, that supports epistemic scaffolding, assessment redesign, and AI literacy targeting metacognition.

A structured survey of AI hallucinations, synthesizing prior research to clarify their evolving definitions, underlying causes, and implications for Information Systems positions AI hallucinations as socio-technical phenomena with direct implications for trust, decision-making, and governance.
This study investigates the subjective perspectives and evaluative orientations of university students when navigating AI hallucinations during human–AI collaborative writing and offers empirical material for formulating tentative, data-informed pedagogical hypotheses concerning different patterns of epistemic and cogn...
Yu-Peng Guo, Ting Huang, Sheng-Chen Yue et al.· Journal of educational compu...· 0 citations
Children with intellectual and developmental disabilities (IDD) face elevated risks of victimization and may participate in forensic interviews, yet their reports are often evaluated through deficit-based assumptions. Following Preferred Reporting Items for Systematic Reviews and Meta-Analyses (PRISMA) 2020 guidelines,...
Seung-Jin Lee· Intellectual and Development...· 0 citations
The study reveals that AI hallucinations have three kinds of manifestations, which include content distortion, evidence failure and improper argumentation, which comprises factual error, false or irrelevant citation, and superficially coherent arguments lacking evidence.
A narrative review distinguishes fabrication, the invention of an entirely non-existent source, from unfaithfulness, the citation of a genuine source in support of a claim it does not contain, and argues that the two failure modes require different detection strategies.
M. Rana, M. Alkhlewi, Turki Abdulaziz Alsohaibani et al.· European Journal of Prosthod...· 0 citations
Retrieval-based evidence verification provides a reproducible and transparent approach for evaluating the reliability of AI-generated medical information, with direct relevance to digital health practice, evidence-based medicine, and medical informatics.
AI coding agents are increasingly help developers fix bugs and build features largely on their own, but every interaction with their models consumes tokens. In each session, an agent sends instructions, tool descriptions, and session history to its model. Most efforts to reduce this cost focus on individual tasks. Yet developers return to the same […] The post TokenEconomizer: Learning from Experience to Make AI Coding Agents More Efficient appeared first on Microsoft Research.
At ICSOB 2026 in Gothenburg, we presented TenderIntell, our work on multi-agent support for tendering. This post looks back at the conference, the idea behind a panel of three AI reviewers who score each proposal independently, and why evaluating agents reliably is the question we keep coming back to. The post TenderIntell at ICSOB 2026: Three Days in Gothenburg appeared first on GPT-Lab.
MIT News · Artificial Intelligence· news.mit.eduNov 13, 2026
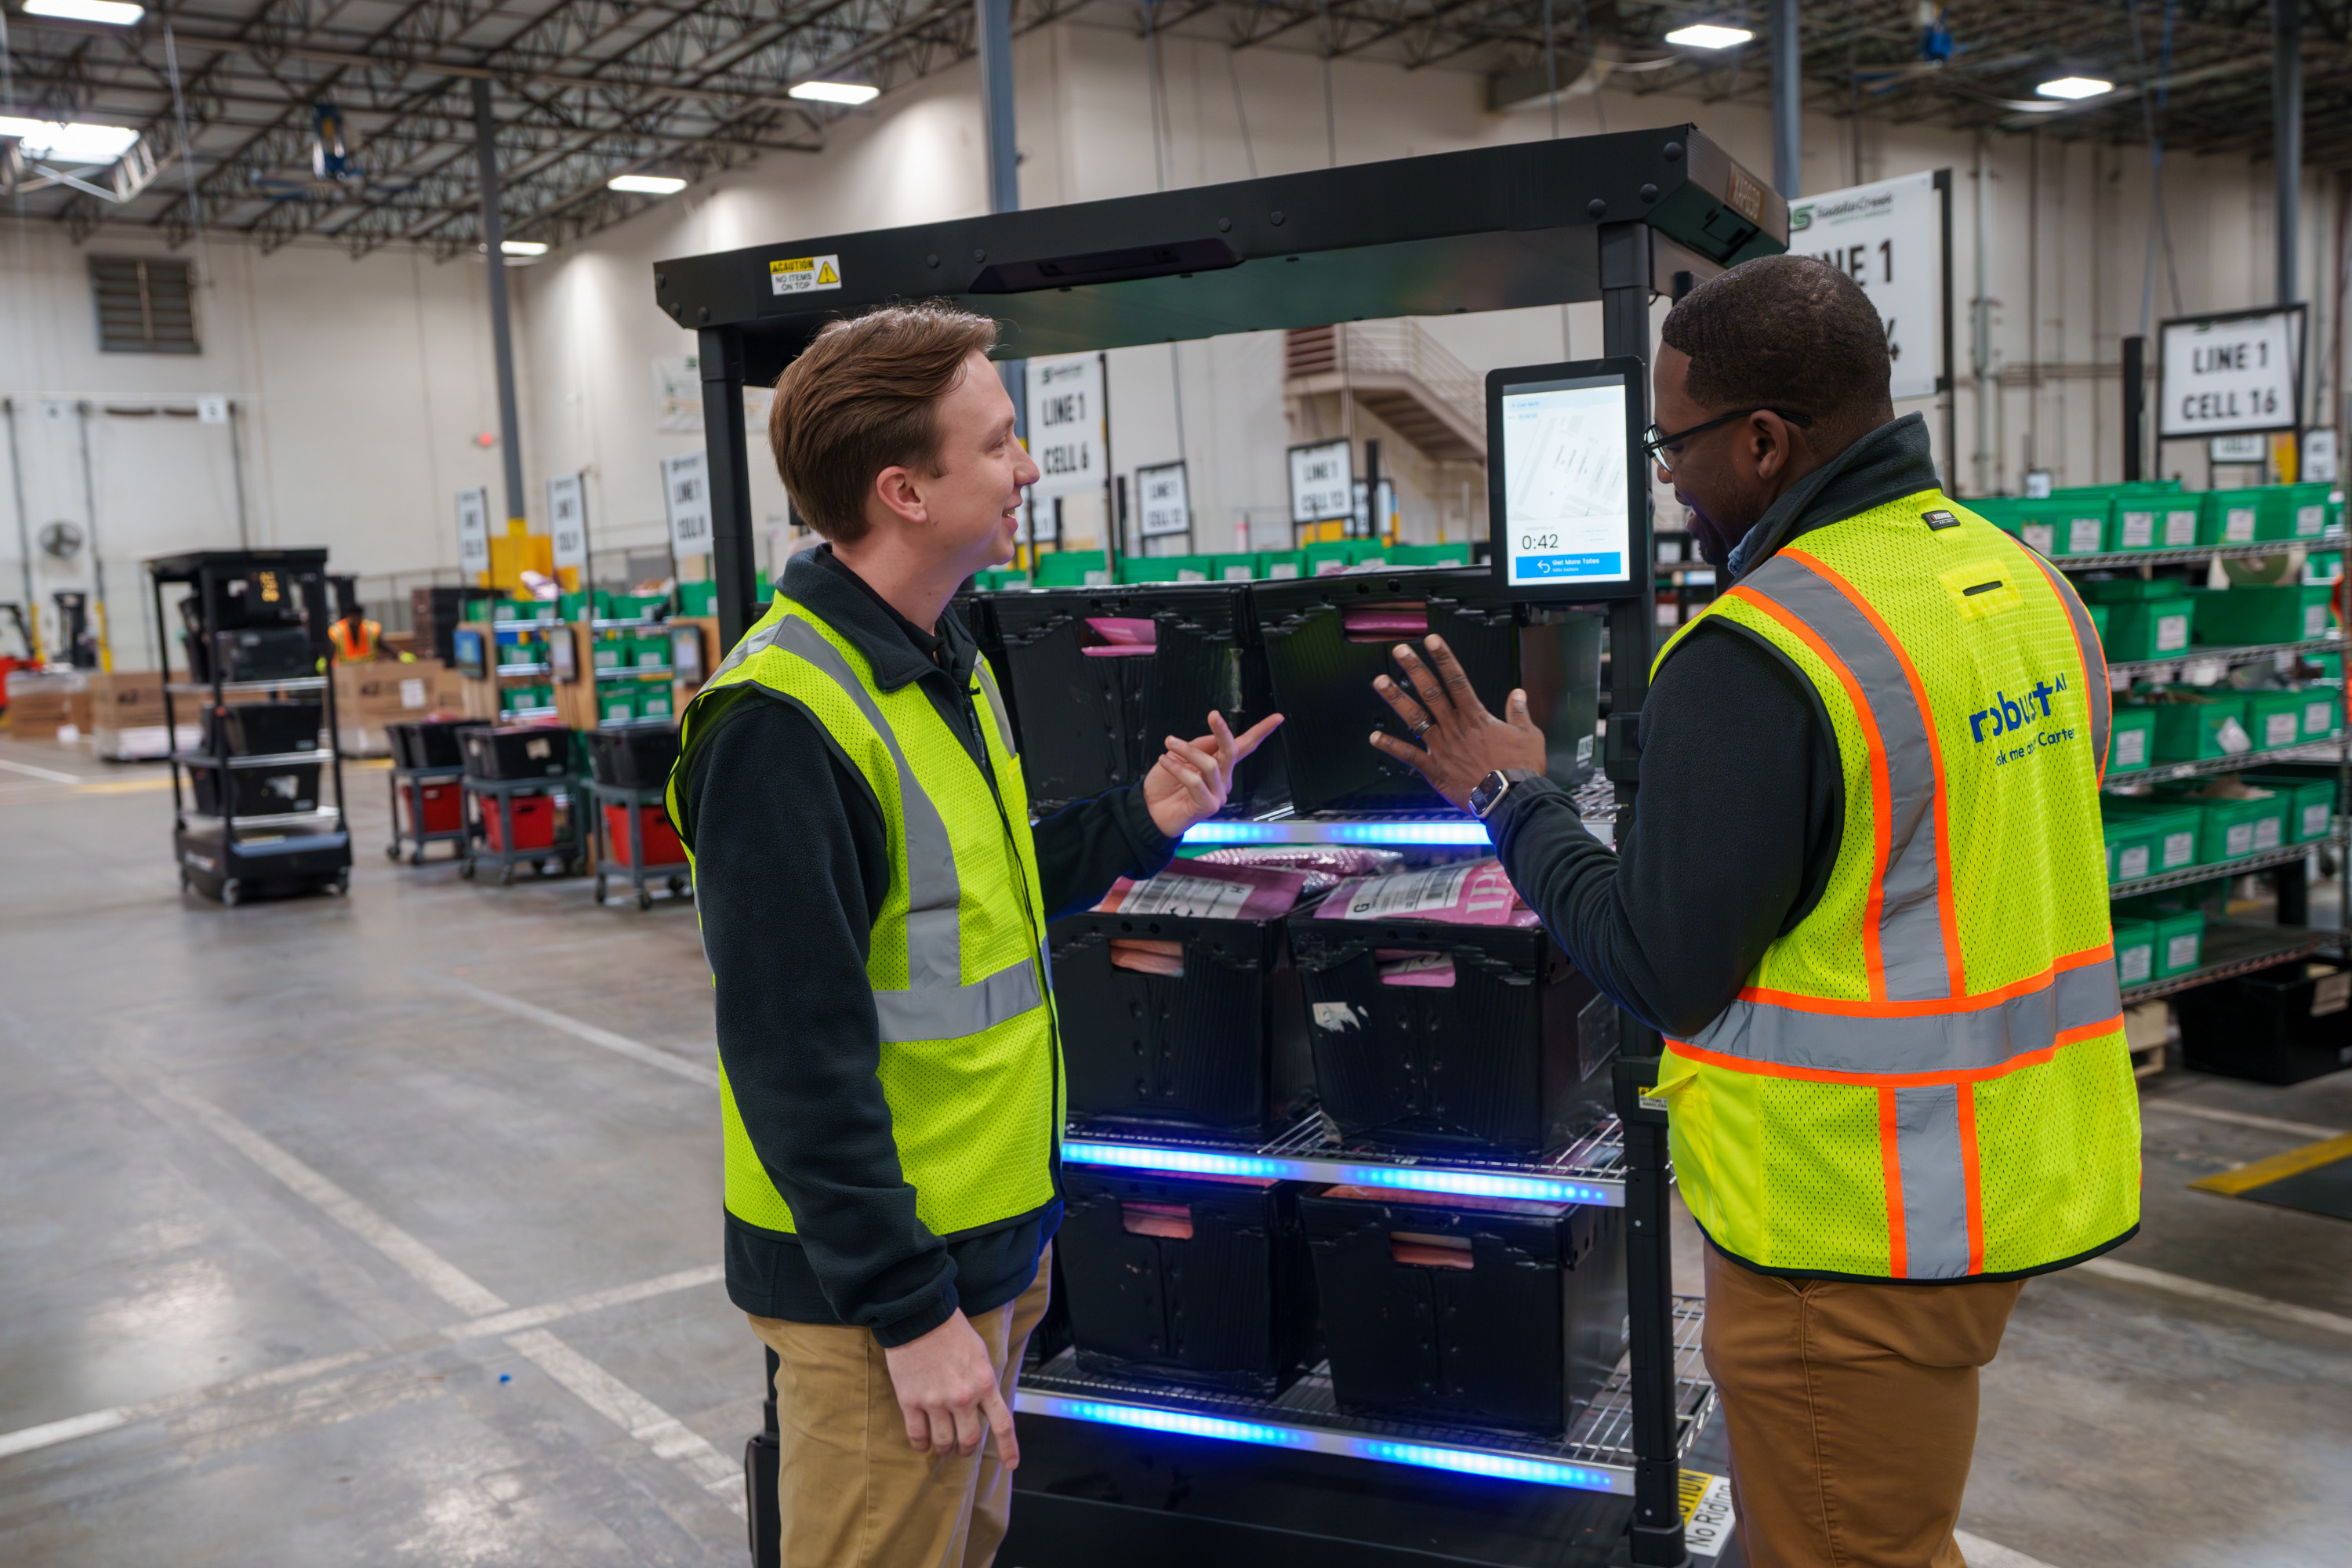
Founded by Anthony Jules ’92, SM ’92 and Professor Emeritus Rodney Brooks, Robust AI’s robots are designed to collaborate with humans in factories and warehouses.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.