A recent study released three Kurdish voices, 35 hours of recorded speech, and a paper describing the work, all free to download are checked to make the work easier for others, especially community linguists, to check and reuse.
Abstract
Kurdish is spoken by millions of people, but little technology can read it aloud. A recent study released three Kurdish voices, 35 hours of recorded speech, and a paper describing the work, all free to download. This review checks how well those public files match the paper. The research is careful about its limits, but the files contain several problems: a settings file lists equipment that was never used, test recordings are left unlabeled among training data, and a coding fault mishandles long numbers. The download page also claims a stronger result than the paper reports and recommends one voice for general use. That recommendation matters because Kurdish has major regional and written variation, while these voices were built from three people reading prepared texts. The process therefore removes much everyday and regional speech. English and German benefit from long traditions of dictionaries and linguistic description that help identify wrong pronunciations; Kurdish has far less such support, so software choices can go unchecked. The voices sound fluent, but they represent the reading styles of their speakers rather than Kurdish as a whole. Most of these issues can be fixed using information the team already has, without changing the reported results. Better records would mainly make the work easier for others, especially community linguists, to check and reuse. The license is the main exception: whether audiobook owners allow corrected versions to be shared will affect whether future Kurdish voices can build on this work or must start again.
The notable findings suggest that LLMs often make basic errors of grammar and semantics, and highlight the limitations of current LLMs as a reliable source of content generation and information retrieval for low-resource languages.
Farah Adeeba, A. Khan, Rajesh Bhatt et al.· 0 citations
The MMS output contains 613 unconverted or unmapped characters, showing that part of the residual error reflects scoring-pipeline limits rather than recognition alone, and the fixed reference and segment-level results are released, subject to source-corpus sharing terms, to support independent checking.
This work performs experiments on VoxPopuli and The Polish Parliamentary speech datasets and estimates word error rate (WER) differences for different text normalization approaches, showing that the difference due to the lack of number normalization in WER may be substantial.
Neyshekar is presented as an open Persian read-speech corpus designed for coverage of both formal and informal language, named entities, and longer utterances, and utility is assessed through two ASR architectures, three optimisation seeds, WER and CER, and independent evaluation on the public PSRB sample.
Ahmad Amirivojdan, Farzad Nadiri, Abolfazl Alizadeh et al.· 0 citations
Low-resource multilingual text-to-speech (TTS) systems have expanded language coverage, but their robustness under complex text inputs remains insufficiently diagnosed. Existing evaluations mainly focus on naturalness, speaker similarity, and content consistency using regular test sentences, while providing limited ins...
Tian-Lun Zuo, Zi-Yu Zhang, Tingzhi Mao et al.· 0 citations
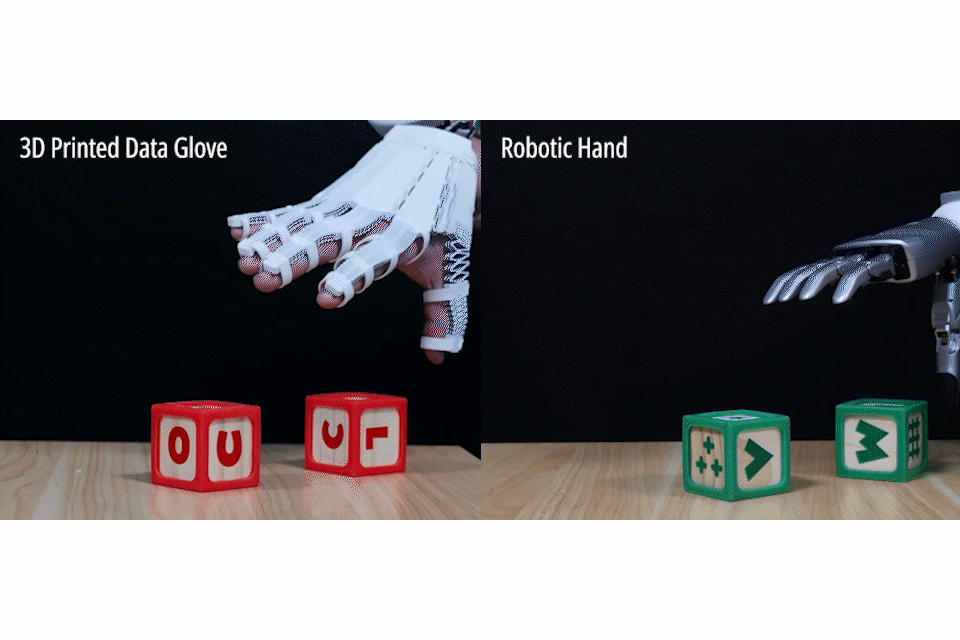
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
Microsoft Research Blog· microsoft.comOct 22, 2026
Flint-interactive gives AI agents a language for creating interactive visualizations. Click a chart, filter data, highlight related content, and explore beyond the view the author originally chose. The post Flint-interactive: A language for creating interactive data visualizations appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.
