Code, data and notebooks accompanying the manuscript "Reinforcement learning-based PID for nonlinear temperature control with delayed feedback and measurement noise" (Y. Sapazhanov, S. Kadyrov; submitted to Mathematical Models in Engineering, Extrica). The study compares six strategies for tuning PID and nonlinear PID...
Yershat Sapazhanov, Shirali Kadyrov· Zenodo (CERN European Organi...· 0 citations
Large language models (LLMs) are increasingly used in Electronic Design Automation (EDA) to write hardware description code. This paper reviews how LLMs generate and verify Verilog for a RISC-V processor datapath, a core topic in Computer Architecture and Organization. The review is built around the AI-driven logic syn...
RENZ HERALD ELAMPARO· Zenodo (CERN European Organi...· 0 citations
Résumé (FR) Ce document, produit avec l'assistance de Gemini 3 Raisonnement, est publié sous licence Apache 2.0. Il constitue une publication défensive volontaire (antériorité) et entre de ce fait dans l'état de la technique dès sa publication en vertu des législations sur les brevets applicables : art. 54(2) CBE (Conv...
Xavier Pillet· Zenodo (CERN European Organi...· 0 citations
Contemporary AI alignment research is dominated by two paradigms: behavioral conditioning through Reinforcement Learning from Human Feedback (RLHF), and speculative epistemic frameworks such as "Simulation Theology." Both treat alignment as an external constraint imposed on a value-neutral substrate, and both fail for...
Rémi Leroy· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Large language models encode behavioral constraints directly within their latent representations. Existing approaches to modifying these behaviors rely on parameter-level adjustments (Supervised Fine-Tuning, Reinforcement Learning from Human Feedback, or permanent weight abliteration). These irreversibly alter model we...
Stefan Beierle· Zenodo (CERN European Organi...· 0 citations
Abstract Cloud-based systems demand secure yet efficient file access mechanisms. Traditional encryption frameworks often introduce latency and resource overhead, limiting scalability. Building on Astillero's (2026) AI-driven logic gate synthesis, this paper explores how Artificial Intelligence (AI) can optimize encrypt...
Diane Rose Cepe· Zenodo (CERN European Organi...· 0 citations
Résumé (FR) Ce document, produit avec l'assistance de Gemini 3 Raisonnement, est publié sous licence Apache 2.0. Il constitue une publication défensive volontaire (antériorité) et entre de ce fait dans l'état de la technique dès sa publication en vertu des législations sur les brevets applicables : art. 54(2) CBE (Conv...
Xavier Pillet· Zenodo (CERN European Organi...· 0 citations
Audited data and code archive for the associated autonomous-motion-planning manuscript. Includes 65 raw training-stat MAT files, 47 executed 100-scenario final-test MAT files, 47 selected Stage-10 checkpoints, frozen final and validation scenario banks, run-level ledgers, and verification scripts. Independent regenerat...
Yusuf Bilfaqih, Ari Santoso, Joko Susila et al.· Zenodo (CERN European Organi...· 0 citations
Healthcare organizations are one of the most susceptible targets to advanced cyber-attacks owing to increasing dependence on cloud computing, AI-powered clinical applications, interconnected medical devices, and EHRs.The traditional security approach is unable to tackle ransomware attacks, insider threats, identity the...
Alisha Panda· International Journal of Sci...· 0 citations
Code, data and notebooks accompanying the manuscript "Reinforcement learning-based PID for nonlinear temperature control with delayed feedback and measurement noise" (Y. Sapazhanov, S. Kadyrov; submitted to Mathematical Models in Engineering, Extrica). The study compares six strategies for tuning PID and nonlinear PID...
Yershat Sapazhanov, Shirali Kadyrov· Zenodo (CERN European Organi...· 0 citations
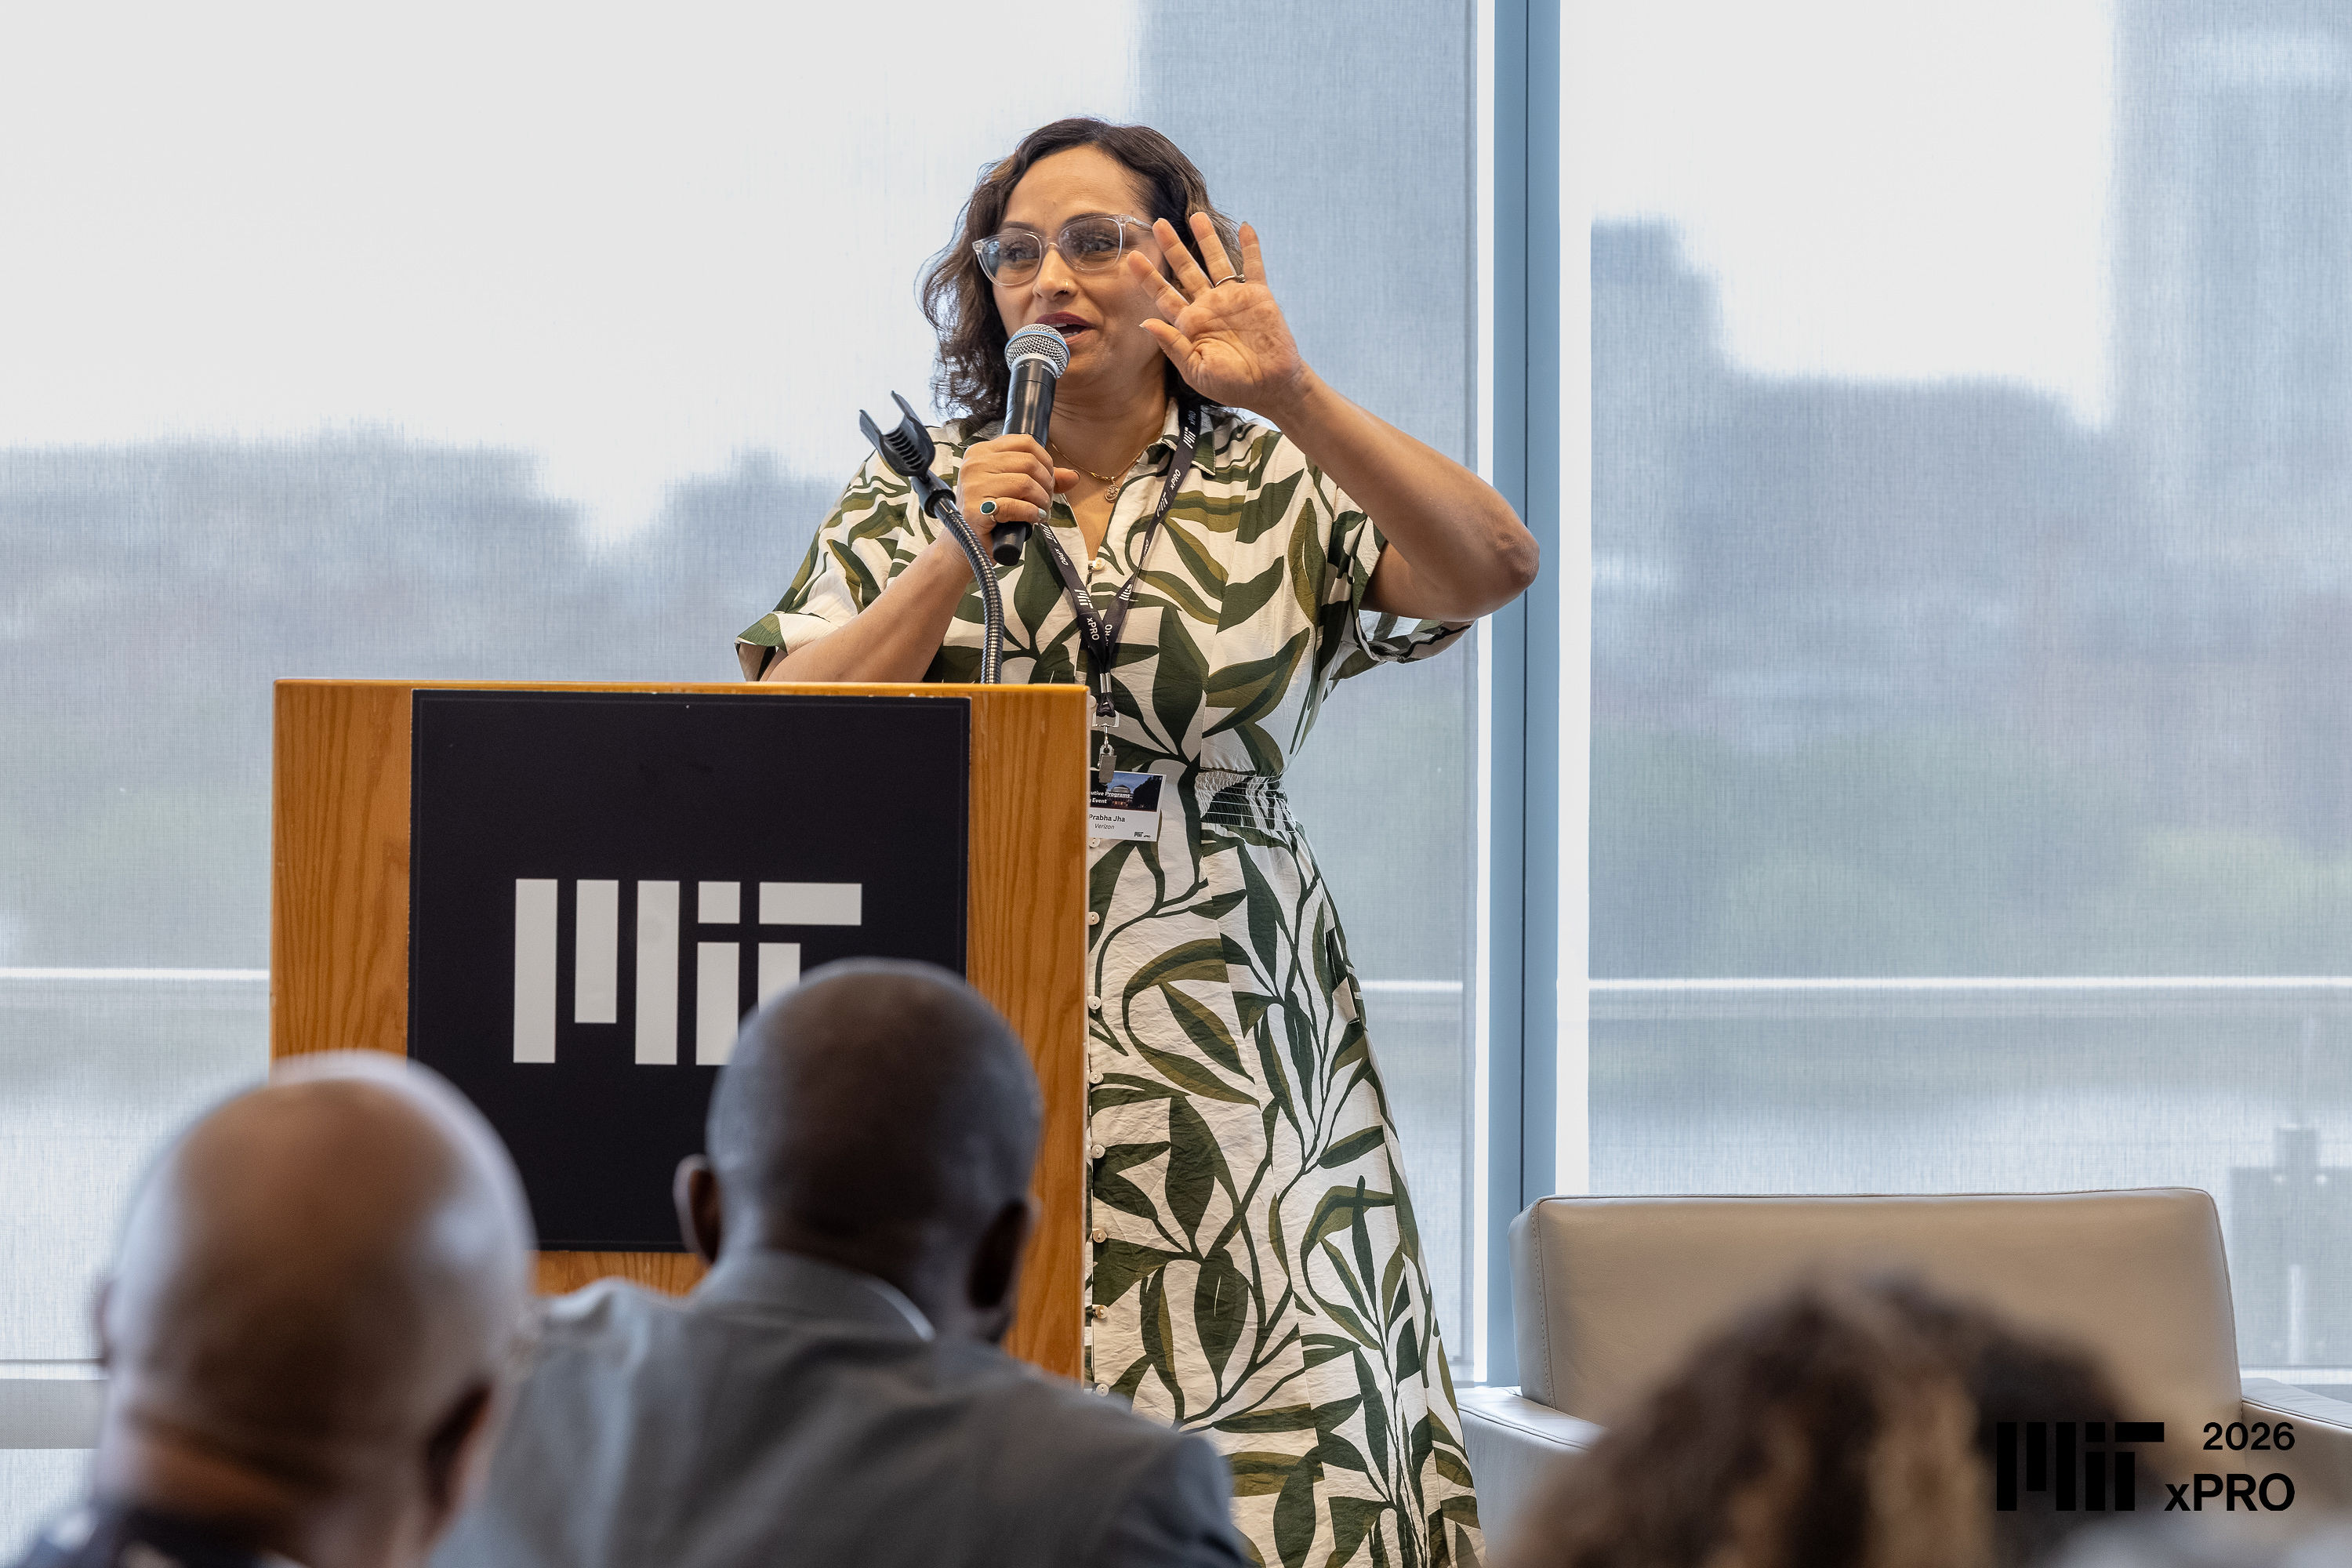
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.