Code and Data for Nonlocal Monte Carlo via Deep Reinforcement Learning
Code and Data for "Nonlocal Monte Carlo via Deep Reinforcement Learning"
Dmitrii Dobrynin
· Zenodo (CERN European Organi... · 0 citations
Category
2,493 papers
Code and Data for "Nonlocal Monte Carlo via Deep Reinforcement Learning"
Understanding consumer sentiment is important in digital marketing because it strongly influences brand perception and purchasing decisions. This paper proposes a novel two-agent off-policy proximal policy optimization (PPO) framework. Unlike standard multi-agent reinforcement learning (RL) approaches, the proposed fra...
Abstract This study verified the effects of “experiential practice” and “visualizing” carbon dioxide reduction on the transformation of junior high school students' environmental awareness and pro-environmental behavior (PEB). We sought to propose measures for sustaining high environmental awareness and choice of appro...
Audited data and code archive for the associated autonomous-motion-planning manuscript. Includes 65 raw training-stat MAT files, 47 executed 100-scenario final-test MAT files, 47 selected Stage-10 checkpoints, frozen final and validation scenario banks, run-level ledgers, and verification scripts. Independent regenerat...
Reach audiences
Advertise in front of researchers, engineers, and readers.
ABOUT ReactFlow is a flow-matching model that generates the transition state (TS) and the surrounding reaction pathway from reactant and product structures. It uses an SO(3)-equivariant EquiformerV2 backbone (35.3M parameters) and is trained in two stages: flow-matching pretraining, followed by GRPO reinforcement-learn...
Mobile Edge Computing (MEC) enables resource-constrained mobile devices to offload computation-intensive tasks to nearby edge servers. Existing computation offloading approaches primarily optimise latency, energy consumption, or resource allocation, but often do not consider security constraints and multi-user queue st...
Quantum Electronics Explained: Quantum Systems, Devices & Advanced Technologies is a publication-grade Open Educational Resource (OER) module covering the physical principles, macroscopic quantum mechanics, circuit quantum electrodynamics (cQED), and cryogenic microwave control governing quantum hardware. Serving as an...
ABOUT ReactFlow is a flow-matching model that generates the transition state (TS) and the surrounding reaction pathway from reactant and product structures. It uses an SO(3)-equivariant EquiformerV2 backbone (35.3M parameters) and is trained in two stages: flow-matching pretraining, followed by GRPO reinforcement-learn...
Smart city Internet of Things (IoT) networks is generating a continuous stream of heterogeneous sensor data that tends to require a timely analysis under the strict energy, latency, and computational constraints. Existing cloud-edge learning approaches have improved IoT intelligence, but they often treat feature learni...
Abstract High penetration of inverter-interfaced generation, faults, and sudden load changes in power systems makes them more vulnerable to voltage and frequency deviations. Traditional controllers often struggle to adapt to varying disturbance types and severities in real time. Adaptive, data-driven control methods ar...
Code, simulation setup and results accompanying the paper "ProphetRouterRL: A Reinforcement Learning Enhanced Routing Protocol for V2X Delay Tolerant Networks" (submitted to MDPI Network). ProphetRouterRL keeps PRoPHET's delivery-predictability comparison as a first filter and adds a small tabular Q-learning agent that...
Cross-border energy supply chains under the Belt and Road Initiative (BRI) face unprecedented challenges, including geopolitical instability, macroeconomic volatility, and operational disruptions. Traditional optimization or flat reinforcement learning (RL) methods often struggle to address the scale, uncertainty, an...
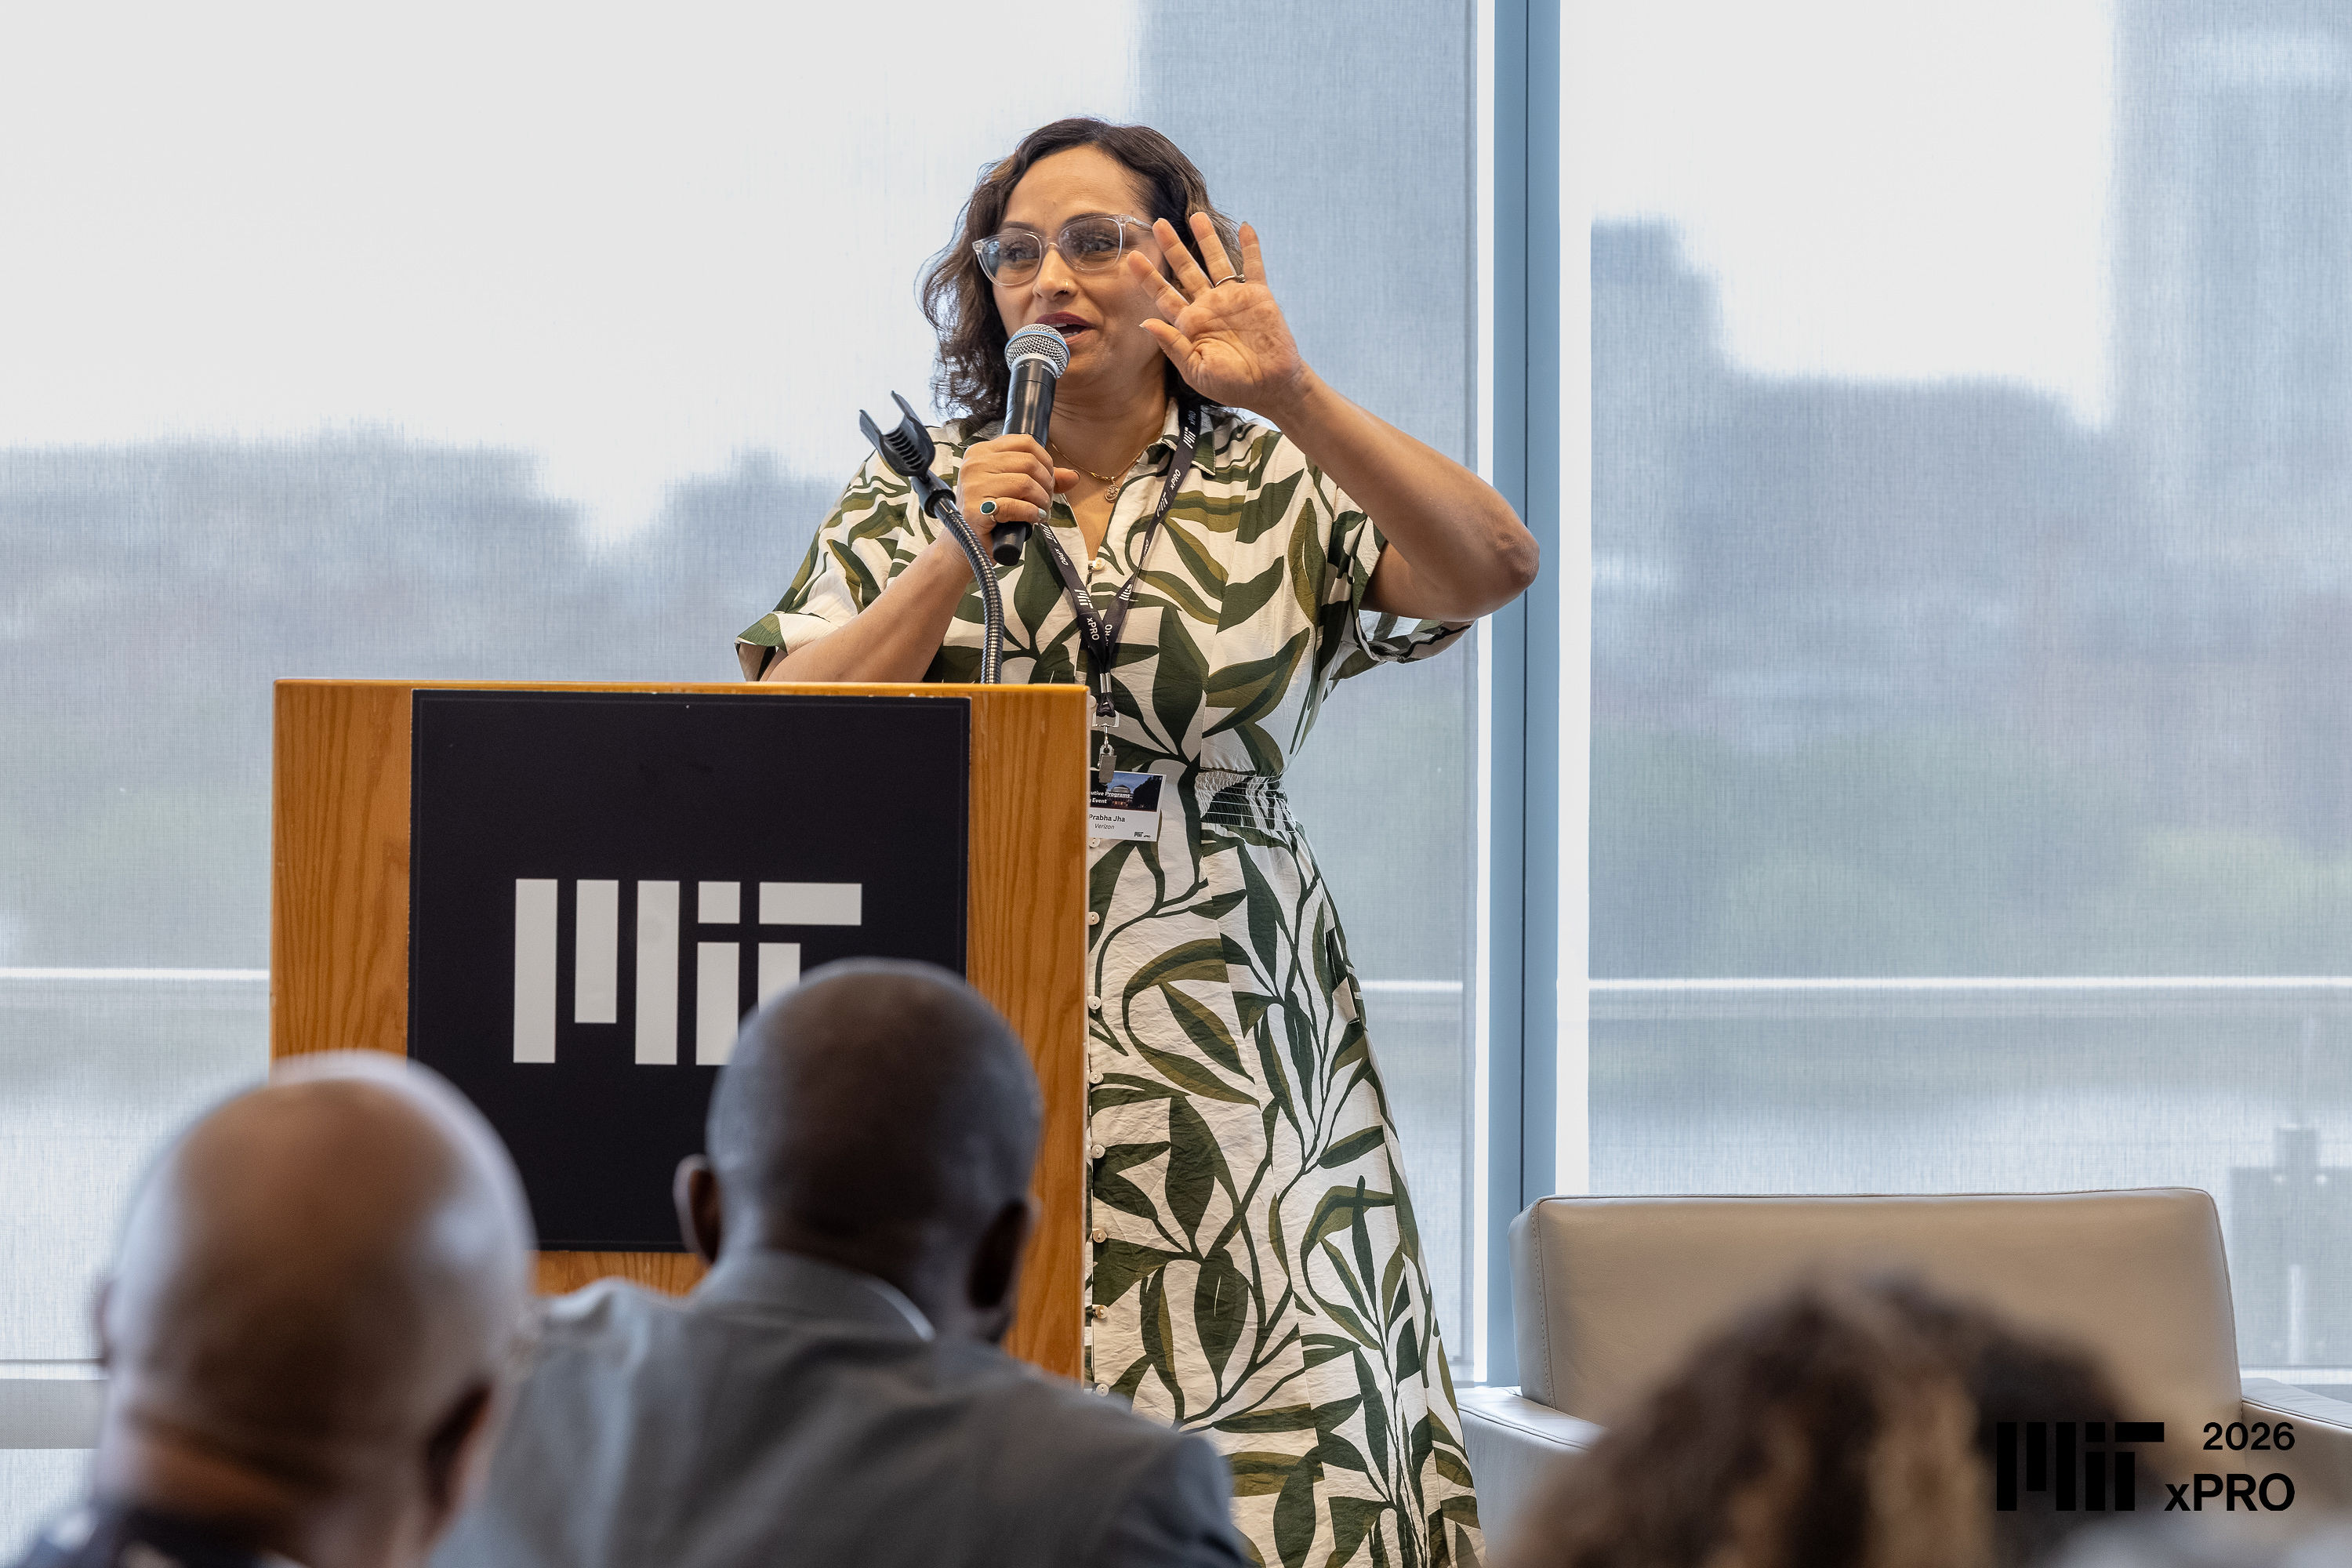
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Education Innovation
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
A Blog post by NVIDIA on Hugging Face
A Blog post by IBM Research on Hugging Face
A new machine-learning approach broke records for weather forecasting for an important time frame in emergency planning.
We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.