Preprint · Version 1 · September 2026 · Not peer reviewed If the limits of language are the limits of the thinkable, then the possibility of linguistic superintelligence depends on whether a system can expand its own language. This paper argues that large language models (LLMs) cannot do so in a closed regime. We intro...
Carlos Alberto Sierra Murillo· Zenodo (CERN European Organi...· 0 citations
Abstract of Cache-Fused Kinematic Rails: Ex-Ante Silicon Alignment via In-Vivo KV-Cache Metric Grafting Current Large Language Model (LLM) alignment relies primarily on post-hoc, output-level correction mechanisms such as external API meta-governors, Reinforcement Learning from Human Feedback (RLHF), or post-generation...
Daniel Solis· Zenodo (CERN European Organi...· 0 citations
Hardware-aware quantization frameworks such as HAQ use reinforcement learning (RL)to search per-layer bit-width policies, but this search itself requires hundreds to thousands ofpolicy evaluations with an accelerator (and, in HAQ’s case, per-episode fine-tuning) in theloop — a resource requirement that is at odds with...
Alaa eldeen Abdelrahman· Zenodo (CERN European Organi...· 0 citations
FINDING: The search results are video titles and abstracts, not actual mathematical solutions. No equations, constants, or derivations are present. The only concrete mathematical content is a reference to an arXiv paper on robotic garment folding (LeHome Challenge 2026), which is applied robotics, not pure competition...
Andrew Stewart Caldin· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
rslcpp - the ROS simulation library for C++ - lets you turn a set of existing ROS 2 nodes into a deterministic simulation. Instead of the asynchronous, multi-process default execution of ROS 2, rslcpp aggregates all participating nodes in a single process and drives them through a custom executor under an explicit simu...
Simon Sagmeister, Marcel Weinmann· Zenodo (CERN European Organi...· 0 citations
Cell-Free (CF) massive Multiple-Input Multiple Output (MIMO) networks are a key enabler for future sixth generation wireless systems, as they allow distributed Radio Units (RUs) to cooperatively serve users and mitigate inter-user interference. However, under dense deployments and high spatial loading, conventional lin...
Mohammad Eskandarinia, John S. Vardakas, Christos V. Verikoukis· Zenodo (CERN European Organi...· 0 citations
This article provides a beginner-friendly introduction to Machine Learning and explains how artificial intelligence systems learn patterns from data. It discusses the role of data, the training process, and the main approaches to machine learning, including supervised learning, unsupervised learning, and reinforcement...
Sofia Boukefa· Zenodo (CERN European Organi...· 0 citations
We demonstrate a system that replaces the default Kubernetes scheduler with an inference and topology-aware Reinforcement Learning policy. The system time-slices each GPU, consumes live Prometheus telemetry and places inference workloads across Far-Edge, Edge and Cloud tiers using an action masked agent (MaskablePPO, M...
Ioannis Kyriakopoulos, Kostas Ramantas, Christos V. Verikoukis· Zenodo (CERN European Organi...· 0 citations
Multimodal Large Language Models (MLLMs) have become a leading approach to visual reasoning, yet the field still lacks a quantitative synthesis that rigorously identifies the drivers of their performance. In this paper, we evaluate 21 models across 7 standardised benchmarks, yielding 102 model–benchmark observation...
Results indicate a favorable overall QoS–energy–signaling trade-off for selective risk-aware DAPS activation with hybrid rule-constrained and RL-assisted control within the controlled single-UE 1-D boundary-crossing model.
T. Khan, Taimur Karamat, Mohsan Tanveer et al.· Discover Computing· 0 citations
This paper investigates AI-driven jamming as an emerging security threat to sixth-generation (6G) wireless networks. Unlike conventional jamming techniques that rely on relatively fixed and predictable interference patterns, AI-driven jamming can use machine learning to sense network conditions, adapt attack strategies...
Mohammad Taha Sayahi· Zenodo (CERN European Organi...· 0 citations
chabira abderraouf Autonomous developer agents operating on commodity hardware face a critical trade-off between code correctness and resource stability. Traditional reinforcement learning from human feedback (RLHF) and PPO-based code optimization rely on binary success/failure rewards, which are vulnerable to reward h...
Abderraouf CHABIRA· Zenodo (CERN European Organi...· 0 citations
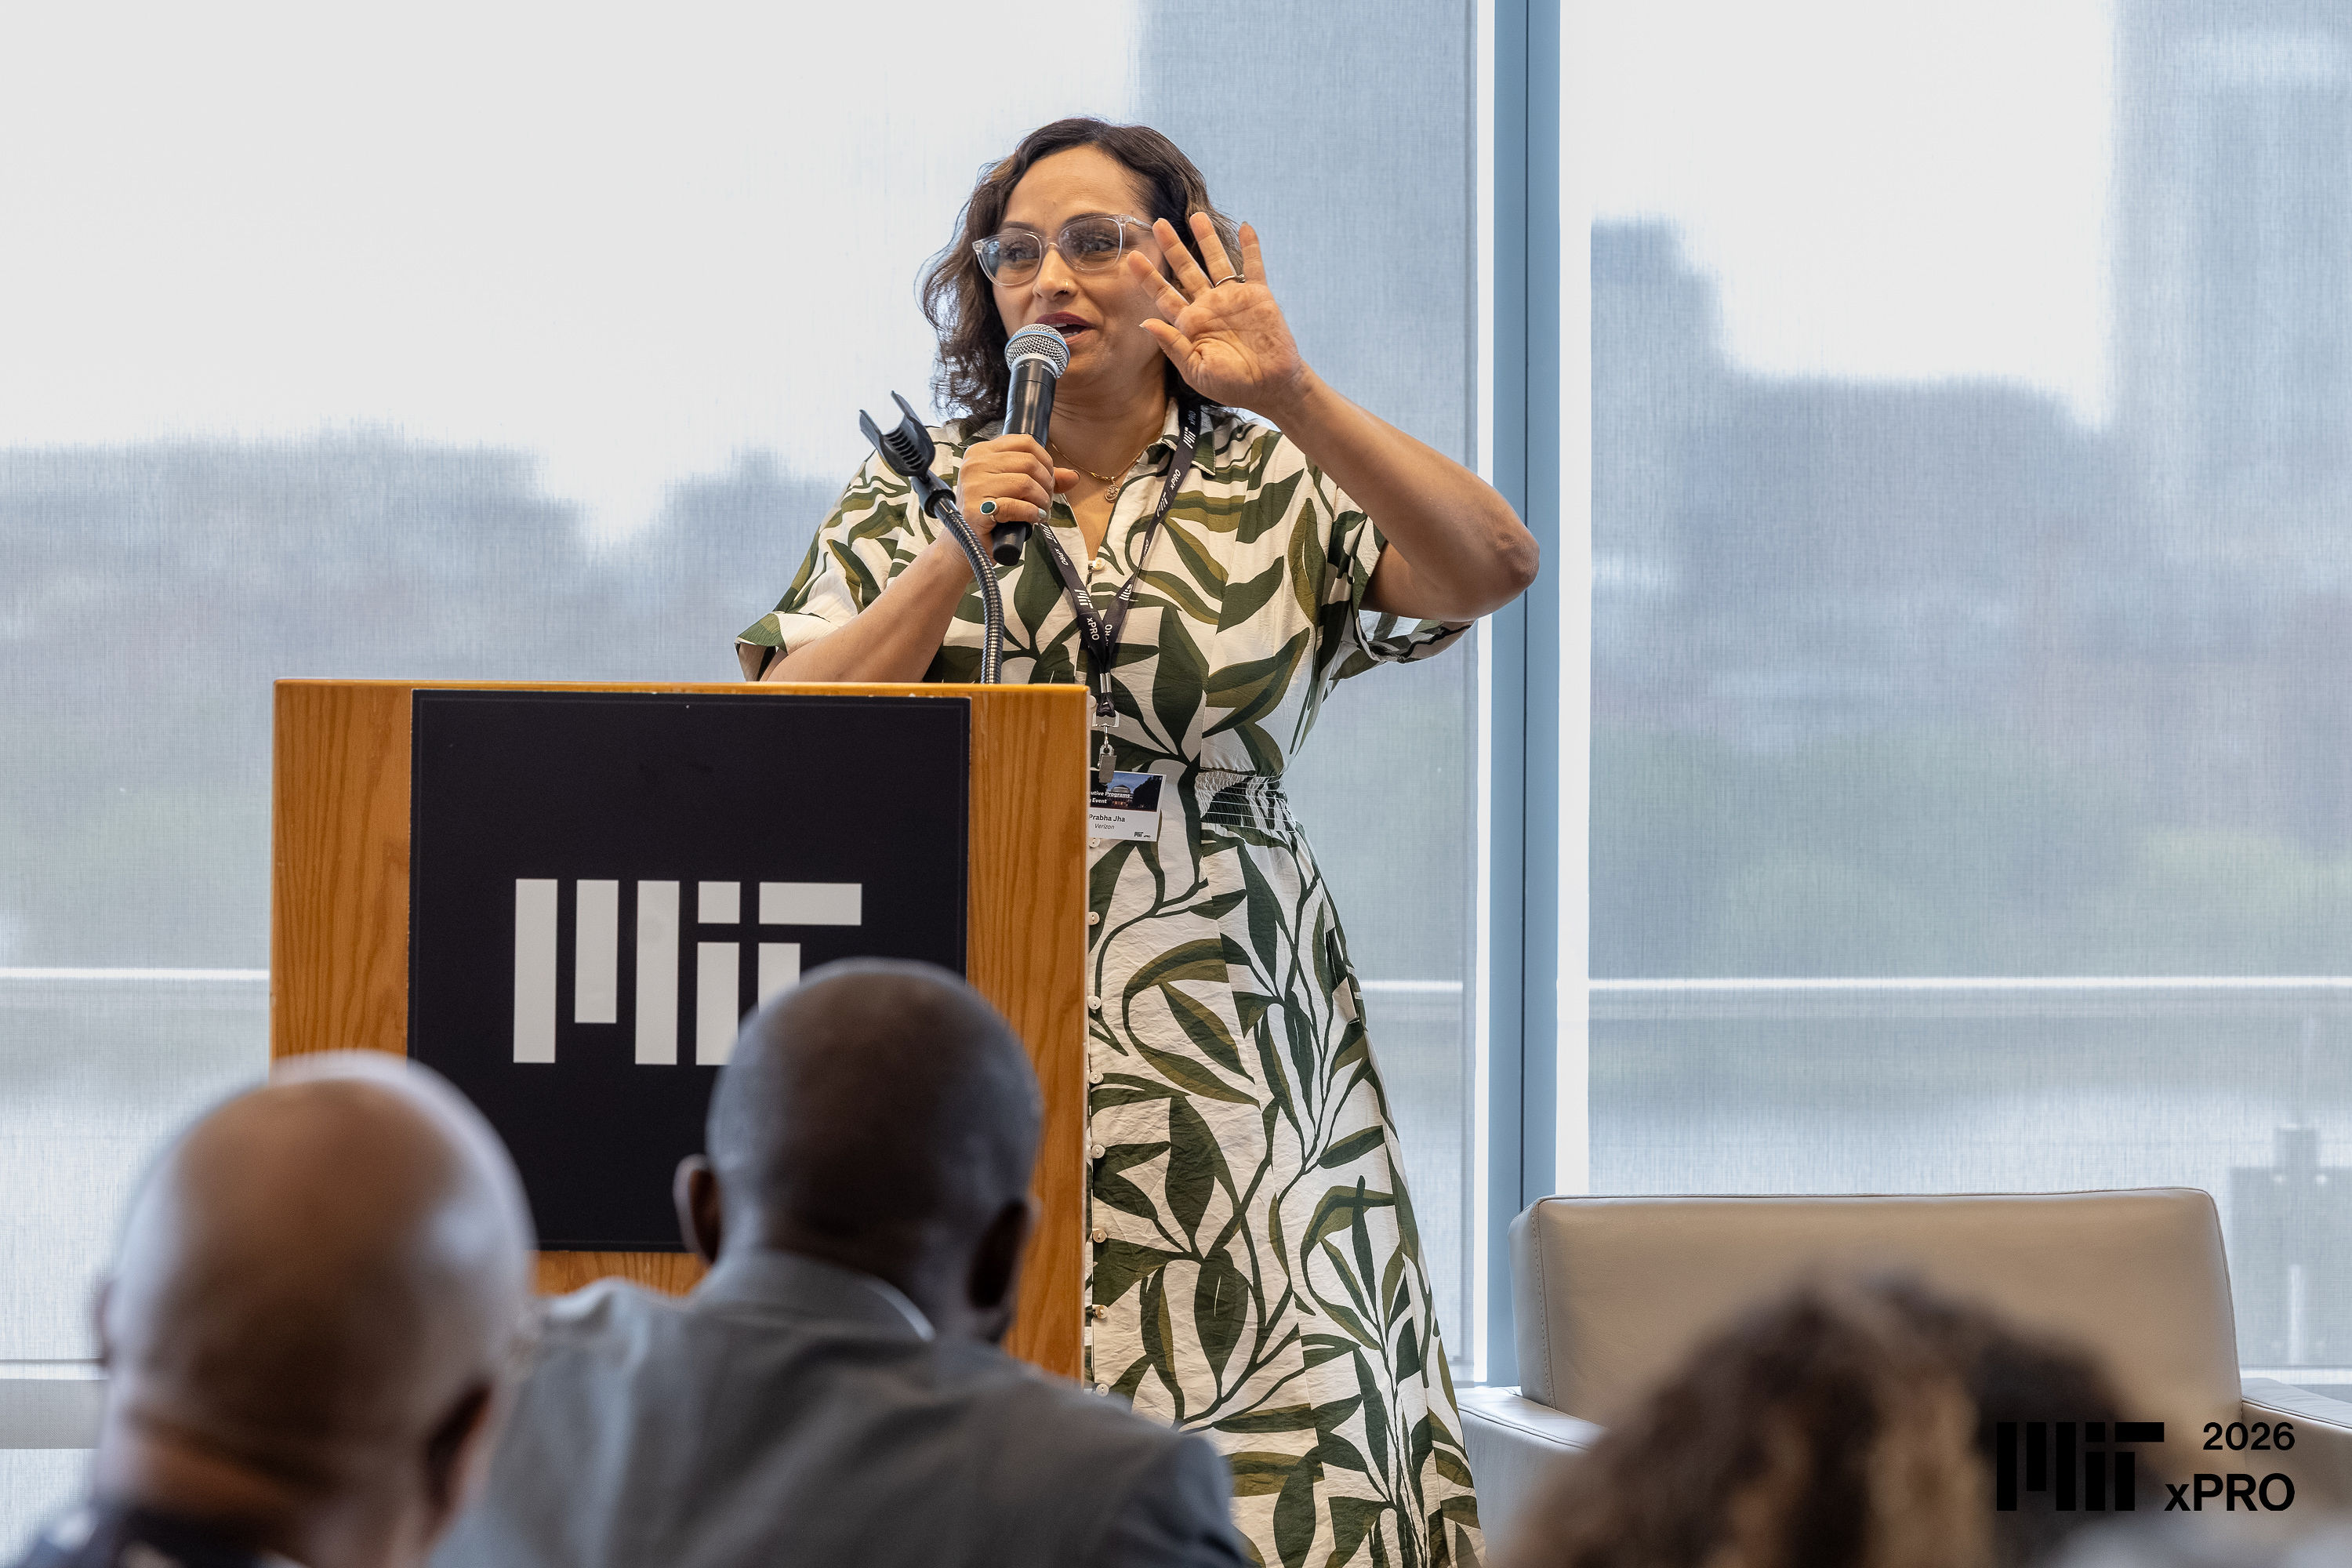
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.