Large language models increasingly produce confidence reports, predictive distributions, and structured decisions that determine whether a system answers, abstains, retrieves evidence, or spends additional computation. Reinforcement learning can improve these signals, but it can also change the answers being assessed,...
Developing economies are particularly prone to polycrisis risk given their inherent fragilities, volatile capital flows, and exposure to geopolitical events. The financial risk methodologies, such as value at risk modeling and linear econometric forecasting, cannot accommodate nonlinear risk interactions across differe...
Amrita Tatia, Sarita Agarwal, Reema Limbad et al.· Global Business Strategy in...· 0 citations
An intelligent, energy-efficient, and robust multi-pollutant forecasting and control framework that integrates hybrid LSTM–GRU forecasting with Proximal Policy Optimization (PPO)-based reinforcement learning to maintain indoor air quality while minimizing unnecessary energy consumption and mechanical actuation is devel...
Walaa N. Ismail, Mona A. S. Ali· Sustainability· 0 citations
This page on Zenodo hosts a free sample only (50 trajectories) — not the full dataset. The complete RegTrace v1 dataset — 29,395 trajectories, 457 SFT traces with full CRL letter text, and 795 forecasting records — is available at sentineldata.com.ua/dataset/regtrace-v1. This sample is a true, unmodified subset of the...
This article introduces a hybrid GA–BO–DRL optimization framework designed to enhance ground node coverage in UAV enabled wireless mesh networks. The proposed methodology integrates a global search mechanism based on a genetic algorithm, a Bayesian optimization module for local refinement, and a deep reinforcement lear...
Eryk DŁUGOSZ, Krzysztof Maślanka· Communications of Internatio...· 0 citations
A deep reinforcement learning-based artificial intelligence framework of time-based e-commerce pricing is introduced, in which the dynamic pricing is modelled as a Markov Decision Process based on demand trends, inventory, user behaviour, and logistical restriction. The method presents a DRCR-based rewarding mechanism,...
Priyanka Kaushik, Divya Naadem, Diana George et al.· Materials, Mechanics, Mechat...· 0 citations
This survey reviews machine-learning-based NoC routing across a 48-study evidence base, and identifies three recurring gaps: limited scalability beyond small meshes, missing deadlock-freedom guarantees for learned policies, and over-reliance on synthetic traffic.
Bernardo Ibarra Infante, Remberto Sandoval Aréchiga, Víktor Iván Rodríguez Abdalá et al.· Machine Learning and Knowled...· 0 citations
This repository contains the complete simulation engine, canonical results, statistical analysis pipeline, and verification/audit trail supporting the manuscript submitted to Scientific Reports. The archive includes: a custom discrete-event WSN simulator implementing a BIS-weighted relay admissibility filter combined w...
Anitha HM, Nalina V, Shreesha Bhat et al.· Zenodo (CERN European Organi...· 0 citations
Personalized learning in AI-driven music education still faces challenges such as the difficulty of integrating multimodal learning evidence, the complexity of modeling music skill dependencies, and the lack of long-term optimization of learning pathways. To address these issues, this paper proposes a framework for opt...
Meng Lin· International Journal of Art...· 0 citations
This dataset contains the simulation code and results for the research paper "Deep Reinforcement Learning for Supply Chain Resilience: The Tengiz–Sileno Ethane Corridor in Kazakhstan." Contents: 1. Python source code for the physics-based simulator of the Tengiz → GSK → Sileno ethane supply chain (sileno_env.py, config...
Background: Elastic and cognitive optical networks vary modulation format, symbol rate, launch power and route while a service is carrying traffic, so the physical layer has to be measured continuously rather than engineered once at commissioning. Optical performance monitoring (OPM) and modulation format identificatio...
G. Lakshmi, S. Brindha· Indian Journal of Science an...· 0 citations
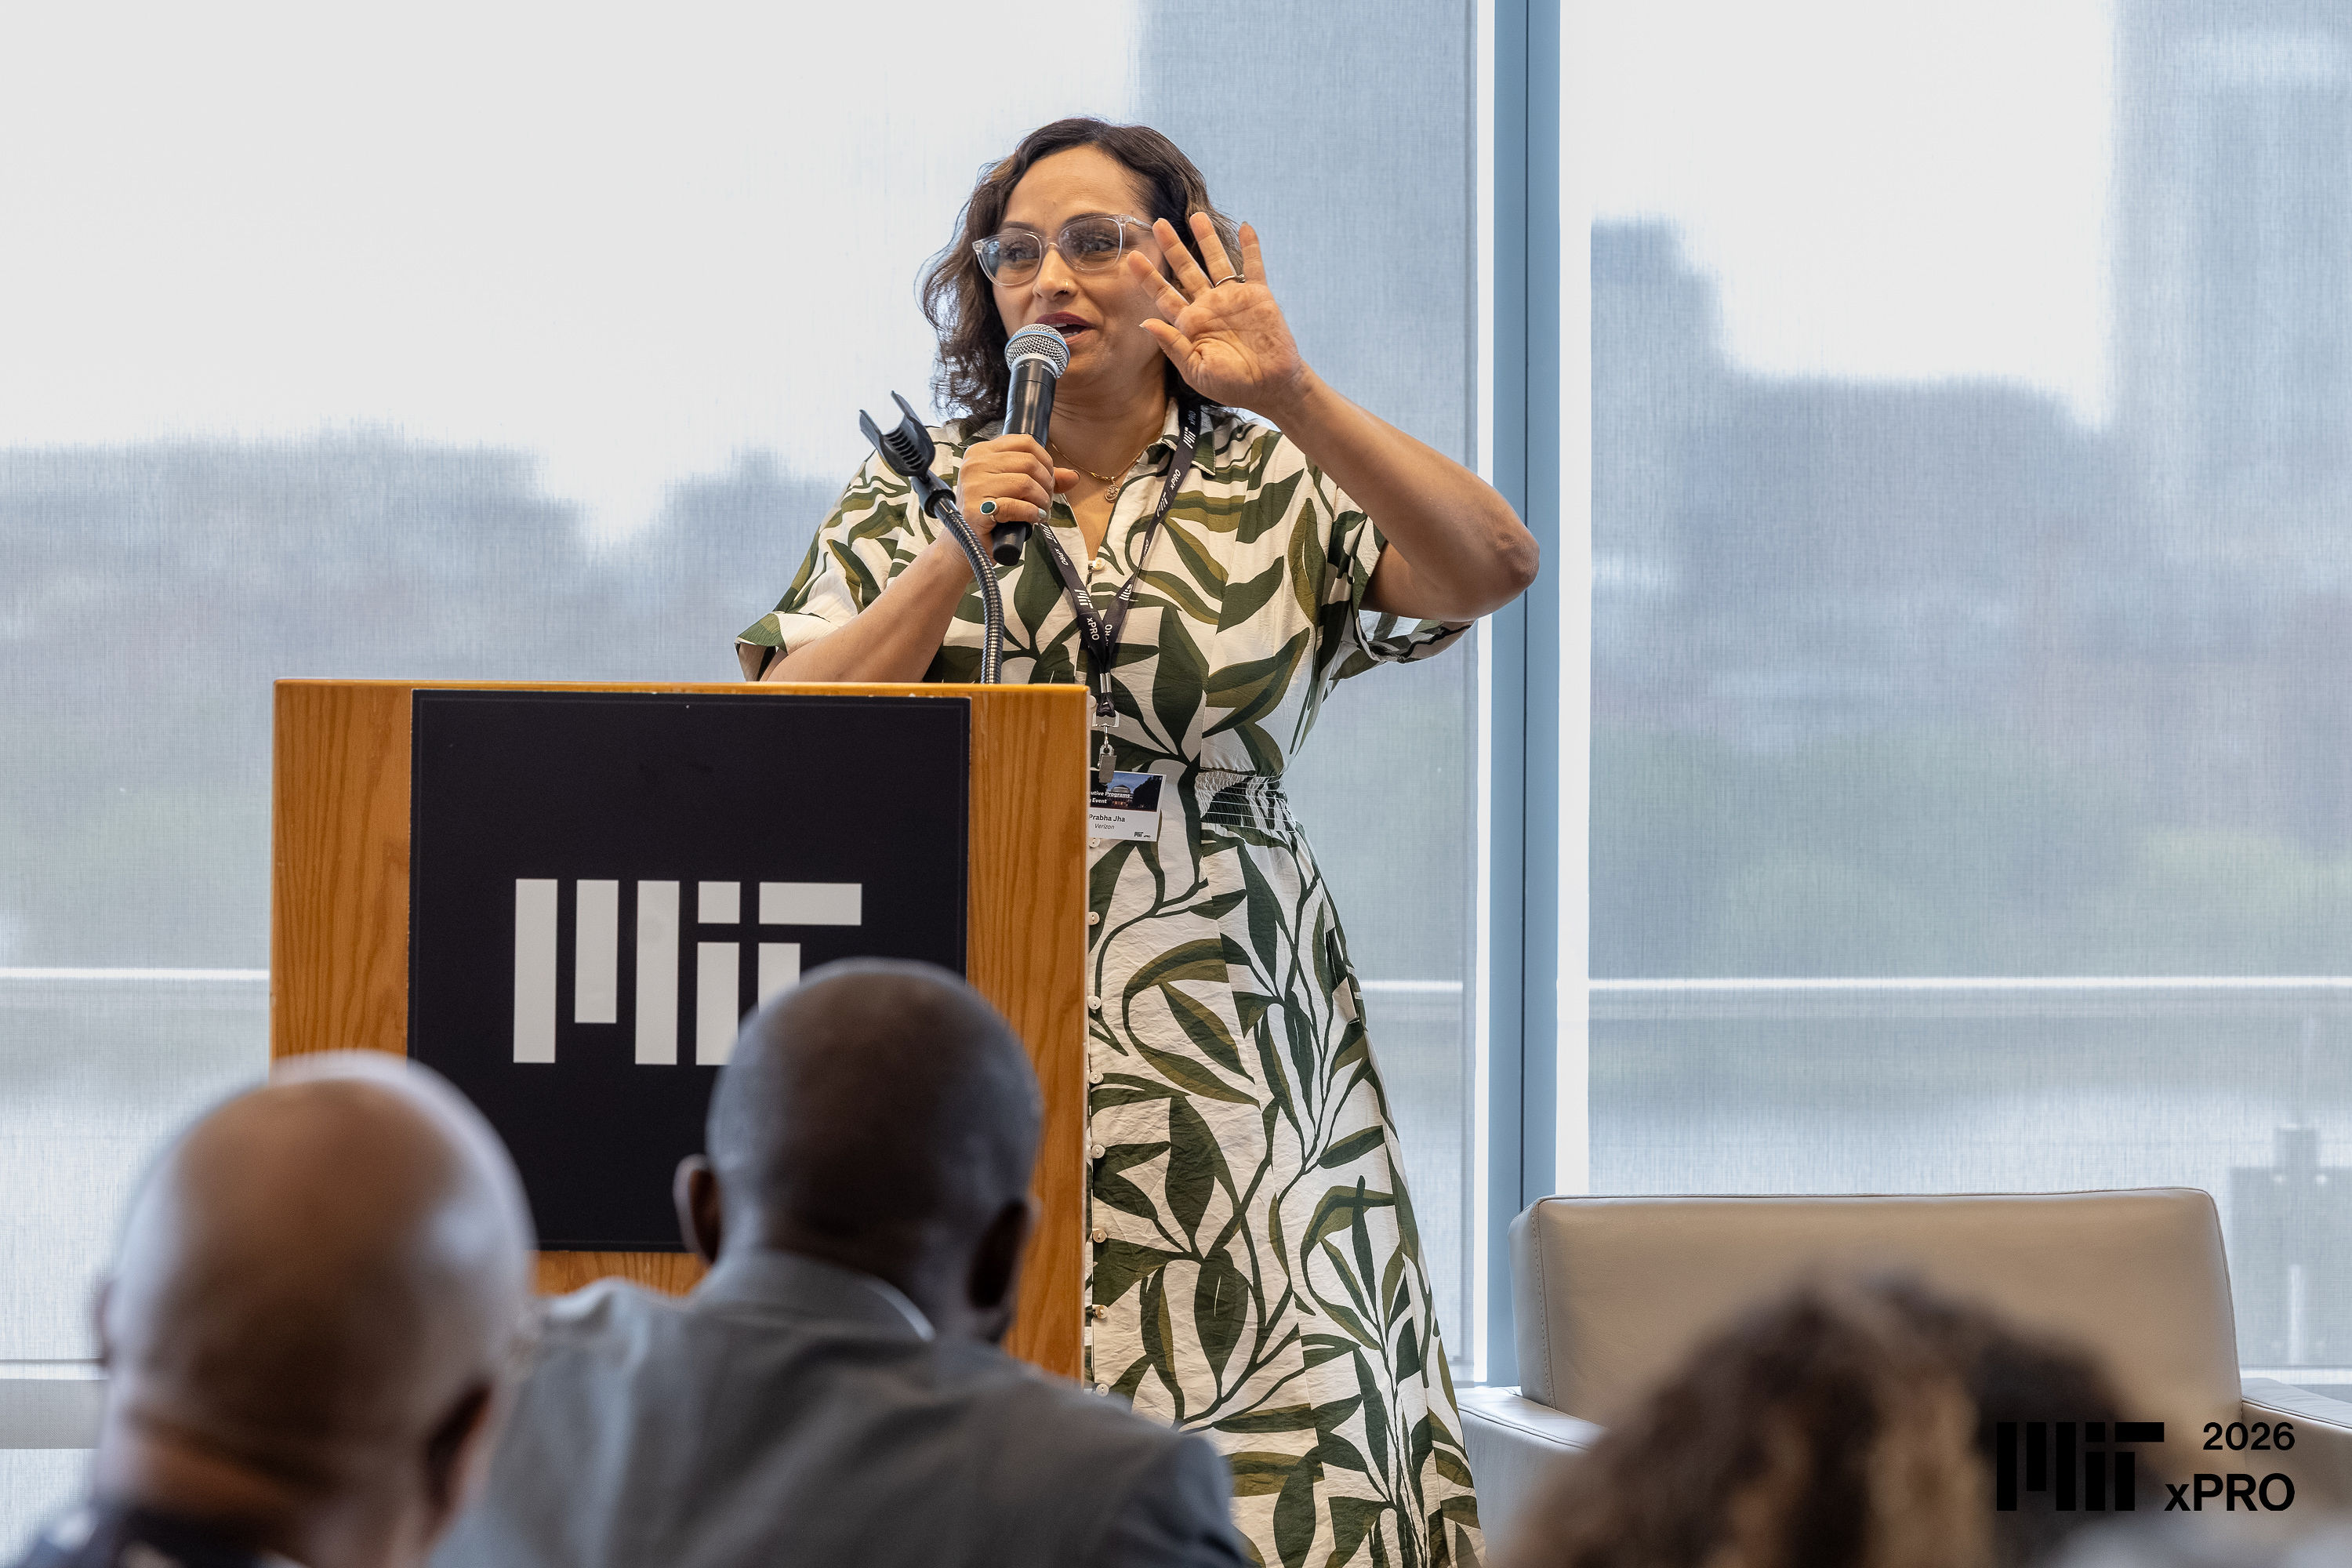
Prabha Jha used her experience with MIT Open Learning’s program for senior executives to develop AI solutions for her employer, Verizon, and to write a book.
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.