QDL Research Suite QDL Research Suite is a free, open-source Python package that brings together tested computational and reproducibility tools from the Quantum Diverter Loop (QDL) research program. It is designed to help researchers verify, reproduce, inspect, and reuse advanced mathematical, statistical, and computat...
Roshankumar chandaliya· Zenodo (CERN European Organi...· 0 citations
A free, portable, offline Windows application that calculates length/height-for-age, weight-for-age, and BMI-for-age z-scores (standard deviation scores, SDS) and percentiles for children and adolescents from a CSV file. No installation is required: download and extract AnthroZ_Calculator_v6.0_Windows_App.zip, keep its...
José G. B. Derraik· Zenodo (CERN European Organi...· 0 citations
Exact, reproducible software for deterministic lexicographic flow allocation on lossy, capacitated rooted trees, and for the inverse rehabilitation-design problem posed on the same model. The allocation module implements the three-stage lexicographic model of the AppliedMath article Three-Stage Lexicographic Allocation...
Adilbay Kudaybergenov, Anvar Kabulov, Mukhabbad Kazimbetova et al.· Zenodo (CERN European Organi...· 0 citations
Corrective evidence for Training adequacy and evaluation populations in remaining useful life benchmarks: 96 primary fits, two numerical-scale diagnostics and nine additional budget checks. All original prediction prefixes were reproduced exactly and every extended fit stopped by validation patience before the threefol...
Siyu Cai· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
This dataset supports the structure-guided analysis of the MFN2 C-terminal modulator surface in the review "Conformational allocation of mitofusin 2 in neuronal mitochondrial dynamics: mechanisms and therapeutic targeting". It contains receptor and ligand coordinates, docking configurations, raw poses and logs, solvent...
Zhiyuan Zhang, Boquan Qin, Shizhou Wu et al.· Zenodo (CERN European Organi...· 0 citations
Repository Description This repository contains all data, computational outputs, and analysis scripts used for the ExFiT study: Ensemble-based Excited-State Character Fingerprinting across Temperatures. It provides equilibrium geometries, finite-temperature Wigner ensembles, quantum-chemical outputs, excited-state desc...
A. Roy, Jacek W. Waluk, Daniel T. Gryko et al.· Zenodo (CERN European Organi...· 0 citations
This version (2026-09-26) corrects a citation error found by an automated check and confirmed by hand against the arXiv abstracts. Version 2 cited the identifier 2607.07314, an unrelated federated-learning paper posted after this synthesis was drafted, for the quantum software debugging paper that notes quantum bugs "o...
Saluca Agentic AI Research Team· Zenodo (CERN European Organi...· 0 citations
Version 3 (2026-09-26) corrects a citation error in versions 1 and 2 and a false correction added in version 2, found by an independent audit and confirmed by re-checking every cited arXiv abstract. The inference-system fingerprinting findings, one of the four topics named in the title, were cited to arXiv:2605.29960;...
Saluca Agentic AI Research Team· Zenodo (CERN European Organi...· 0 citations
Description Model outputs required to run the test suite of the pyTMD tide prediction software. Disclaimer All models are owned and maintained by their developers. pyTMD is only licensed to use these models for scientific use and is not responsible for their upkeep. Please cite the original reference for each model if...
Tyler Clark Sutterley· Zenodo (CERN European Organi...· 0 citations
Evaluation frameworks turn model outputs into the scores that benchmarks, leaderboards and deployment decisions rely on, and the scoring code itself also requires direct checks. We test four evaluation frameworks (DeepEval, TruLens, lighteval and HELM) and one metrics library (TorchMetrics) with three checks: does a sc...
Jared Condon· Zenodo (CERN European Organi...· 0 citations
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
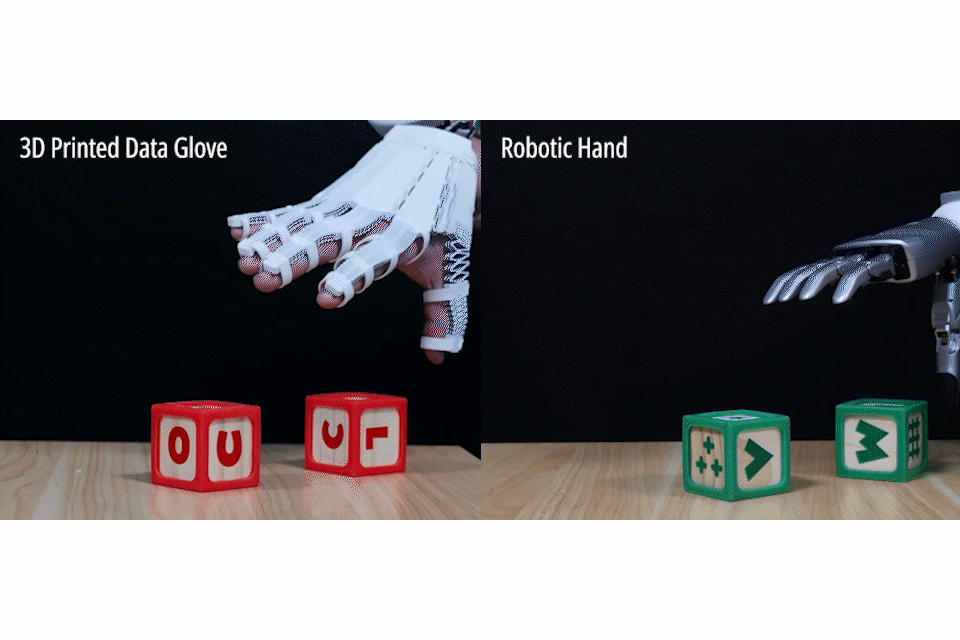
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
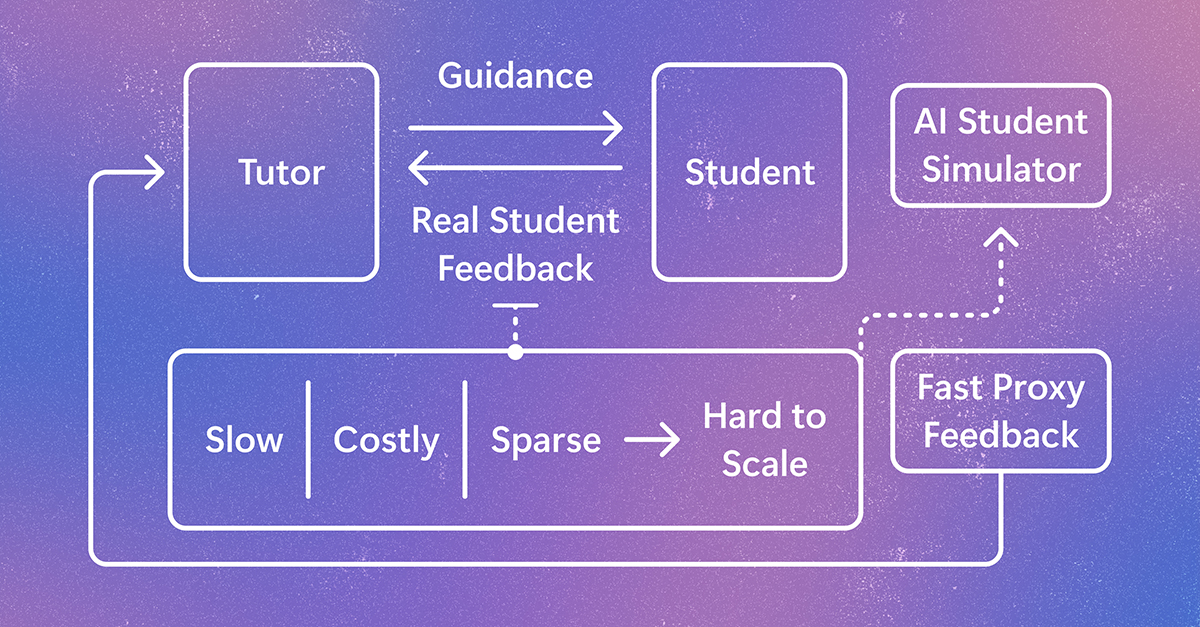
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.