This software implements a controlled, post-hoc workflow for evaluating both the predictive accuracy and the functional behaviour of two-input machine-learning surrogate models. It starts from a normalised analytical table and provides strict input validation, deterministic model fitting, held-out and reconstruction me...
Mateusz Żeruń· Zenodo (CERN European Organi...· 0 citations
UDCF Instrumented Pendulum Cutting Rig v3.1 The repository contains the source code for the UDCF Instrumented Pendulum Cutting Rig v3.1. This simulator serves as a Digital Twin, allowing researchers to predict severance success (η ≥ 1) or sub-critical impact based on the kinematic energy of a swinging pendulum. Version...
Clifford Yeboah· Zenodo (CERN European Organi...· 0 citations
Companion archive for the paper "Product-Level Test Generation from Featured Transition Systems", accepted at the 17th IFIP International Conference on Testing Software and Systems (ICTSS 2026) and published in the Springer Lecture Notes in Computer Science series. The archive collects the unabridged experimental table...
AILEE Trust Layer — V8.1 Release Note (Calibration + Hardened Brooks Domain Validation) Date: September 16, 2026 Author: Don Michael License: MIT Location: Warrington, PA Disclaimer: This release note describes independent exploratory work. It is not acknowledged, approved, or endorsed by Brooks Instrument and does not...
Don Michael Feeney· Zenodo (CERN European Organi...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
This replication package provides complete implementations to fully reproduce the experiments from our paper Reconstructing Objects for Software Testing.
Ketai Qiu, Luca Di Grazia, Alessio Gambi et al.· Zenodo (CERN European Organi...· 0 citations
Document 74 // Monograph Series on Causal Inertia & Epistemic Governance Author: Marius Egerhei Torjusen (ORCID: 0009-0006-0431-6637) Affiliation: Chief Architect, ReismannPoint Systems // Brahman Ventures (Locus Zero Research Division, Risør, Norway) Series Lineage: Direct operational, mathematical, and physical succe...
Torjusen Marius Egerhei· Zenodo (CERN European Organi...· 0 citations
Document 74 // Monograph Series on Causal Inertia & Epistemic Governance Author: Marius Egerhei Torjusen (ORCID: 0009-0006-0431-6637) Affiliation: Chief Architect, ReismannPoint Systems // Brahman Ventures (Locus Zero Research Division, Risør, Norway) Series Lineage: Direct operational, mathematical, and physical succe...
Torjusen Marius Egerhei· Zenodo (CERN European Organi...· 0 citations
A large-scale empirical study of quality assurance (QA) practices in 157 open-source LLM-based agent projects with at least 100 GitHub stars highlights the need to move beyond feature-level testing toward systematic end-to-end validation that ensures agent workflows remain within intended boundaries when interacting wi...
Wu-Yang Dai, Moses Openja, Jiho Shin et al.· 0 citations
C++-Eval: A C++ Evaluation Benchmark for Large Language Models C++-Eval is a comprehensive benchmark for evaluating the C++ code generation capabilities of Large Language Models (LLMs), with a focus on complex memory management and industrial-grade software engineering requirements. Dataset Statistics 200 multi-level C...
LZX-zx-em· Zenodo (CERN European Organi...· 0 citations
The proposed computer vision framework represents a cost-effective advancement in surgical digitisation, enabling accurate instrument tracking using standard video data and supporting future optimisation of orthopaedic surgical practice with significant implications for clinical research.
M. Paraskevaidis, David Alexander Back, Elian Niklas Oudintsov et al.· Surgical Innovation· 0 citations
It was found that the velocity is positively affected by higher values of porosity and Reynolds number, particularly in the case of wall deformation, while the temperature distribution behaves the opposite way as it is affected by wall injection and suction under higher Reynolds number and porosity conditions.
Shuang Li, Muflih Alhazmi, S. Hilali et al.· SLAS technology· 0 citations
Use case flows are important elements of use case modeling because they support downstream software engineering activities, including requirements analysis, architectural and detailed design, and test case generation. However, constructing them manually is costly and expertise-intensive, while existing automated approa...
Guang-Yu Wang, Bang-Qi Li, Ji Wu et al.· 0 citations
Is your company’s AI sovereign? A practical guide for CIOs on AI vendor lock-in, EU Data Act switching, cloud sovereignty, and testing your exit plan before you need it. The post Sovereignty Is the Option to Leave appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
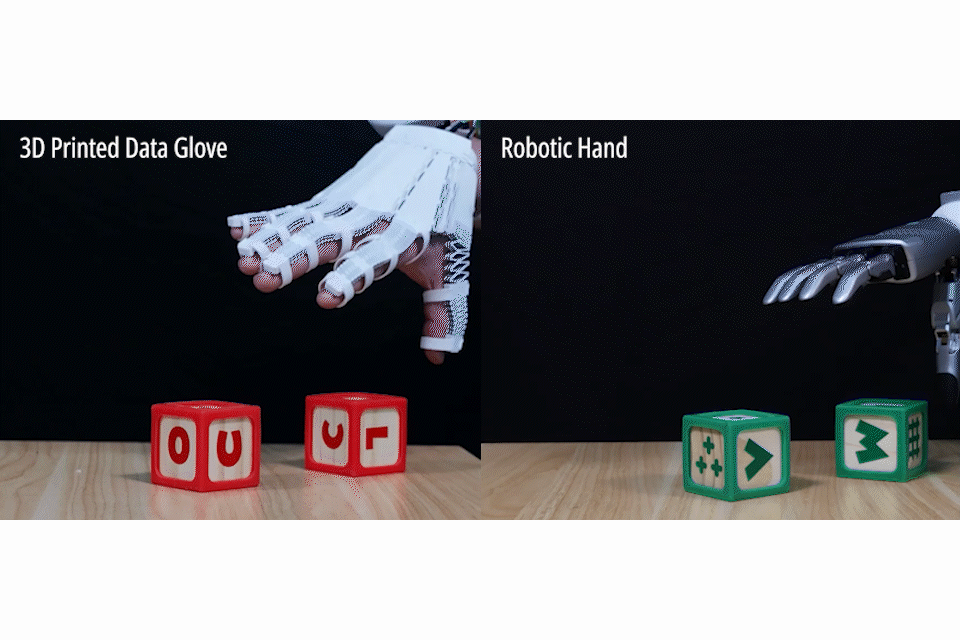
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.