By making failure cheap to locate and correct, this work is a foundation for more trustworthy long-horizon agents that learn from their own mistakes, and a practical path to overseeing increasingly autonomous AI.
Salman Rahman, Y. Kim, Mihir Parmar et al.· 2 citations
This project verified that generating robust and reliable software using agentic AI requires careful practice and human supervision and demonstrated that using agentic AI workflow for software development (with its prompts and skills) can become a specification of the code that leads to cost-effective sustainability of...
Ayesha Shafique, Barton P. Miller, E. Heymann· 0 citations
heteroTests is an R package for heteroscedasticity diagnostics in linear-model workflows. It provides a consistent interface for classical variance diagnostics including White, Breusch-Pagan, Koenker, Goldfeld-Quandt, group-wise variance tests and ARCH-related checks, together with streaming implementations, simulation...
Diogo Ribeiro· Zenodo (CERN European Organi...· 0 citations
Abstract Minimal establishes the complete operational criterion for deleting information while preserving every admissible finite-horizon test and task value, and turns that criterion into exact certificates and executable reductions. More than one hundred independently screened and frozen suites were evaluated under c...
Bsmpx· Zenodo (CERN European Organi...· 0 citations
Artifacts for "Assessing Postcondition Completeness in Auto-Generated Function Contracts for Software Verification" submission for SAST 2026. Caio Vinícius Pereira Silveira and Mateus Felipe Tymburibá Ferreira. 11st Brazilian Symposium on Systematic and Automated Software Testing. SAST 2026. September 8--11, 2026, São...
This archive contains the derived data, harmonised labels, frozen evaluation splits, and complete numerical results supporting the study "Global maps overstate the reliability of blue-carbon credits." It provides everything required to reproduce every figure and number in the paper, and a reusable benchmark for testing...
Md. Rakib Hasan· Zenodo (CERN European Organi...· 0 citations
Sixth Edition, September 2026. Proposes minimum standards for evaluating Bitcoin consensus-change proposals: submission requirements, tiered minimum review periods, code-audit standards, activation-threshold floors backed by a quantified chain-split risk model grounded in the double-spend / gambler's-ruin literature (N...
Trace-IN625 is a source-aware, literature-derived dataset of tensile properties and supporting microstructure information for additively manufactured IN625. It organizes published measurements into individually retrievable material-condition records, preserving source references, processing and heat-treatment informati...
Heyu Song, Jinlai Xiang, Minchen Liao et al.· Zenodo (CERN European Organi...· 0 citations
Topological String-Gradient Theory (TSGT): Autonomous LLM Stress-Test and Critical Reconstruction Author’s Context: Let’s be completely transparent about what this manuscript actually represents. While earlier drafts of TSGT were hand-iterated and driven by my own intuitive theoretical concepts, this release is the res...
Mustafa Karatüm· Zenodo (CERN European Organi...· 0 citations
Fixed (unified_math) [breaking] replace From bounds with FromPrimitive, add software-scalar tensor ops Other (deep_causality_par) Pin the fan-out, the serial bound, and the untested configuration (deep_causality_file) Repair the three audited test defects and close the gaps behind them
Marvin Hansen· Zenodo (CERN European Organi...· 0 citations
Is your company’s AI sovereign? A practical guide for CIOs on AI vendor lock-in, EU Data Act switching, cloud sovereignty, and testing your exit plan before you need it. The post Sovereignty Is the Option to Leave appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comOct 30, 2026
Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.
Microsoft Research Blog· microsoft.comOct 29, 2026
Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.
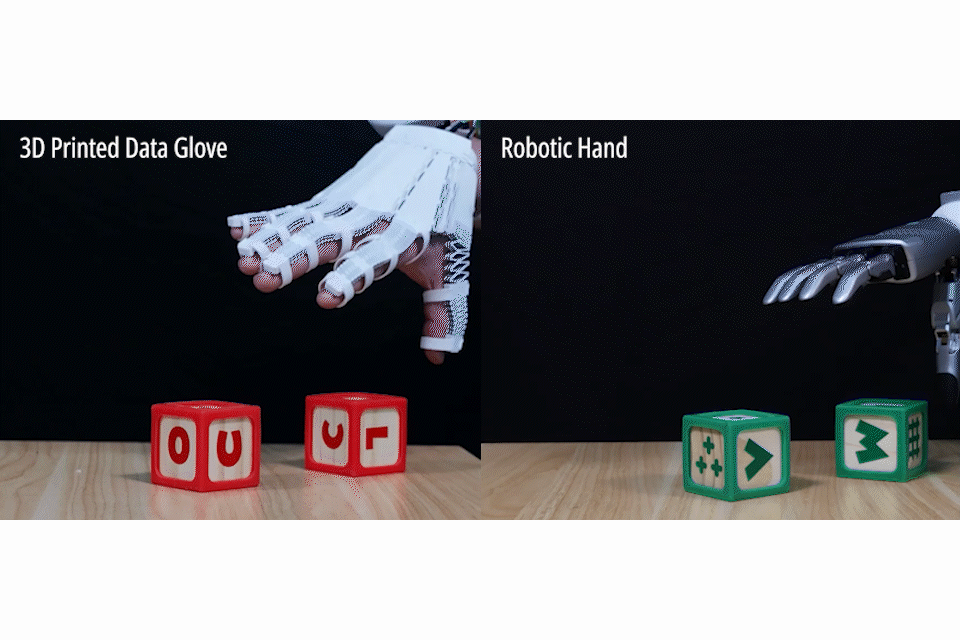
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.