Under this model, generative components ground test intent at authoring time into reviewable artifacts, rather than re-evaluating locators during every test run, and semantic agreement is achievable but not automatic: nine of twenty guarantee-surface pairs resolve.
Simarjot Khanna· Proceedings of the 1st Inter...· 0 citations
Applying large language models (LLMs) to regulated domains such as financial and legal compliance is fundamentally a software engineering problem: an answer produced from a model’s parameters is, at the surface, indistinguishable from one grounded in the authoritative source, yet only the latter can be audited. Prior s...
Monalisha Ojha, P. Mishra· Proceedings of the 1st Inter...· 0 citations
Eight lessons from six months of developing CHERI-PIT, an LLM-agent pipeline that ports C/C++ projects to the memory-safe pure-capability (purecap) ABI of CHERI hardware on Arm Morello, trace a path toward a porting tool that emits reproducible and auditable port recipes.
Noam Benkler, Steven Johnston, D. Lide et al.· Proceedings of the 2nd Inter...· 0 citations
Parity testing validates software modernization: the legacy system supplies every expected output, so the oracle is sound. One decision is delegated, increasingly to a language model and often the very model that translated the code: which inputs to try. How much divergence such suites let through is unmeasured, and wh...
Simarjot Khanna· Proceedings of the 2nd Inter...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
This vision paper argues that trustworthy AI-assisted software engineering requires behavioural accountability: making implicit assumptions explicit, surfacing behavioural violations, and producing auditable evidence for developers and CI pipelines.
Radosław Klimek· Proceedings of the 1st Inter...· 0 citations
Viewing trustworthy automation through this governance perspective reveals two complementary governance responsibilities: Before automated execution, trustworthiness objectives must be systematically operationalised into lifecycle artefacts that guide or constrain engineering behaviour and after execution, operational...
C. Braga, Manuel A. Serrano, E. Fernández-Medina· Proceedings of the 1st Inter...· 0 citations
This paper argues that AI and program analysis are not competing technologies but complementary capabilities, and envision enterprise software engineering as a collaboration in which program analysis provides evidence, AI provides intelligence, and human engineers contribute the judgment and wisdom required to build tr...
Vini Kanvar· Proceedings of the 2nd Inter...· 0 citations
GRAML, a framework that combines graph evidence, vulnerability description generation, and multi-task training, is proposed, and practical guidance for building more reliable and secure software engineering systems with large language models is provided.
Ruo-Han Li, Miao-Qing Tian, Hai-Peng Qu et al.· 0 citations
Large language models equipped with development environments have moved code generation toward repository-scale construction, yet building complete repositories remains difficult because interacting modules, interfaces, configurations, tests, and dependencies must work together. We introduce Code Primitives, agent-nati...
Hai-Bo Jin, Peng Kuang, Xu-Chen Yu et al.· 0 citations
Multiphysics continuum models are powerful tools for studying electrochemical devices, enabling in silico reactor design and resolution of local pH, potential, and concentration fields that govern device performance but are difficult to measure experimentally. However, constructing such models requires substantial nume...
Sebastian Castro, Maya Schuchert, Spencer A. McCluskey et al.· 0 citations
The evaluation of coding agents generally strives to be as realistic as possible. In our study, we collect 4,782 agent sessions of real software engineers in JetBrains IDEs, which we call Production Sessions. Since our subject is interactive agents, we study the sessions with at least three user messages (33% of the sa...
I. Slinko, Yaroslav Golubev, Sergey Titov· 0 citations
Public R analysis source accompanying the manuscript “Serum Trace-Element Categories and Reported First-Degree Family History of Malignancy: An Exploratory Analysis of the SPES Cohort.” This release contains the original MAIN, P95 and malignancy-category analytical branches; referee-requested revision modules; classifi...
Buonerba Carlo· Zenodo (CERN European Organi...· 0 citations
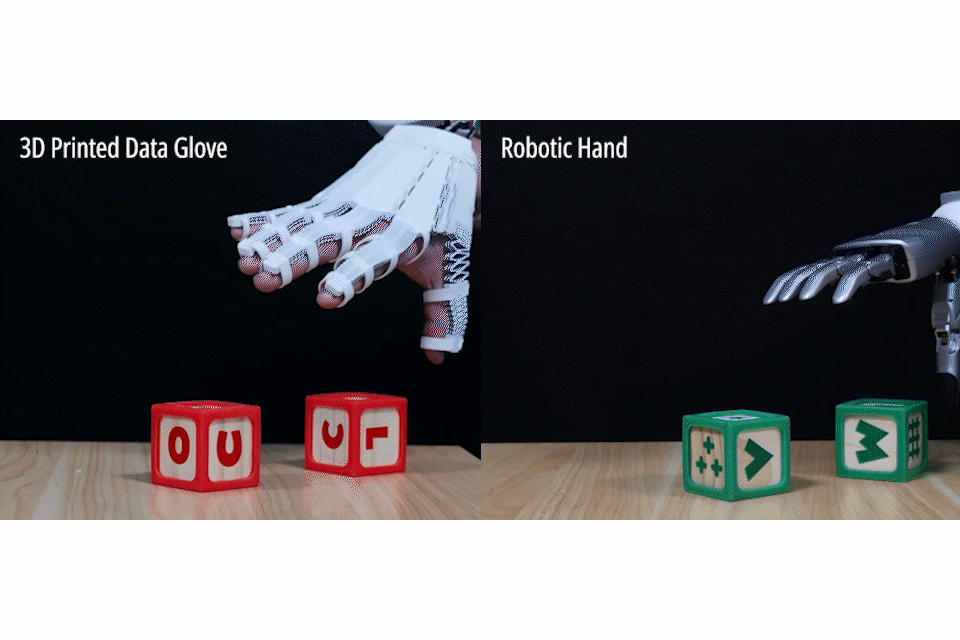
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
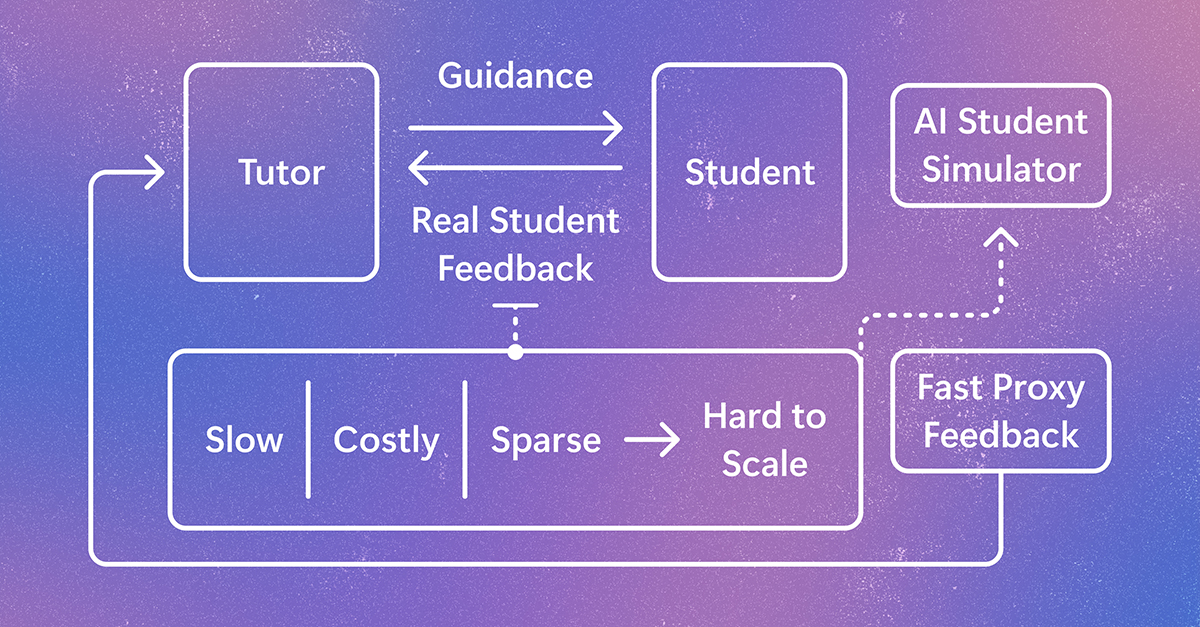
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
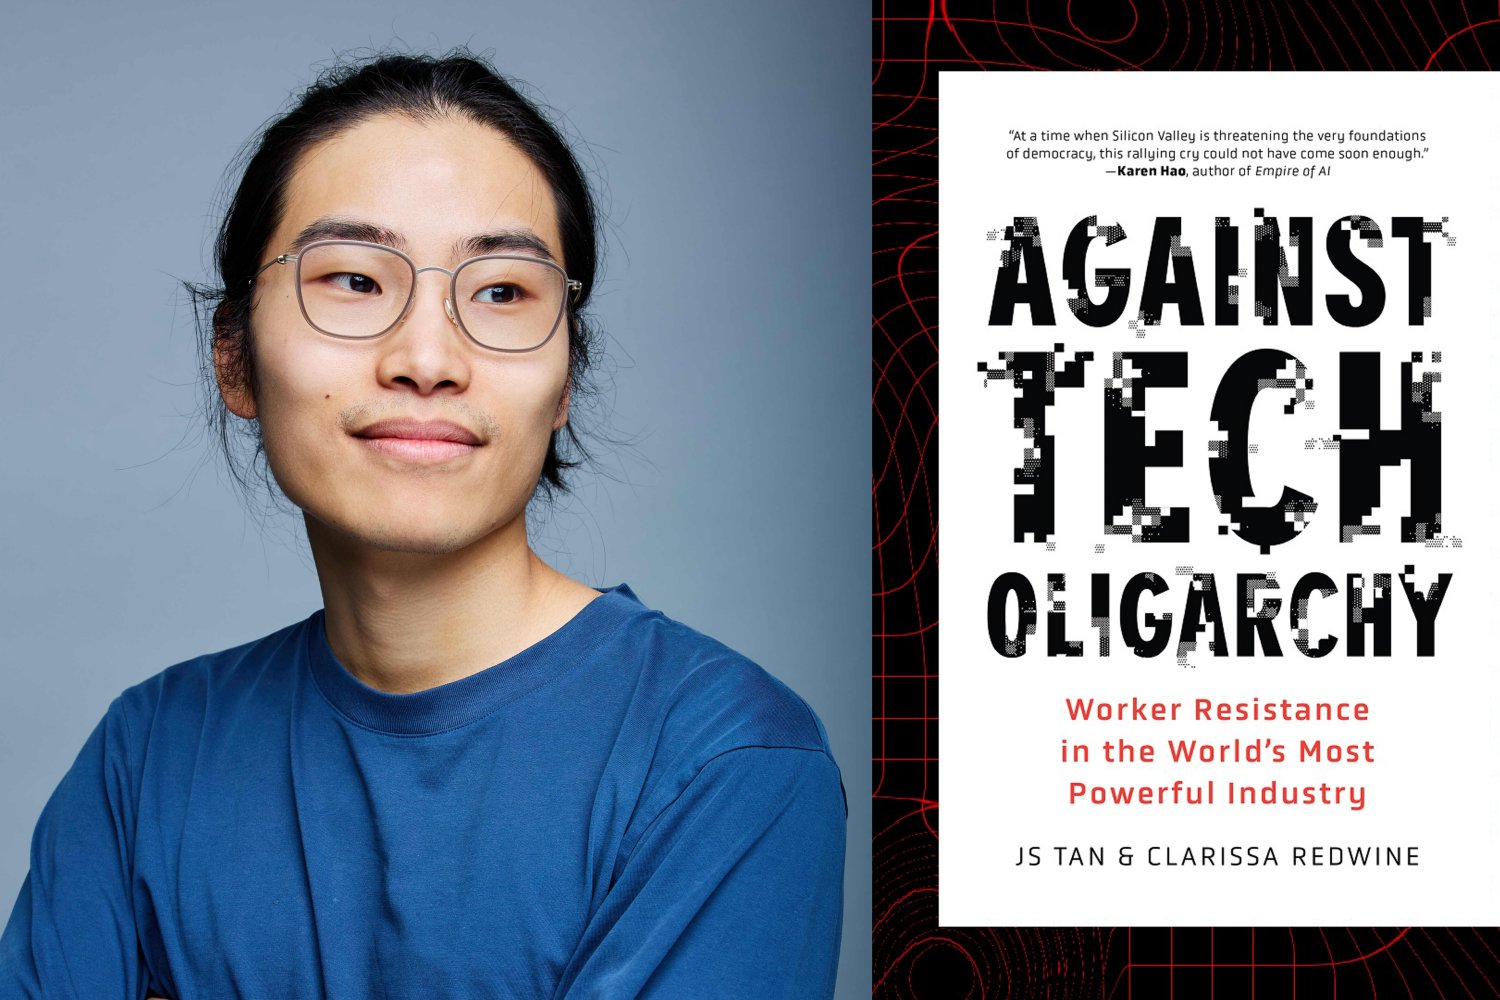
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.