Code, configurations, seeds, results and figures for a Monte Carlo simulation study of composite multi-beat, multi-view transoesophageal echocardiographic measurement rules for tricuspid regurgitant jet dimensions (beat averaging, percentage beat-consistency windows, largest view mean, millimetre cross-view triggers) a...
Kardokh Kakabra· Zenodo (CERN European Organi...· 0 citations
Software development is moving away from writing code line by line. Instead of using AI only for simple autocomplete, developers now manage multiple coding agents across different parts of a codebase at once. While these tools make individual tasks faster, recent data shows that teams are generating far more code witho...
Passive Time Difference of Arrival (TDoA) localization conventionally requires multiple synchronized receivers to obtain spatially diverse observations. In this paper, we show that the periodic nature of the 5G NR downlink Positioning Reference Signals (PRS), combined with receiver motion, provides an alternative sourc...
Marco Tricco, Samuele Zanini, Giuseppe Bianchi et al.· Proceedings of the 20th ACM...· 0 citations
Robotic vehicles, such as Unmanned Aerial Vehicles (UAVs), are deployed in safety-critical applications ranging from package delivery to search and rescue operations. In these cyber-physical systems, software vulnerabilities can cause physical consequences such as collisions and mission failures, giving them direct saf...
Ashwin Nambiar, Shafiq-us Saleheen, Antonio Bianchi· Proceedings of the 2026 8th...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
FlowAgent is an AI agent deployed at Google to automatically repair test failures in the pre-submit outer-loop workflow inside continuous integration systems, using a ReAct-style generate-and-validate loop and rigorous pre-execution and post-execution abstention filters to ensure high-quality suggestions under strict l...
Celal Ziftci, Spencer Greene, Raymond Liu et al.· Proceedings of the 41st IEEE...· 0 citations
SIGMA is proposed, a data generation and training pipeline enabling alignment self-improvement that generalizes to out-of-distribution settings and shows that a Model Spec balancing harmlessness and helpfulness, test-time reasoning for safety deliberation, and high-quality rubrics from SIGMA's task designer agent are c...
Jing-Yu Zhang, Shruti Palaskar, Daniel Khashabi et al.· 0 citations
A case study of a production healthcare platform built through coding agents and governed by an operator without formal software-engineering training, which found that tests, monitors and reviewing agents used to supervise the system were fallible.
This work proposes Failure-Driven Prompt Refinement (FDPR), a methodology that analyzes recurring model failures to guide evidence-based prompt refinement, and shows that failure-driven refinement improves the reliability of LLM-based vulnerability analysis while yielding reusable prompt design principles.
OBJECTIVE
The use of cell free fetal DNA has expanded to include autosomal dominant single gene conditions (cfDNA-SGD). Our aim is to estimate the cost-effectiveness of a cfDNA-SGD panel in a general obstetric population as compared to offering this test only in the setting of anomalies.
METHODS
Using TreeAge softwar...
M. Bunnell, Claire Packer, Sophie Adams et al.· Prenatal Diagnosis· 0 citations
Objectives This study aims to investigate the potential relationship between radiomic features extracted from 18F-fluorodeoxyglucose (18F-FDG) positron emission tomography (PET)/computed tomography (CT) images of patients with breast cancer and molecular markers including estrogen receptor (ER), progesterone receptor (...
Busra Aydur Puren, Semra Usta, Y. Salihoğlu et al.· Molecular Imaging and Radion...· 0 citations
Large language models (LLMs) equipped with terminal access have demonstrated strong capabilities in automating software engineering tasks. However, existing agents remain brittle on long-horizon workflows, where they must repeatedly reconstruct program state scattered across source files, configurations, tests, depende...
Hai-Bo Jin, Xin-Jie Li, Peng Kuang et al.· 0 citations
Automated Program Repair (APR) with language models is usually evaluated by whether a generated patch passes the test suite, which can hide differences in maintainability, security, and computational cost. We propose a Weighted Quality Index (QI), inspired by the ISO/IEC 25010 software quality model, that combines func...
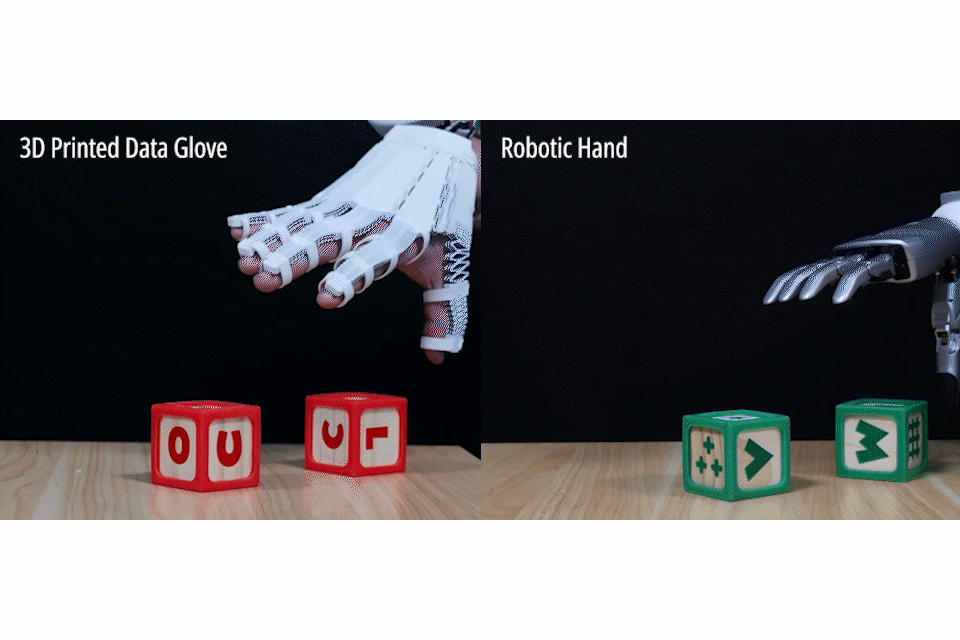
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
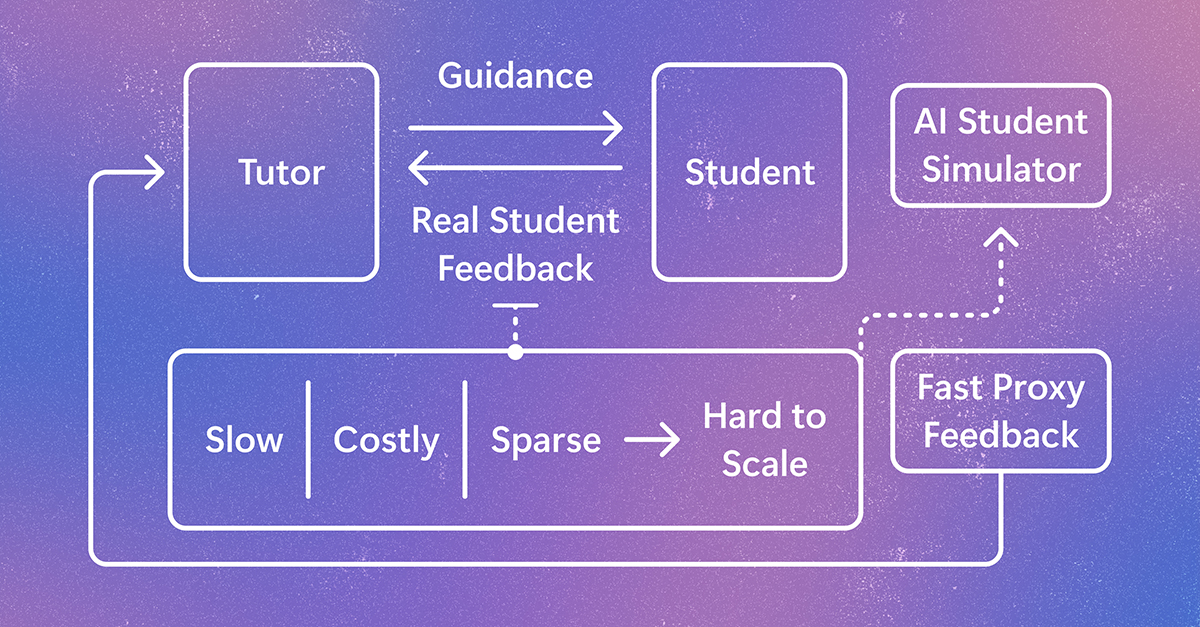
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
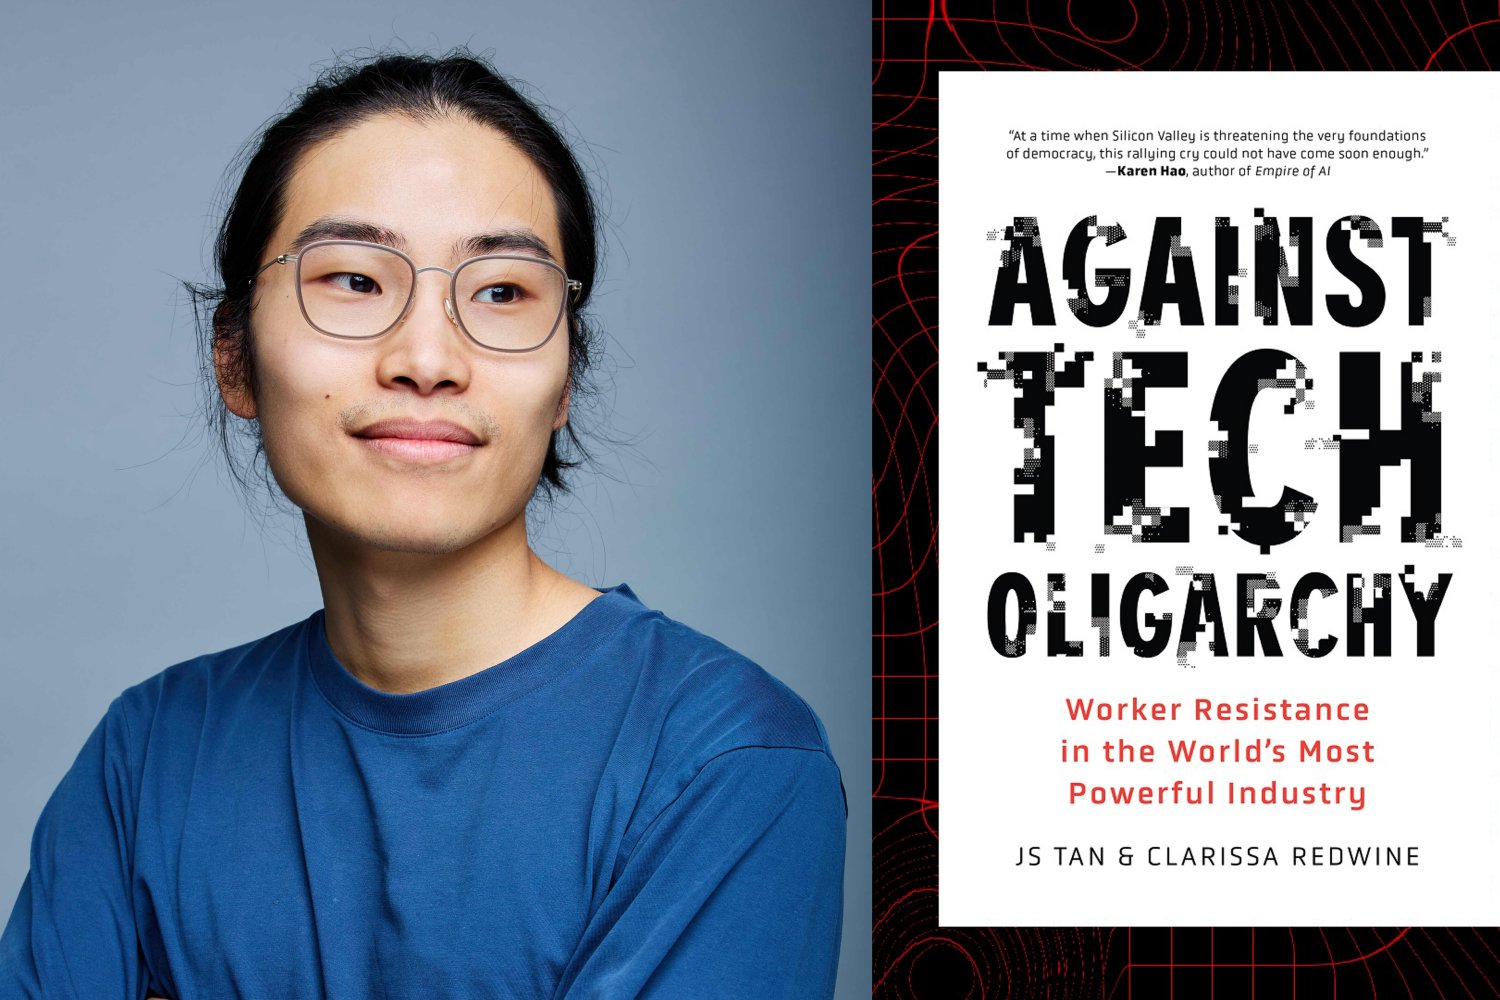
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.