Skip to content
#generative ai #software testing Review Open access

Beyond the Hype: The Efficiency-Throughput Gap with GitHub Copilot

Oct 2026 · Vol 69, pp. 68 - 77 · 0 citations · 21 references

Abstract

Investigating the real-world impact of GitHub Copilot on software engineering, this field study uncovers a critical disconnect between gains in individual developer efficiency and improvements in organizational throughput. Using a multi-method approach, we employed the Organizational Ohm’s Law framework and integrated engineering productivity surveys, GitHub Copilot and engineering metrics data, and participant information. While we observed positive shifts in engineer motivation and perceived skill enhancement, accompanied by decreased working hours, our analysis revealed no statistically significant improvement in engineering metrics such as monthly pull request volume and lines of code produced. Survey data indicated that engineers found GitHub Copilot most beneficial for generating testing scripts, boilerplate code, queries, and configurations, but less effective for intricate coding tasks and essential human-centric enterprise development activities such as communication and process management. This phenomenon, which we term the efficiency-throughput gap, demonstrates that individual efficiency gains did not translate to greater organizational output. Our findings underscore the complexities of realizing immediate productivity gains with generative AI in software engineering and offer crucial methodological insights and empirical results for designing and evaluating future AI-powered product development. A real-world field study examines how GitHub Copilot affects engineering productivity in an enterprise setting.
Read PDF

Similar papers

#software testing Preprint Aug 2026

Benchmarking the Titans: A Multi-Dimensional Empirical Evaluation of LLM Code Generation Quality in the .NET Ecosystem

An automated, multi-dimensional evaluation framework for C# code generation, applying it to four state-of-the-art LLMs: GPT, Gemini, Claude, and Grok is presented and a substantial gap between correctness and quality attributes is revealed.

Seyed Mohammad Mahdi Ghalandarian, Majid Bazargani, Masoumeh Taromirad · 0 citations
Conference Open access Sep 2026

Analyzing the Relationship Between Cloud-Native Architectural Patterns and Software Quality in AI-Assisted Development

Modern software systems are increasingly built as cloud-native, distributed applications, and an increasing share of their source code is now produced with the assistance of large language model (LLM) based coding tools. Both shifts change the way architectural decisions propagate into software quality. To investigate...

G. D. S. R. Gimres, K.Dilshi Divya · 0 citations
Case report Open access Sep 2026

Optimizing Developer Experience for High Performance Engineering: A Roadmap for Enterprises to Reduce Friction, Measure Impact, and Scale Productivity and Software Delivery

How are issues in your development workflow impacting engineering performance? As developer friction, technical debt, and administrative overhead continue to hinder output, Dr. Ibrahim Haddad wrote a new roadmap to help enterprises optimize their developers’ experience and performance. Did you know that developers...

Ibrahim Haddad · 0 citations
Conference Sep 2026

When Enterprise Integrations Fail: 7 Production Lessons from Modernizing Fortune 500 Landscapes

Enterprise integrations rarely fail because of technology. They fail because of architectural decisions, operational blind spots, and assumptions made long before the systems reach production, by which point the assumptions are load-bearing and undocumented. Drawing on 17 years modernizing integration landscapes for Fo...

Rashmi Kumari · 0 citations
Review Open access Aug 2026

Exploring an Invisible Version Control Technique to Reduce the Cognitive Load of Research Workflows

Despite the cognitive demands of research workflow, a critical gap exists in research tools: they force a trade-off between usability and robust data safety. Consequently, researchers rely on manual file management, creating ‘Version Chaos’ (e.g., thesis_v1.docx, final_v5.docx) that imposes severe extraneous cognitive...

A. S. Dilan Gomas, R. Rathnayake · 0 citations
Open access Aug 2026

Evaluating the Efficiency of Open-Source AI Chat Models in Local Deployments

This study evaluates the performance and operational practicality of locally deployed large language models (LLMs) as organizations seek cost-efficient, privacy-preserving alternatives to cloud AI. The objective is to generate workflow-aware evidence that supports informed model selection for automation use cases. Four...

Ida Bagus Kerthyayana Manuaba, Juwono · 0 citations

Related blog posts

Microsoft Research Blog Oct 30, 2026

From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence

Evaluating Microsoft Copilot at enterprise scale requires test data that captures the full complexity of real organizations, yet real enterprise data contains sensitive information that cannot be used for evaluation under any circumstances. The post From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence appeared first on Microsoft Research.

Microsoft Research Blog Oct 29, 2026

Microsoft Research Focus – Edition #97

Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.

Microsoft Research Blog Oct 12, 2026

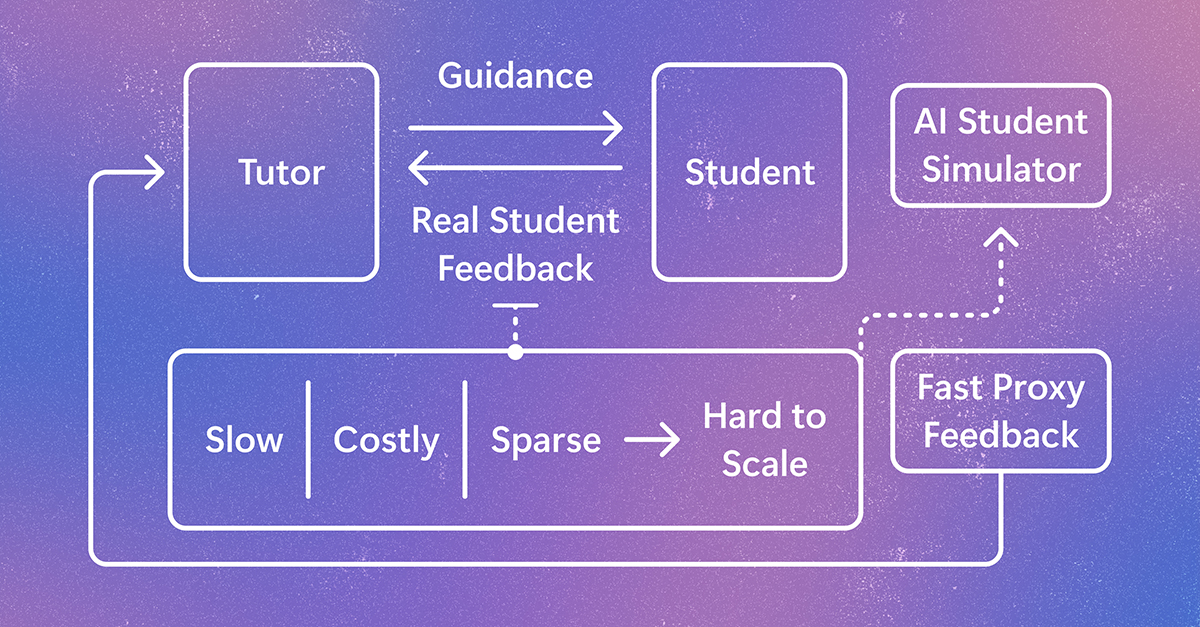
Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.