Oct 2026· IEEE Journal of Solid-State Circuits· Vol 61, pp. 5313-5325· 0 citations· 30 references
Abstract
This article presents an energy-efficient and process-, voltage-, and temperature (PVT)-robust time-domain (TD) compute-in-memory (CIM) macro for edge artificial intelligence (AI) devices. It features: 1) a PVT inner-tracking (PIT) technique that aligns the PVT responses of TD computation and TD quantization, delivering inherent robustness without incurring extra power or circuit overhead; 2) a scalable global timer (SGT) that eliminates standard quantization within the CIM array, enabling scalable precision for varying accumulation sizes while alleviating energy and area bottlenecks; and 3) a reconfigurable pipelined cascading (RPC) mechanism that allows for flexible accumulation sizes without sacrificing utilization and speed, thus narrowing the gap between peak and average energy efficiency. Fabricated in a 28-nm CMOS process, the prototype TD-CIM macro achieves an energy efficiency of 82.2–236.5 TOPS/W in 4-bit mode and 20.4–58.7 TOPS/W in 8-bit mode. Furthermore, the 8-bit mode demonstrates an accuracy loss of less than 1.12% across various networks on ImageNet, even with wide variations in supply voltage and temperature.
SRAM-based computing-in-memory (SRAM-CIM) alleviates the memory-wall bottleneck of the von Neumann architecture, enabling energy-efficient AI edge computing. Current-domain CIM schemes suffer from degraded linearity at low supply voltages, whereas time-domain CIM schemes are highly sensitive to process, voltage, and te...
Xiao-Bo Gong, Bin Qiang, Zi-Li Jiang et al.· IEEE Transactions on Circuit...· 0 citations
The rapid advancement of artificial intelligence (AI) necessitates high-performance computing architecture. While compute express link (CXL) technologies facilitate memory expansion, conventional dynamic random-access memory (DRAM) encounters fundamental limitations in power consumption and scalability. Consequently, 1...
Jehyeok Jung, Munhyeon Kim, Sihyun Kim· Micromachines· 0 citations
The growing deployment of real-time applications on wearable and Internet of Things (IoT) edge devices has intensified the need for energy-efficient, high-performance systems that meet stringent timing and energy constraints. Events-driven architectures leverage the sparsity of real-time to further improve system energ...
Clément Choné, Leslie Xu, Filippo Quadri et al.· 0 citations
Recent advances in in-sensor computing demonstrate the potential of integrating sensing and computation at the perception front end; however, many existing approaches rely on customized devices, facing scalability, uniformity, and power challenges. Here, we present a cross-platform in-sensor computing strategy that emb...
Ming-Qiang Wang, Hui Yu, Ben-Shan Wang et al.· Nature Communications· 0 citations
Resistive memory technologies offer a compelling advantage for in-memory computing. However, realizing a device architecture that simultaneously achieves high computational precision, efficiency, and density has remained elusive due to inherent trade-offs among these performance metrics. Here, we introduce a com- pact...
G. Syed, Loris Coccia, V. Jonnalagadda et al.· 0 citations
We present the first implementation of the analog gradient accumulation with dynamic reference (AGAD), reported as the most advanced and highest-performing version of the TT (Tiki-Taka) algorithm, on an HfO2-based resistive random-access memory (RRAM) array for analog neural network training. Through comparative simula...
Ji-Min Lee, Paul Solomon, N. Gong et al.· Science Advances· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
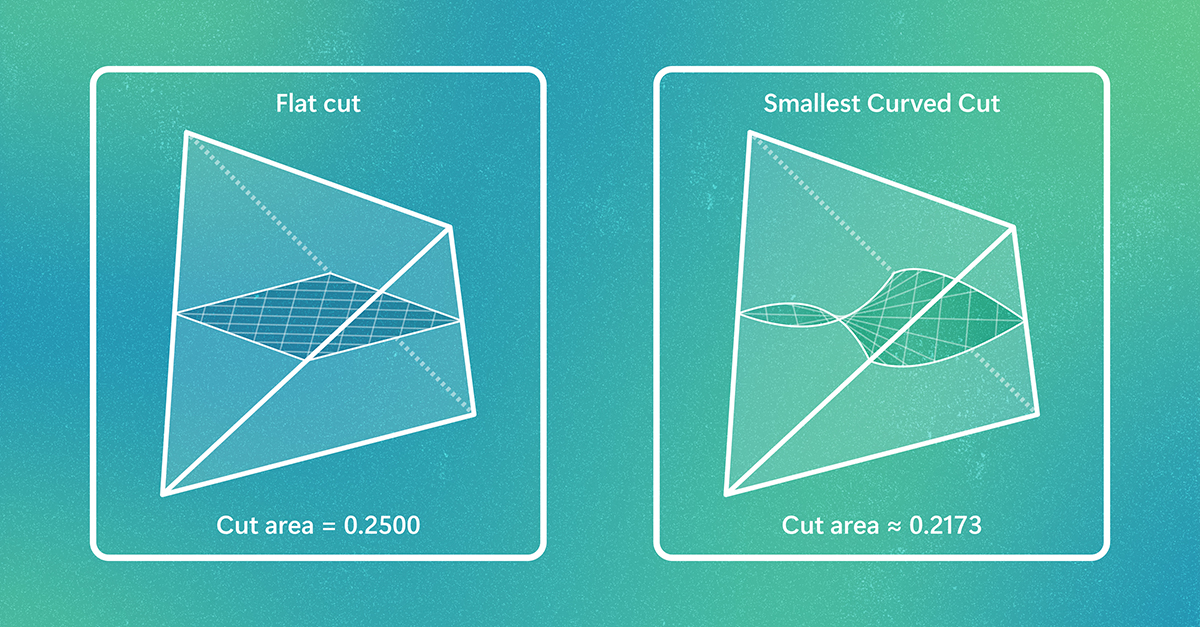
For decades, a fundamental question about the difficulty of computing in high-dimensional spaces has resisted proof. New research resolves this question, removing a major theoretical obstacle to understanding the efficiency of randomized algorithms used across science and computing. The Kannan–Lovász–Simonovits (KLS) conjecture was proposed in 1995. It asks whether, for a broad class of high-dimensional […] The post Solving a 31-year-old grand challenge in mathematics – the KLS conjecture appear…
MIT News · Artificial Intelligence· news.mit.eduOct 15, 2026
A new computational approach reveals how cells communicate to assemble into tissues. This could accelerate stem cell engineering, improve disease models, and inform therapies.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.