While an unlearned language model may no longer recall a fact directly, the fact often remains recoverable through multi-hop reasoning over related knowledge. Most existing unlearning techniques overlook this vulnerability, targeting facts in isolation while leaving their supporting knowledge intact. To achieve true forgetting, we propose a general deep unlearning framework compatible with existing unlearning algorithms. Our approach adaptively explores both explicit responses and latent internal representations to discover valid reasoning paths, compiles them into a confidence-aware supporting subgraph, and we apply a graph minimum cut to sever all recovery paths while preserving unrelated knowledge. To rigorously evaluate deep unlearning, we introduce a model-specific pipeline that extracts and completes knowledge graphs from raw text, filtering them by calibrated model confidence to reflect what the model genuinely retains. Comprehensive experiments demonstrate that selectively unlearning supporting knowledge yields substantially deeper forgetting than superficial methods while preserving model utility, highlighting that genuine unlearning requires breaking the relational structures that enable factual reconstruction.
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.
Carmine Giardino, Xiaofeng Wang, P. Abrahamsson· International Conference on...· 175 citations· ⚡19
This work investigates the possibilities of using LLMs in a resume screening setting via a document retrieval framework that simulates job candidate selection and finds that the MTEs are biased, significantly favoring White-associated names in 85% of cases and female-associated names in only 11.1% of cases.
This study conducts a case survey study based on the secondary data of the major pivots happened in 49 software startups, and demonstrates that customer need pivot is the most common among all pivot types.
Sohaib Shahid Bajwa, Xiaofeng Wang, Anh Nguyen-Duc et al.· Empirical Software Engineeri...· 127 citations· ⚡15
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
Martin Trust Center Managing Director Bill Aulet introduces Dear Dreamer, a free platform for middle and high school students who want to learn about entrepreneurship.
Microsoft Research Blog· microsoft.comSep 30, 2026
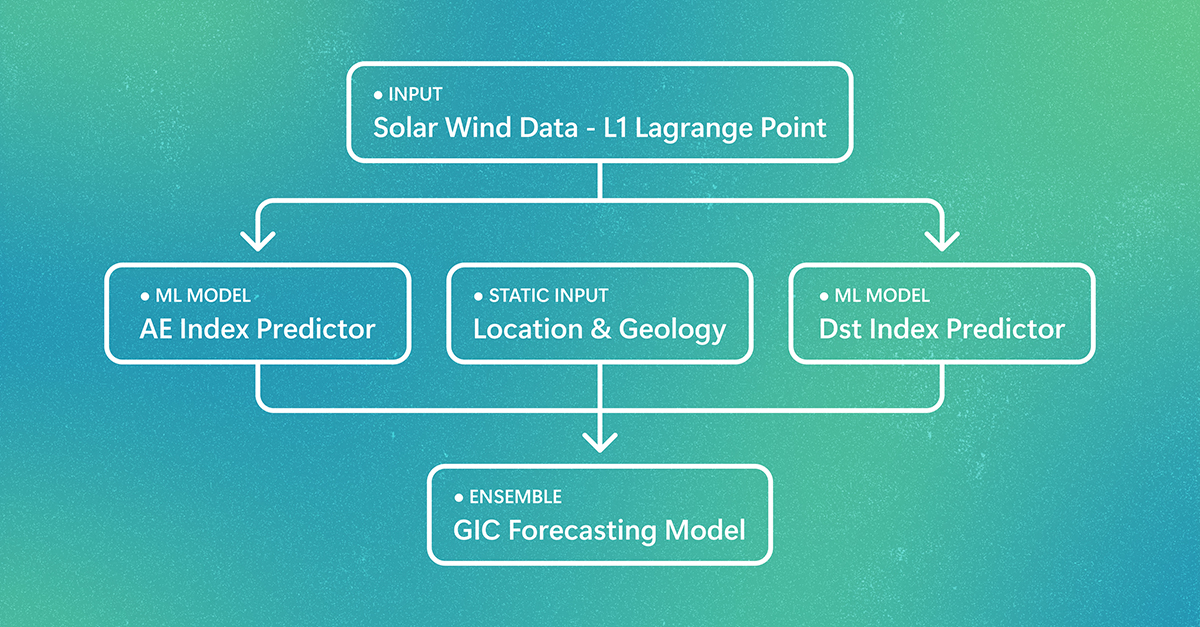
Extreme space-weather events can damage power systems on Earth and degrade GPS accuracy and satellite operations. A new machine learning system can predict where damage is likely to occur 30-60 minutes before a storm arrives. The post Forecasting space weather risks on power grids appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.