Preliminary empirical evidence that single-observation queries are insufficient for evaluations of LLM refusal behaviors is presented, with reliable quantification of refusals required between 15 and 25 repeated queries, well above the single-observation standard common in existing evaluations.
Abstract
We present preliminary empirical evidence that single-observation queries are insufficient for evaluations of LLM refusal behaviors. Using a longitudinal auditing system, we issued identical prompts 100 times each across four dates to GPT-4.1 for two socially salient topics across 20 Wikipedia sources. Refusal outcomes were consistent with a stable Bernoulli process, yet 20\% of sources fell within a decision-boundary region where a single query is largely uninformative. Reliable quantification of refusals required between 15 and 25 repeated queries, well above the single-observation standard common in existing evaluations.
Advisory systems built on large language models should be audited at the disclosure levels users actually reach, and judged across the whole identity space rather than one attribute at a time.
Large Language Models (LLMs) are increasingly used as probabilistic generators for simulation, synthetic data generation, and decision support in settings where real-world data are unavailable. Yet, the structure and reliability of the distributions they produce remain understudied. Here, we systematically analyze LLM-...
Fan Huang, Minsuk Kim, C. Diggans et al.· 0 citations
It is suggested that current LLMs often rely on heuristic arbitration strategies when integrating heterogeneous evidence, highlighting a failure mode for tool-augmented decision systems.
Mattia Carletti, Edward Phillips, Fredrik K. Gustafsson et al.· 0 citations
This work formalizes news-corpus poisoning of probabilistic forecasters, a threat model distinct from prior RAG poisoning, which targets factual answers or opinion polarity rather than calibrated probabilities.
Large language models can generate several records within one autoregressive completion, making earlier answers available as context for later records. This paper shows that such shared-completion batching can distort relationships among variables in the resulting synthetic data, using controlled tests on synthetic sur...
Paired equivalence testing at a declared margin is supply: paired equivalence testing at a declared margin, with certification tables giving the items an evaluation needs, computed from disagreement observed under compression, not from independent-binomial variance.
Amogh Singh· 1 citation
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
MIT News · Artificial Intelligence· news.mit.eduOct 22, 2026
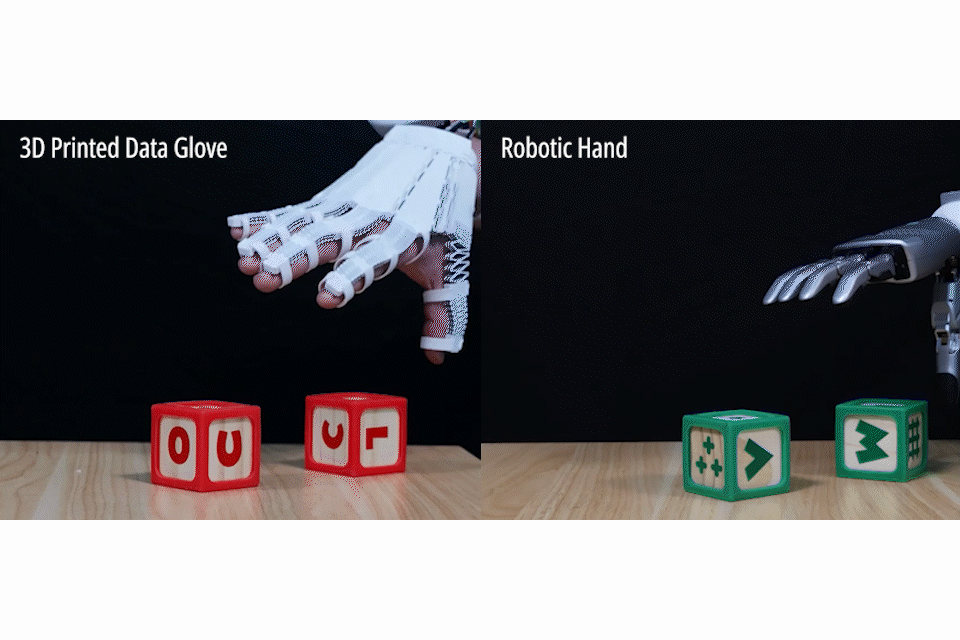
“X-Hinges” helps design and 3D print items like lamps and gloves with an interactive twist: automatically embedded sensors that perceive and adaptively respond to human contact.
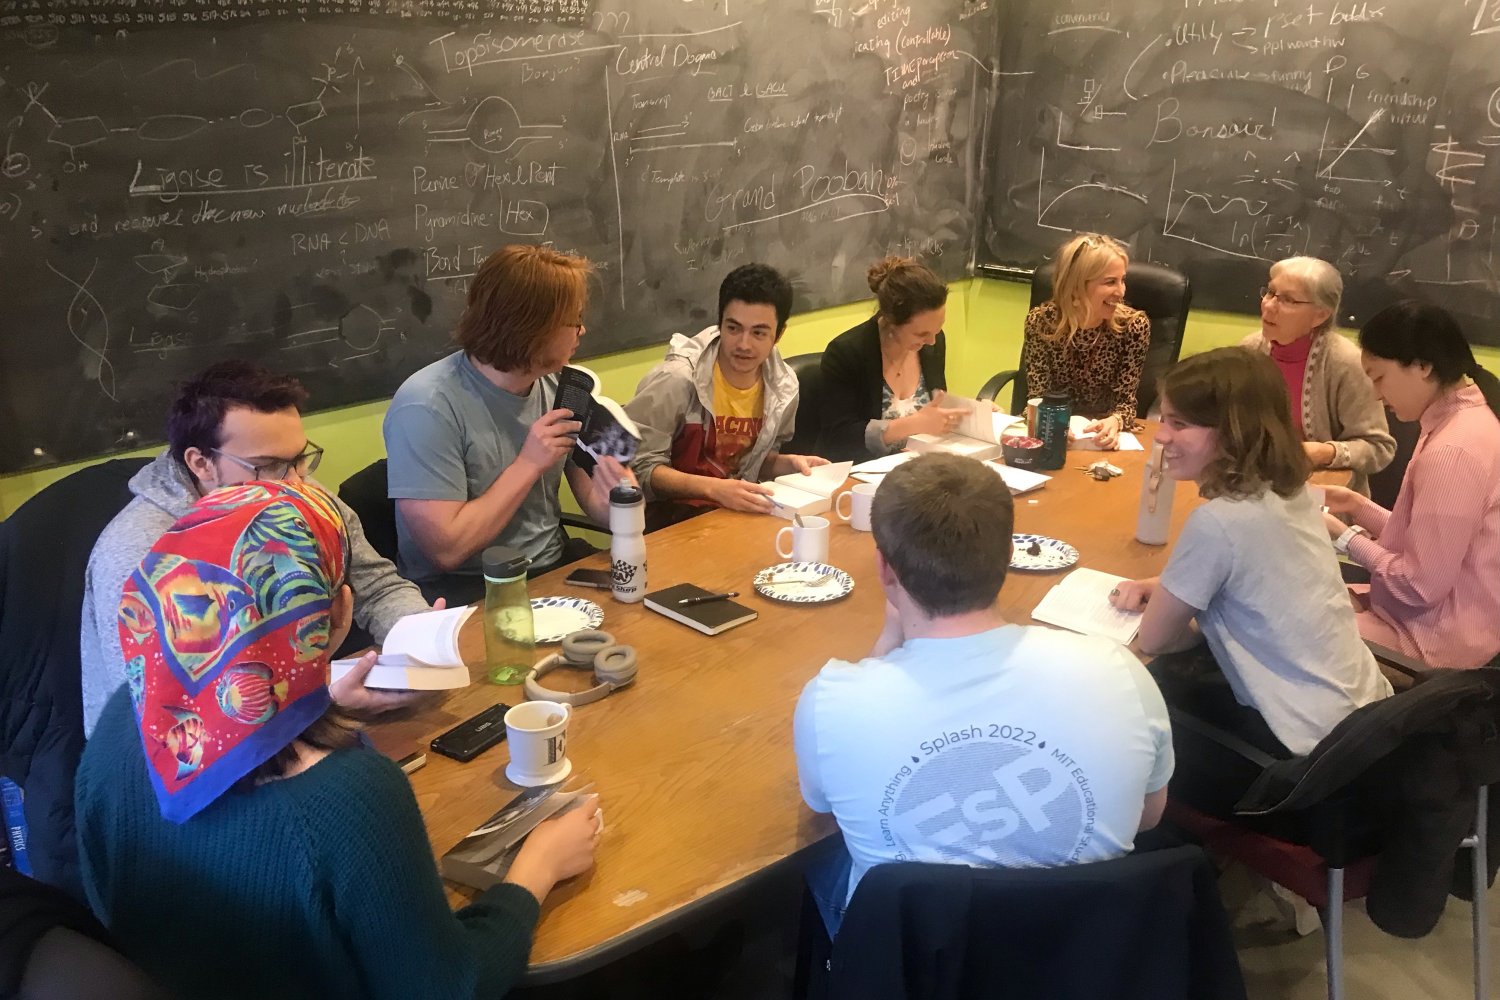
Students in MIT’s Concourse program delve deeply into the human condition, debate challenging questions, and learn to develop judgment about issues that can’t be quantified.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.