Oct 2026· Proceedings of the ACM on Software Engineering· Vol 3, pp. 1626 - 1648· 0 citations· 66 references
Software Testing and Debugging Techniques
TL;DR
This paper formalizes test suite generation as a Markov Decision Process (MDP) and demonstrates that its objective exhibits monotone submodularity, which enables an effective relaxation of this NP-hard global optimization into a tractable step-wise greedy procedure.
Abstract
With the rapid evolution of Large Language Models (LLMs), automated software testing is witnessing a paradigm shift. While proprietary models like GPT-4o demonstrate impressive capabilities, their high deployment costs and data privacy concerns make open-source LLMs the practical imperative for many academic and industrial scenarios. In the field of automated test generation, it has evolved to iterative workflows to construct test suites based on LLMs. When utilizing open-source LLMs, we empirically observe they lack a suite-level perspective, suffering from structural myopia—failing to generate new tests with large marginal gain based on the current covered status. In this paper, from the perspective of sequences, we formalize test suite generation as a Markov Decision Process (MDP) and demonstrate that its objective exhibits monotone submodularity, which enables an effective relaxation of this NP-hard global optimization into a tractable step-wise greedy procedure. Guided by this insight, we propose TestDecision, which transforms LLMs into neural greedy experts. TestDecision consists of two synergistic components: (1) an inference framework which implements test suite construction following a step-wise greedy strategy; and (2) a training pipeline of reinforcement learning which equips the base LLM with sequential test generation ability to maximize marginal gain. Comprehensive evaluations on the ULT benchmark demonstrate that TestDecision significantly outperforms existing advanced methods. It brings an improvement between 38.15-52.37% in branch coverage and 298.22-558.88% in execution pass rate over all base models, achieving a comparable performance on 7B backbone with a much larger proprietary LLM GPT-5.2. Furthermore, TestDecision can find 58.43-95.45% more bugs than vanilla base LLMs and exhibit superior generalization on LiveCodeBench, proving its capability to construct high-quality test suites.
This work extends Compute-Aligned Training to this setting through an abstraction of policy-guided search, deriving tractable, trace-supported losses and introduces a search-agnostic uniform-allocation (UA) loss that accounts for the budget without specifying the specific search.
This paper presents a search-based testing framework for LLM-based applications that incorporates failure diversity as an explicit optimization objective and maintains an archive of generated tests and rewards distance from that archive, while a repopulation operator periodically replaces non-failing tests in the popul...
Lev Sorokin, Ivan Vasilev, Ken E. Friedl et al.· 0 citations
This paper introduces AESAT (Auto-Evolving SAT solving), a novel neuro-symbolic framework designed to automatically evolve and optimize the heuristic functions of SAT solvers, and represents the first time an LLM-enhanced solver has dominated the world's premier SAT competition.
Mao Luo, Hang Ding, Chumin Li et al.· Proceedings of the Thirty-Fi...· 0 citations
Open-ended scientific discovery often requires repeatedly proposing and evaluating candidate solutions. LLM-based systems can support this process by generating and refining executable solutions from verifier feedback. Methods such as TTT-Discover use test-time training (TTT) to update the solution-generating LLM from...
Chong-He Jiang, Ao Qu, Si-Yuan Liu et al.· 0 citations
CovR is presented, an agentic framework for automated testbench generation that combines self-reflection loops with simulation-based feedback to maximize coverage and a reinforcement learning (RL) framework tailored for coverage-driven testbench generation, leveraging tool-derived rewards from simulation and coverage f...
SAILOR, a proof-of-concept system that detects such unsupported numerical choices, asks the user targeted follow-up questions, and updates the optimization model before returning a solution, is presented.
Shaghayegh Sadeghi, Steve Smith, D. C. Del Rey Fernández· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
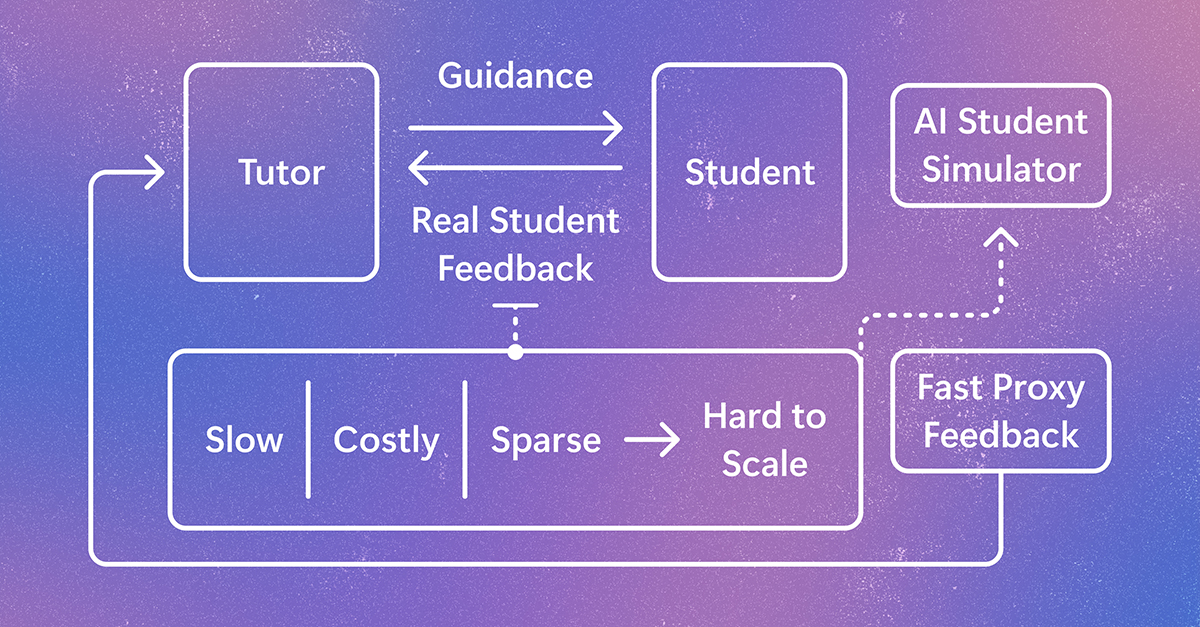
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduNov 17, 2026
By studying the computational foundations of language learning, Associate Professor Jacob Andreas builds intelligent systems that can communicate effectively with humans.
MIT News · Artificial Intelligence· news.mit.eduNov 17, 2026
AI coding agents are increasingly help developers fix bugs and build features largely on their own, but every interaction with their models consumes tokens. In each session, an agent sends instructions, tool descriptions, and session history to its model. Most efforts to reduce this cost focus on individual tasks. Yet developers return to the same […] The post TokenEconomizer: Learning from Experience to Make AI Coding Agents More Efficient appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.


