On-policy distillation (OPD) improves the reasoning capabilities of small language models through token-level teacher supervision on student-generated trajectories. Yet can teachers that excel at solving problems independently also guide student reasoning effectively? Prior work shows that when student prefixes follow reasoning paths that differ from the teacher's own or contain errors, teachers can be less accurate when continuing from these prefixes than when solving problems independently. To this end, we propose Prep-OPD, which uses reinforcement learning (RL) before distillation to train the teacher to adapt to the student's existing reasoning state and correct course when errors arise. Training optimizes teacher continuations from fixed student prefixes using final-answer correctness as the reward. The prepared teacher then trains the student through trajectory guidance and token-level supervision. We evaluate Prep-OPD on eight mathematical reasoning benchmarks, using Qwen3-4B-Instruct-2507 as the teacher and Qwen3-0.6B and Qwen3-1.7B as students. With the 4B teacher and 1.7B student, Prep-OPD improves average accuracy over standard OPD and the strongest baseline, Relay-OPD, by 8.28 and 2.30 percentage points, respectively. Controlled experiments further show that teacher RL conditioned on student-generated prefixes yields higher student accuracy than problem-start teacher RL with and without handoff on Qwen3-1.7B. Reusing the same prepared teacher also improves Qwen3-0.6B.

This paper investigates developing real-world perception for active agents, proposes Gibson Environment for this purpose, and showcases a set of perceptual tasks learned therein.
F. Xia, Amir Zamir, Zhi-Yang He et al.· 2018 IEEE/CVF Conference on...· 1,069 citations· ⚡112
Supporting data, adapters, predictions and code for the article *Low-Cost LoRA Fine-Tuning of Small Language Models for Multi-Step Arithmetic Reasoning* by Jake O'Grady, Asena Isik Gürhan, Chee Fong Ting and Effirul Ramlan (University of Galway). We generated 20,000 GSM8K-derived arithmetic problems with step-by-step s...
O'Grady, Jake, Gürhan, Asena Isik, Chee, Fong Ting et al.· Zenodo (CERN European Organi...· 465 citations
The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.
Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al.· Information and Software Tec...· 394 citations· ⚡54
The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.
Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al.· Neural Information Processin...· 316 citations· ⚡15
It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...
Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al.· Neural Information Processin...· 302 citations· ⚡60
An algorithm is proposed which leverages disentangled semantic factors to generate adversarial perturbation by altering controlled semantic attributes to fool the learner towards various "adversarial" targets.
Haonan Qiu, Chaowei Xiao, Lei Yang et al.· arXiv.org· 208 citations· ⚡17
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
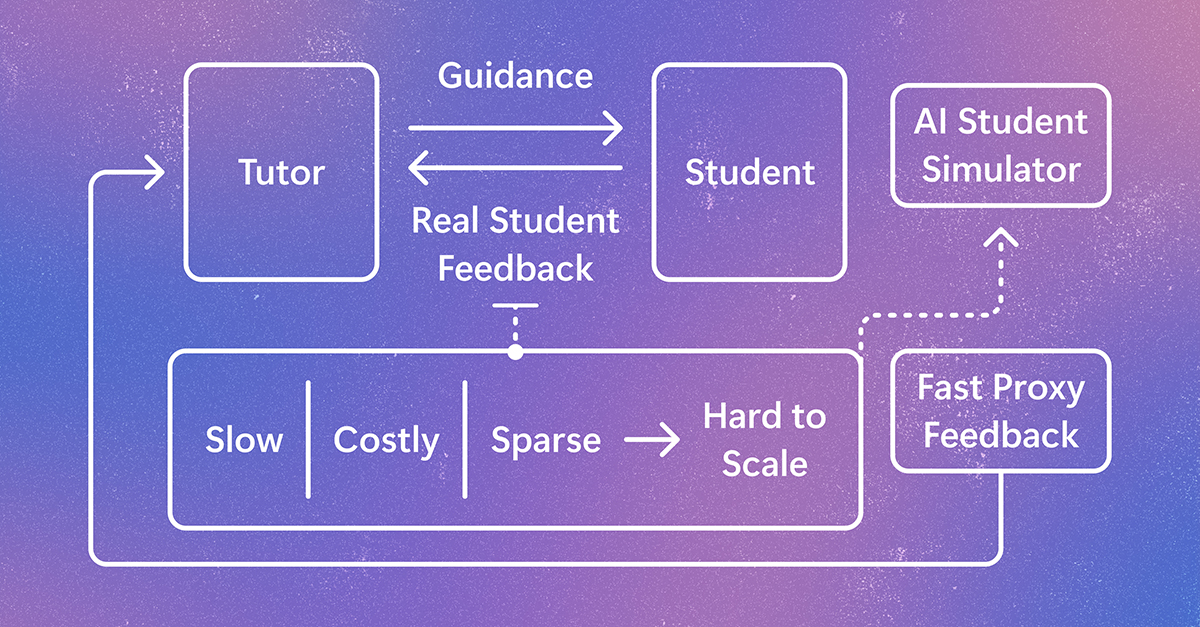
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.