Skip to content

HEIRS-PS: Hybrid 3-D RRAM- and SRAM-CIM for Pipelined Sparse Multitask Transformer Acceleration

Nov 2026 · IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems · Vol 45, pp. 6215-6228 · 0 citations · 45 references

Abstract

Multitask transformers have garnered widespread attention for fast task adaptation at edge. However, in addition to matrix–vector multiplication (MVM) with static and dynamic weights in the data-intensive transformer, task adaptation introduces new challenge of weight updating. Besides, while sparsity can help mitigate the rapid growth in parameter size and computational demand, it requires great hardware flexibility. Compute-in-memory (CIM) is widely explored to overcome the memory bottleneck in neural network acceleration, mainly with single type of memory devices, but struggles to balance the storage density with computing flexibility across multiple tasks. Meanwhile, the conventional pipeline parallel dataflow for high throughput suffers from the underutilization with bubbles caused by variable input sequence length and model sparsity. In this article, HEIRS-PS, a hybrid three-dimension RRAM- and SRAM-CIM architecture, is proposed for the pipelined multitask transformer acceleration with sparsity. With the 3-D integrated RRAM-CIM and SRAM-CIM arrays, a novel hybrid-CIM paradigm is proposed with the collaborative addition to achieve both high storage density and computing flexibility for multitask inference. Moreover, by fully leveraging the hybrid-CIM structure in HEIRS-PS, a new dynamic workload scheduling method is proposed with a layer regrouping method to balance the computing latency across pipeline stages. By eliminating the bubbles, the model inference latency is reduced with higher throughput. Experiment shows that the proposed HEIRS-PS architecture improves the energy efficiency by up to $13.3\times $ and $8.68\times $ , compared with state-of-the-art (SOTA) RRAM-CIM and SRAM-CIM works on Llama-1.3B. Moreover, HEIRS-PS also reduces the computing latency by up to 29.5% with the balanced latency across pipeline stages.

View source

Similar papers

Conference Open access Sep 2026

Hybrid RRAM-SRAM Computing-in-Memory Architecture Enabling Inference and Fine-Tuning

The hybrid RRAM-SRAM CIM architecture that enables inference and finetuning is proposed and achieves the higher peak energy efficiency of 20.76 TOPS/W, outperforming the state-of-the-art by 2.30×.

Yuxuan Huang, Jia-Wei Su, Han Jin et al. · 0 citations
Conference Open access Sep 2026

A Hybrid Analog–Digital Dynamic Compute-in-Memory Architecture with Workload-Aware Dynamic Mode Selection for Edge AI

A Hybrid Analog-Digital Dynamic Compute-in-Memory (HAD-DCIM) architecture that integrates analogue accumulation with effective digital refinement using a workload-aware dynamic mode-selection mechanism and is suggested that HAD-DCIM is a very effective, accurate, and flexible solution for edge-AI applications that don'...

Keerthi Kassan V, S. Kumaresan · 0 citations
Preprint Oct 2026

SPARTA: A Sparse Ternary LLM Accelerator with Adaptive Attention and Unified Datapath for Long-Context Edge Inference

LLMs on edge devices are constrained by limited memory and bandwidth. Although 1.58-bit ternary weights greatly reduce model storage, long-context inference is increasingly bottlenecked by KV-cache traffic and attention. Existing accelerators also use separate datapaths for ternary linear layers and attention, incurrin...

Yan-Zhen Zhou, Zheng-Yu Han, Qun-You Liu et al. · 0 citations
Open access Sep 2026

DCSR-GCN: A High-Performance GCN Accelerator Based on Dynamic Compression and Sparsity Reordering

DCSR-GCN, a high-performance GCN accelerator based on dynamic compression and sparsity reordering based on dynamic compression and sparsity reordering, is presented and a two-phase reordering algorithm that combines conflict-aware row scheduling with reuse-aware column grouping is proposed, thereby mitigating RAW confl...

Jun-Sheng Chang, Yi-Min Zhao, Yu-Xin Huang et al. · 0 citations

Related blog posts

Microsoft Research Blog Oct 29, 2026

Microsoft Research Focus – Edition #97

Host Sowbhagya Suresh shares some of the latest news and cutting-edge research from across Microsoft—from understanding the challenges facing coding agents to uncovering how people use AI at work and improving extended-range weather forecasting. The post Microsoft Research Focus – Edition #97 appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 28, 2026

Making machines that can listen

Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.

Microsoft Research Blog Oct 21, 2026

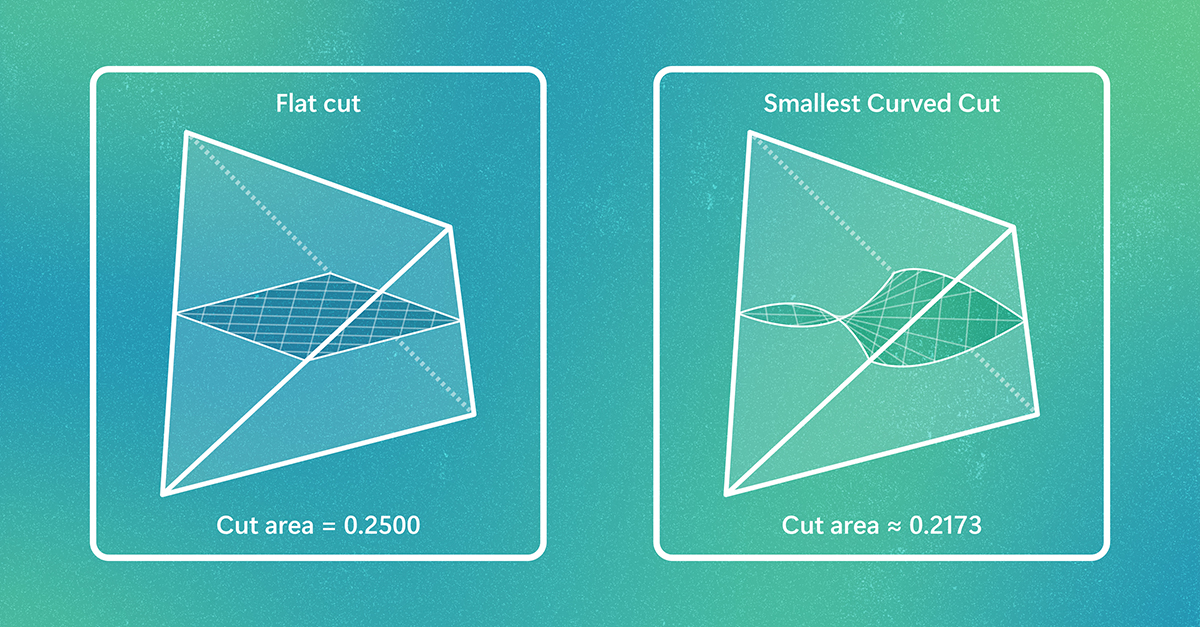
Solving a 31-year-old grand challenge in mathematics – the KLS conjecture

For decades, a fundamental question about the difficulty of computing in high-dimensional spaces has resisted proof. New research resolves this question, removing a major theoretical obstacle to understanding the efficiency of randomized algorithms used across science and computing. The Kannan–Lovász–Simonovits (KLS) conjecture was proposed in 1995. It asks whether, for a broad class of high-dimensional […] The post Solving a 31-year-old grand challenge in mathematics – the KLS conjecture appear…

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.