This work investigates whether LLMs can learn molecular design strategies from cheaper synthetic tasks that generalize to expensive molecular lead optimization settings and suggests that scaling post-training using synthetic tasks is an effective strategy for adapting LLMs to high-cost experimental scenarios that are too expensive to directly train on.

Abstract
Designing viable drug candidates requires searching a combinatorially large and rugged chemical space for molecules that satisfy multiple, often competing, objectives. Large language models (LLMs) provide a useful generative prior for this problem because of their representational capacity, reasoning ability, and flexibility when incorporating information from the external environment. While reinforcement learning from verifiable rewards (RLVR) can be used to improve the capabilities of LLMs, many chemically relevant scoring functions require hours or even days per evaluation, making them prohibitively expensive to use directly during online training. Here, we investigate whether LLMs can learn molecular design strategies from cheaper synthetic tasks that generalize to expensive molecular lead optimization settings. We find that curriculum-based training recipes that gradually incorporate more challenging synthetic design tasks enable strong performance that surpasses that of much larger frontier models on structure-based lead optimization. Our results suggest that scaling post-training using synthetic tasks is an effective strategy for adapting LLMs to high-cost experimental scenarios that are too expensive to directly train on.

PepOpt is an interpretable machine learning framework that unifies molecule-based and sequence-based peptide representations in linear models and exploits dynamic programming to efficiently explore ultralarge peptide spaces, accelerating the rational design of novel peptide therapeutics.
Yi-Xiang Mao, Rui-Bo Zhang, Robert P. Sheridan et al.· npj Drug Discovery· 0 citations
This work introduces Top-K prompting as a robust training and inference paradigm to better capture diverse, plausible reaction predictions and establishes Top-K, plausibility-aware training as a practical new direction for robust future LLM-based synthesis planning.
B. Zagribelnyy, Ivan D. Ilin, N. Bondarev et al.· 1 citation
This work forms the specialization of pretrained virtual screening models to individual pockets as a test-time adaptation problem and proposes PETA, a parameter-efficient framework that directly adapts pretrained model at test time and outperforms both pretrained and fully retrained baselines while updating only the La...
Jia-Qi Lin, Ying-Hua Yao, Chang-Ran Wang et al.· 0 citations
Testing the ability of common large language models to consider design principles to generate de novo proteins that bind metals and lipophilic small molecules without copying existing sequences highlights the utility of LLMs in making protein design more comprehensible and accessible to users without sophisticated desi...
Nam Hyeong Kim, A. K. Hatstat, Hyunil Jo et al.· bioRxiv· 1 citation
BOReFT is introduced, which learns a compact, low-dimensional space of hidden-state interventions in a frozen language model, and uses this space as the search domain for Bayesian optimization with an external scoring function, and provides a principled new bridge between discrete proposal spaces of LLM-based search an...
Dhruv Agarwal, Rico Angell, Kavitha Srinivas et al.· 0 citations
Real-SWIT, a generative ULVS framework that learns Enamine REAL Space as a synthesizable molecular distribution and couples this generator with a target-specific scoring model to enable docking-guided exploration of REAL Space at the level of complete molecule, establishes generative access to make-on-demand chemical s...
Kai-Yue Zhang, Ying Sun, Xin-Yue Li et al.· bioRxiv· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
Assistant Professor Benjamin Lindquist studies how engineers deliberately injected randomness into early AI, giving rise to deep-learning models that sometimes hallucinate.
Learn how Google DeepMind and GovTech Singapore uses lightweight on-device Gemma models to intercept conversational scams in private chats with zero cloud data egress.
Microsoft Research Blog· microsoft.comOct 12, 2026
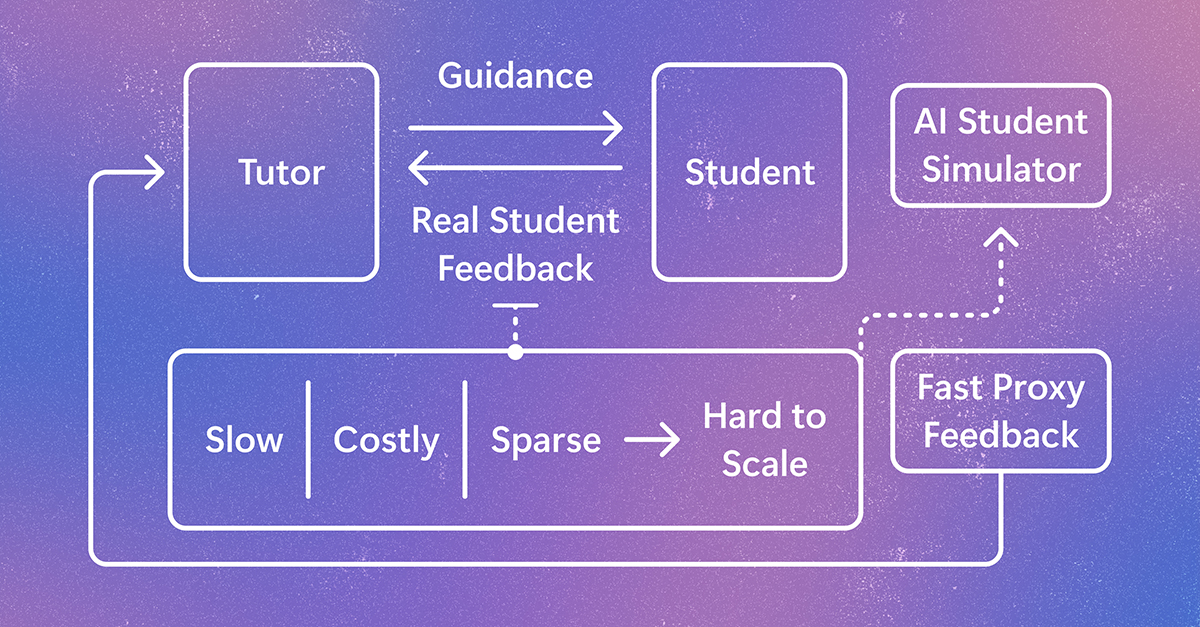
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.