Skip to content
#software testing Open access

Hardware-Assisted Spatial Memory Safety for Shared GPU Accelerators: A Pointer Tagging Co-Design with Analytical and Synthesis-Level Evaluation

Sep 2026 · Computers · 0 citations

TL;DR

This work presents a hardware–software co-design whose 16-bit tag uses odd parity and fail-safe class encoding, which combines a variable-precision extent, an aligned CRC checker, and an exact-bounds micro-cache.

Abstract

Graphics processing units (GPUs) underpin high-performance computing, but device partitioning does not ensure that an in-context pointer remains within its allocation. We present a hardware–software co-design whose 16-bit tag uses odd parity and fail-safe class encoding. It combines a variable-precision extent, an aligned CRC checker, and an exact-bounds micro-cache. For 200,000 log-uniform requests from 16 B to 1 TiB, mean Class 4 fragmentation is 1.638%, versus 27.733% for power-of-two encoding. The seven-bit aligned signature has full GF(2) rank and a 1/128 non-adaptive collision rate; its deterministic window is exactly one through three regions and tight at four. Exhaustive testing rejects every one-bit tag corruption, while two-bit analysis demonstrates why parity is not adversarial authentication. A SAT-equivalent endpoint rewrite reduces Class 3 generic depth from 60 to 24 levels. A fail-closed 32-lane Class 4 topology detects nonuniform active-lane tags in hardware; for uniform tags, it reduces generic CMOS cost from 155,200 to 72,872 transistor equivalents (53.05%) and depth from 67 to 61 levels. Official SASS traces provide an analytical exposure bound rather than native simulation; a separate pre-layout 45 nm mapping is reported only as a timing sensitivity experiment.


Read PDF

Similar papers

Aug 2026

Branch-Free Binary128 Multiplication: SRMA Implementation with SSE2 Instructions and Kintex-7 Validation

This research presents an optimized, reduced-clock-cycle approach for performing 128-bit floating-point calculations on Field-Programmable Gate Arrays (FPGAs) using the SRMA architecture, which not only reduces execution time but also decreases energy consumption on Kintex-7 FPGA boards.

N. P, Thirumalaiswamy V., H. S. et al. · 0 citations
Open access Sep 2026

FlexXNOR-OD: A Channel-Grouped XNOR-Based Variable-Precision Accelerator for Real-Time Edge Object Detection

FlexXNOR-OD is proposed, a new FPGA-oriented accelerator for real-time object detection that combines channel-group precision assignment with a lane-fusible XNOR processing element that offers a practical path toward precision-scalable, multiplier-light object detection on resource-constrained edge platforms.

Budidha Sriman and D. Sateesh · 0 citations
Preprint Aug 2026

What Actually Serializes GPU LZ77 Decode: Three Decoders, Three Mechanisms, and an Encode-Time Lever That Removes the Last One

Across three decoder architectures on an H100 the authors measure that parse, not copy, holds 64-72% of device-resident decode time; that bounding back-reference chain depth - provable, and costing 0.006% in ratio - moves latency by at most 2.8% and, for the file's own latency spike, provably by nothing at all.

Yakiv Shavidze · 0 citations
Preprint Sep 2026

Automated Instruction Encoding Synthesis for Modern GPU ISA Compression

Modern GPU kernels increasingly stress the instruction supply path, while fixed instruction containers can leave substantial footprint slack. This paper presents an automated encoding-synthesis framework that treats instruction layout as a constrained slot-assignment problem over a validated instruction-form field spec...

Ming-Yuan Ma, Hu He · 0 citations
Preprint Sep 2026

BenX: Resource-Sharing Permutations for Computational Integrity

Cryptographic hash functions over integers modulo a prime play a decisive role in the efficiency and security of proof systems for computational integrity. Early designs focused on compact arithmetic circuits and efficient software execution, primarily targeting general-purpose CPUs rather than hardware accelerators. T...

Luca Campa, Thomas De Cnudde, A. Kindi et al. · 0 citations

Related blog posts

Microsoft Research Blog Oct 12, 2026

Simulating student learning for better AI tutoring

StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.

MIT News · Artificial Intelligence Oct 2, 2026

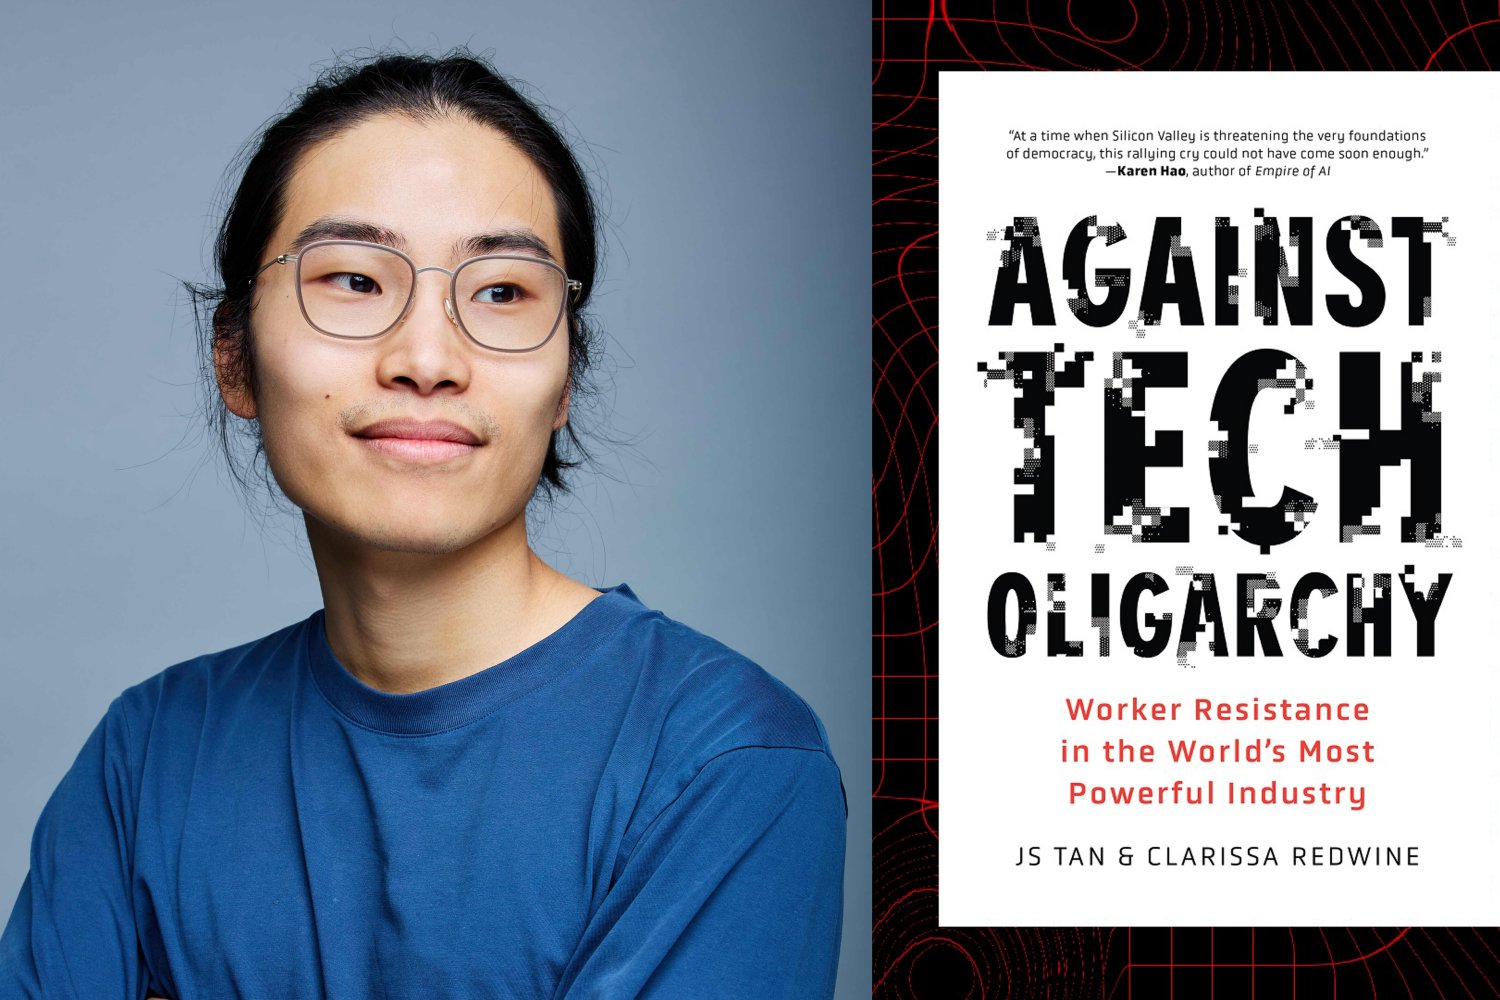
Documenting the tech worker movement

Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.