Skip to content

From Intent to Execution Grant: An Execution-Boundary Conformance Profile for High-Risk AI Actions

Sep 2026 · 1 citation · 25 references
Computer Science

TL;DR

EBL-Core, an execution-boundary conformance profile for deciding whether one canonical, fully materialized AI-generated candidate may receive action-scoped execution authority under explicit conditions, is specified.

Abstract

AI agents increasingly propose actions with external consequences, including financial transfers, infrastructure changes, software deployments, disclosures, and physical actuation. Authorization engines, policy languages, runtime monitors, provenance mechanisms, and agent guardrails provide important foundations, but do not necessarily define a common semantic contract for the final transition from a particular candidate action to execution authority. We specify EBL-Core, an execution-boundary conformance profile for deciding whether one canonical, fully materialized AI-generated candidate may receive action-scoped execution authority under explicit conditions. It binds a structured intent object, Root and Operational Policies, evidence obligations, typed evidence, context, time, and a verifiable Decision Derivation through an Execution Release Contract (ERC). An ERC is not an authority-bearing token; a verified ALLOW ERC may support a separate Execution Grant governed by Redemption-time validation. EBL-Core specifies action binding, policy non-weakening, evidence handling, deterministic adjudication, derivation verification, and grant lifecycle behavior. An accompanying reference artifact provides schemas, adjudication, separate verification and Semantic Replay, and a linearizable in-memory grant store. In the retained run, 34 static vectors and 15 lifecycle checks matched expected outcomes. Across 100 trials, 32 concurrent Redemption attempts yielded exactly one successful Redemption and protected test effect per trial; 100 Revoke-Redeem races ended in valid terminal outcomes. These bounded results demonstrate executability of the specified subset, not human-intent correctness, evidence truth, complete mediation, production readiness, mechanized correctness, or deployment-level security.
View source

Similar papers

Open access 2026

Deterministic Runtime Enforcement: The Execution Authority for Autonomous AI Agents

This paper introduces L-DREA, a deterministic runtime-enforcement architecture that generalizes Anderson’s 1972 reference-monitor primitive from mediation of data access to mediation of externally effective action, and six runtime invariants are established analytically.

Abhinandan Gill-Lakhowal · 0 citations
Preprint Sep 2026

ADF-EA: A Unified Execution Assurance System for Agent Device Foundation

Agents based on large language models (LLMs) can access heterogeneous devices through tools and APIs, but reliable execution must account for unmet effects, uncertain outcomes, and changing prerequisites. A command may be acknowledged without producing its intended effect, while missing feedback may obscure an action t...

Xue-Chun Li, Jia-Xin Liang, Jie Li et al. · 0 citations
Open access Sep 2026

RACER: Remediation Assurance Contracts for Evidence-Gated, Risk-Bounded Autonomous Recovery in Cloud Systems

AI agents can diagnose cloud incidents, synthesize operational commands, and invoke state-changing APIs, but a plausible remediation is not necessarily safe to execute. This study presents RACER, a runtime-assurance mechanism that treats every AI-generated repair as an untrusted proposal until it is bound to a machine-...

Prudvi Saisaran Ponduru, Pavani Priya Vyshnavi Nandanavanam, Sai Kesav Kumar Ponduru · 0 citations
#artificial intelligence Preprint Sep 2026

ActGov: Governing LLM Agent Actions via Policy-Constrained Validation

Large language model (LLM) agents increasingly execute long-horizon workflows through external tools, allowing untrusted outputs to influence subsequent actions and exceed user authorization. Existing defenses isolate injected content or constrain execution with predefined plans and static policies, but these approache...

Kai-Yuan Zhang, Yu-Ke Peng, Ke Jiang et al. · 1 citation · ⚡1
Open access Sep 2026

Runtime Policy Firewall: A Zero-Trust Governance Layer for Enterprise Agentic AI

Enterprise adoption of generative AI is shifting from passive question answering to autonomous agentic execution. Modern agents can decompose goals, retrieve business context, call tools, update records, send messages, initiate transactions, and coordinate workflows across multiple systems. This creates productivity op...

Swapneswar Ray · 0 citations

Related blog posts

MIT News · Artificial Intelligence Oct 2, 2026

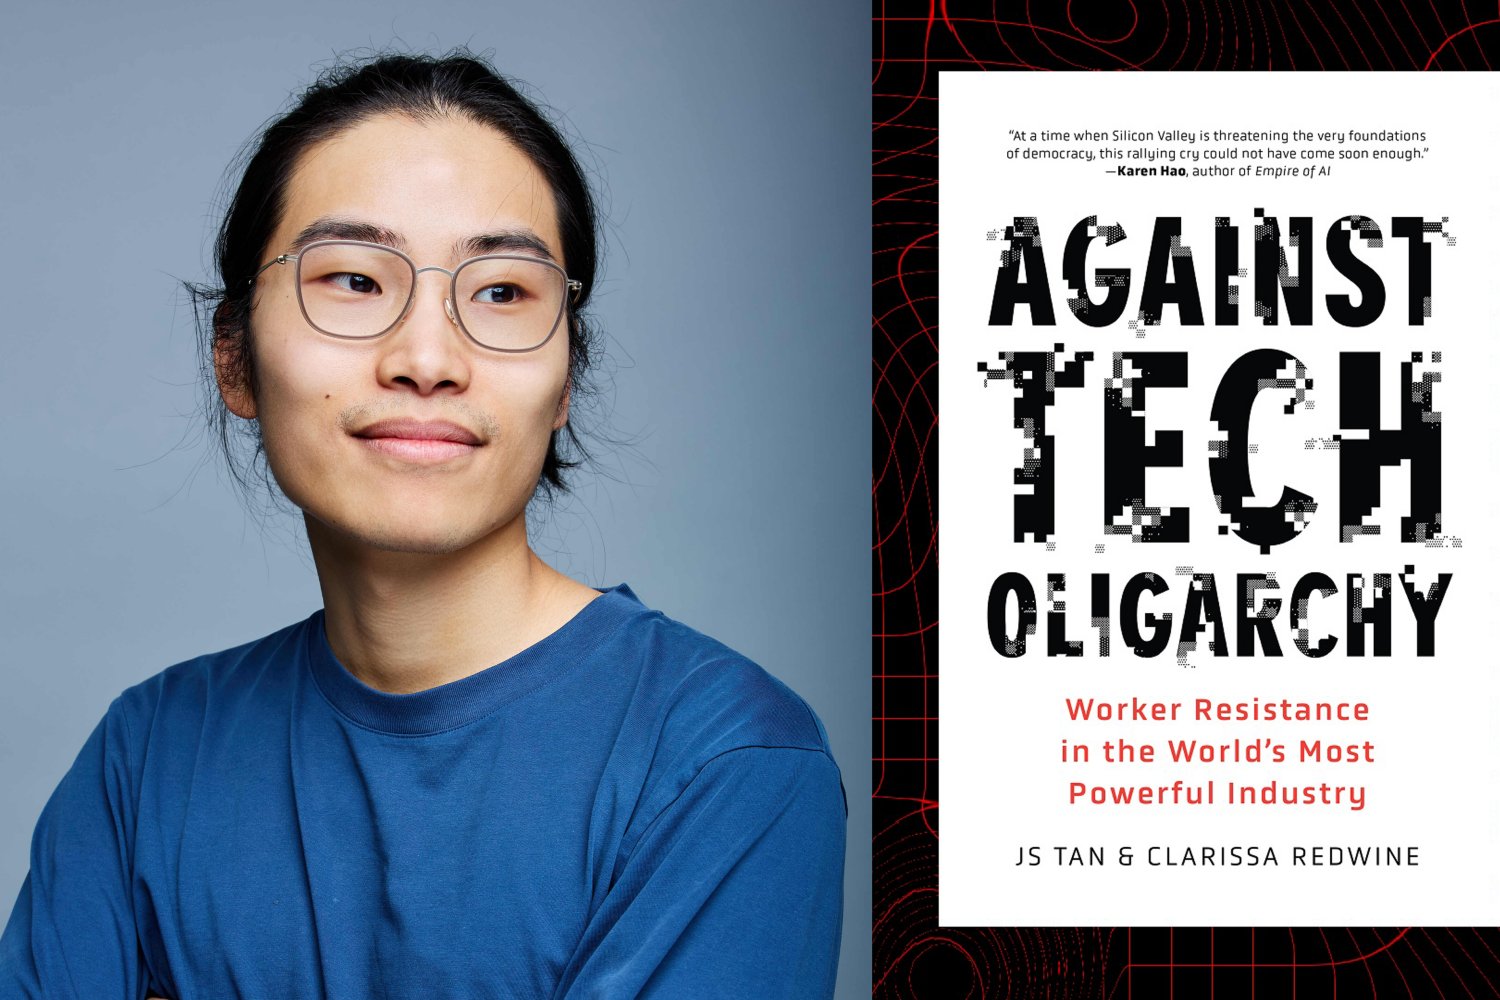
Documenting the tech worker movement

Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.

GPT-Lab Sep 23, 2026

Requirements Don’t Live in Isolation: What We’re Exploring with Req-Space

Requirements in large systems rarely exist in isolation. Their meaning depends on the wider project context - other requirements, policies, decisions, tests, and implementation details. That becomes especially important when AI is used for review, because spotting a possible conflict or gap is only the beginning. ReqSpace explores how AI, visualisation, and connected project context can help reviewers understand those findings, trace the relationships behind them, and focus on the questions that…

GPT-Lab Sep 17, 2026

Beyond Prompt Engineering: The Role of Tacit Knowledge in Software Engineering

AI is making software generation faster, but speed does not remove the need for expertise. As more work is delegated to AI, tacit knowledge may become one of the most important human advantages in software engineering. The post Beyond Prompt Engineering: The Role of Tacit Knowledge in Software Engineering appeared first on GPT-Lab.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.