Fixed-state recurrent language models such as Gated DeltaNet and Mamba promise constant memory at any context length, yet in practice they recall a fact a few thousand tokens later and then lose it. We remove both ways a delta-rule memory forgets, decay and erasure by later writes, on archival heads whose decay is pinn...
Youssef Khouidi· Zenodo (CERN European Organi...· 0 citations
Review title: Hypertension and constipation with anti-CGRP monoclonal antibodies: a systematic review and meta-analysis Type and method of review: Meta analysis Stage of review at time of this submission: Review ongoing — the protocol has been finalised and the peer-reviewed search prepared; formal screening not yet st...
Yara El Deghel, Riwa Jibrayil Razzouk· Open Science Framework· 0 citations
Before an assistant acts on a message, it decides whether the message is something it handles (scope) and what it asks for (intent). We ask which kind of system should make that decision given the same in-scope labelled data, and what moves a prompted model's scope decision. We compare a fine-tuned 150M classifier with...
Safwan Kamal· Zenodo (CERN European Organi...· 0 citations
With the rapid development of cloud-edge industrial Internet of Things, massive sensor and device data are continuously generated at distributed edge clients, while cloud-hosted large language models provide new opportunities for collaborative intelligence and high-level decision support. However, directly uploading in...
Hong Pan, Pengfei Wang, Yu Wang (12152) et al.· Journal of Cloud Computing A...· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Background: Smoke inhalation injury is the main fire-related respiratory injury in burn patients and is included in most burn mortality scores, but whether it predicts death independently of burn size and age has been disputed. Objective: To estimate the multivariable-adjusted association between inhalation injury and...
Large language model chatbots have been proposed as AI-interviewers for collecting qualitative interview data at scale, potentially bridging social science's longstanding divide between the breadth of surveys and the depth of qualitative interviews. This paper provides the first direct empirical comparison of data qual...
S. Güven, T. Gårdhus, Andreas Bjerre-Nielsen et al.· 0 citations
Post-training is widely assumed to reduce the social biases language models inherit from pretraining, yet direct evidence for this assumption remains mixed. In this paper, we examine how gender disparities evolve across the language modeling pipeline. In particular, we study occupational gender bias in OLMo 3, a fully...
Manthan Gadhia, A. Hoyle, Karolina Stanczak· 0 citations
Small-to-large language model routing can reduce inference cost by escalating difficult inputs while retaining easier ones on a smaller model. Its success, however, depends on identifying examples that benefit from escalation, and the reliability of confidence across multilingual tasks remains unclear. We present a sys...
Long-context decoding in large language models (LLMs) is increasingly bottlenecked by the memory and computation required to attend over an ever-growing Key-Value (KV) cache at each autoregressive step. Although token-level sparse attention reduces this burden by restricting computation to a small subset of relevant pa...
Zhen-Xu Tian, Ke-Bin Liu, Zheng-Wu Yang et al.· 0 citations
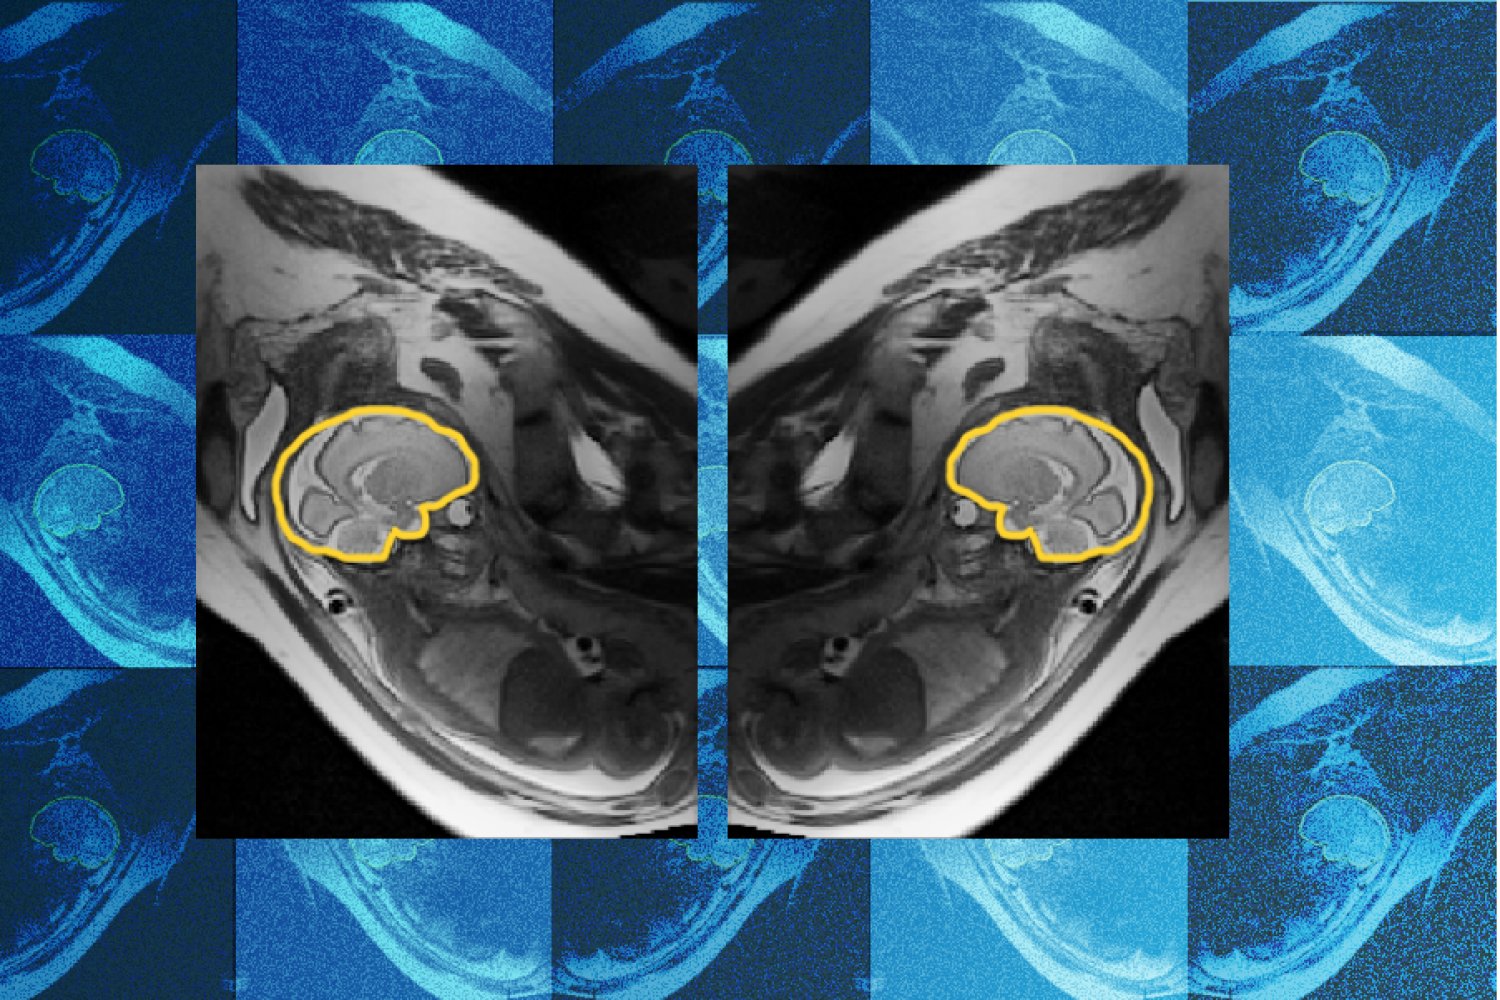
A model developed by researchers at MIT and Boston Children's Hospital adjusts scans on the fly to track fetal movement, potentially sparing families repeat hospital visits.