Large language model (LLM) agents are increasingly evaluated on long-horizon tasks, including autonomously running a business. Existing benchmarks for this setting are almost exclusively English-language, Western in retail context, and single-agent, with the agent observing the business directly. We study how these res...
Bhuvan Arora, Ankita U. Karmakar, Chaitanya Jain et al.· 0 citations
Recent studies have shown that position bias remains a critical vulnerability in large language models (LLMs), undermining both the integrity of multiple-choice evaluations and the reliability of retrieval-augmented generation. However, existing understanding of this phenomenon is largely derived from studies with limi...
Yi-Ning Li, Huayang Li, Le-Mao Liu et al.· 0 citations
Spatial context prediction requires visual grounding and spatial reasoning to identify vacant regions relative to objects in a scene. Spatial relationships and physical constraints remain challenging for large vision-language models (VLMs). Recursive reasoning has demonstrated strong performance on discrete and abstrac...
Wajeeha Tahir, Anna Tegon, Lionnus Kesting et al.· 0 citations
Robustness studies of vision-language models (VLMs) grade degradation on nominal severity scales ("level 1-5") that carry no physical units, and they rarely ask whether a model's confidence follows the loss of visibility. We measure accuracy, internal (token-probability) confidence, verbalized confidence and an explici...
Mochamad Rizal Fauzan, Irgi Surya· 0 citations
Reach audiences
Advertise in front of researchers, engineers, and readers.
Small variations in prompt characteristics can meaningfully alter the semantics, tone, and contextual assumptions of large language model outputs. Such characteristics can involve group variables such as demographics or other sensitive latent attributes. Sensitivity to such input variables is undesirable when demograph...
B. Demir, Emma Shen, Ksheeraj Sai Vepuri et al.· 0 citations
Federated Learning (FL) is a powerful machine learning framework that allows building a global model from the contributions of multiple, distributed clients, while ensuring the privacy of their local data. However, its heavy computational and communication overheads challenge its use for contemporary AI workloads such...
Ali Sarabadani, Massimo Piccardi, M. Abolhasan et al.· 0 citations
LLM-agent memory selection often uses retrieval rankings based on record relevance or individual influence. Such rankings cannot identify sufficient subsets under redundant or jointly necessary evidence. We study per-decision memory sufficiency: selecting a small subset that preserves full-memory behavior. To separate...
A common way to make language models and agents more accurate is to spend more compute at inference time: generate many candidate solutions and submit the one a verifier prefers. Success then requires that some candidate is correct and that the verifier picks it. The first grows predictably with the number of samples;...
Local learning algorithms can reshape resource requirements of artificial intelligence. The memory bottleneck of standard end-to-end backpropagation lies in the need to store all network activations until the loss gradient has been propagated back through. Local learning avoids this, but typically at a cost in accuracy...
Wu-Zi S. Han, Brian A. Yuan, G. Bellec· 0 citations
Looped language models reuse physical Transformer blocks across logical depth, but established architectures entangle recurrence placement, input injection, and recurrent state organization. We isolate these axes in models trained from scratch at matched parameter scale, logical depth, and token budgets, and then test...
Benhao Huang, Chu-Fan Shi, Jun-Lin Chen et al.· 4 citations
Introduction: Near-perfect crop-label accuracy can conceal uncertainty, perturbation sensitivity, and weak explanations. This study evaluates these reliability dimensions without treating benchmark classification as an agronomic recommendation. Materials and methods: Ten classifiers were evaluated using five matched st...
Kwan Hong TAN· Academia AI and Applications· 0 citations
A conceptual framework linking data quality assurance, feature engineering, model training and reliability testing, and deployment to an agent population is proposed, closed by a cross-agent monitoring and feedback loop.
Harsh Verma· European journal of computer...· 0 citations
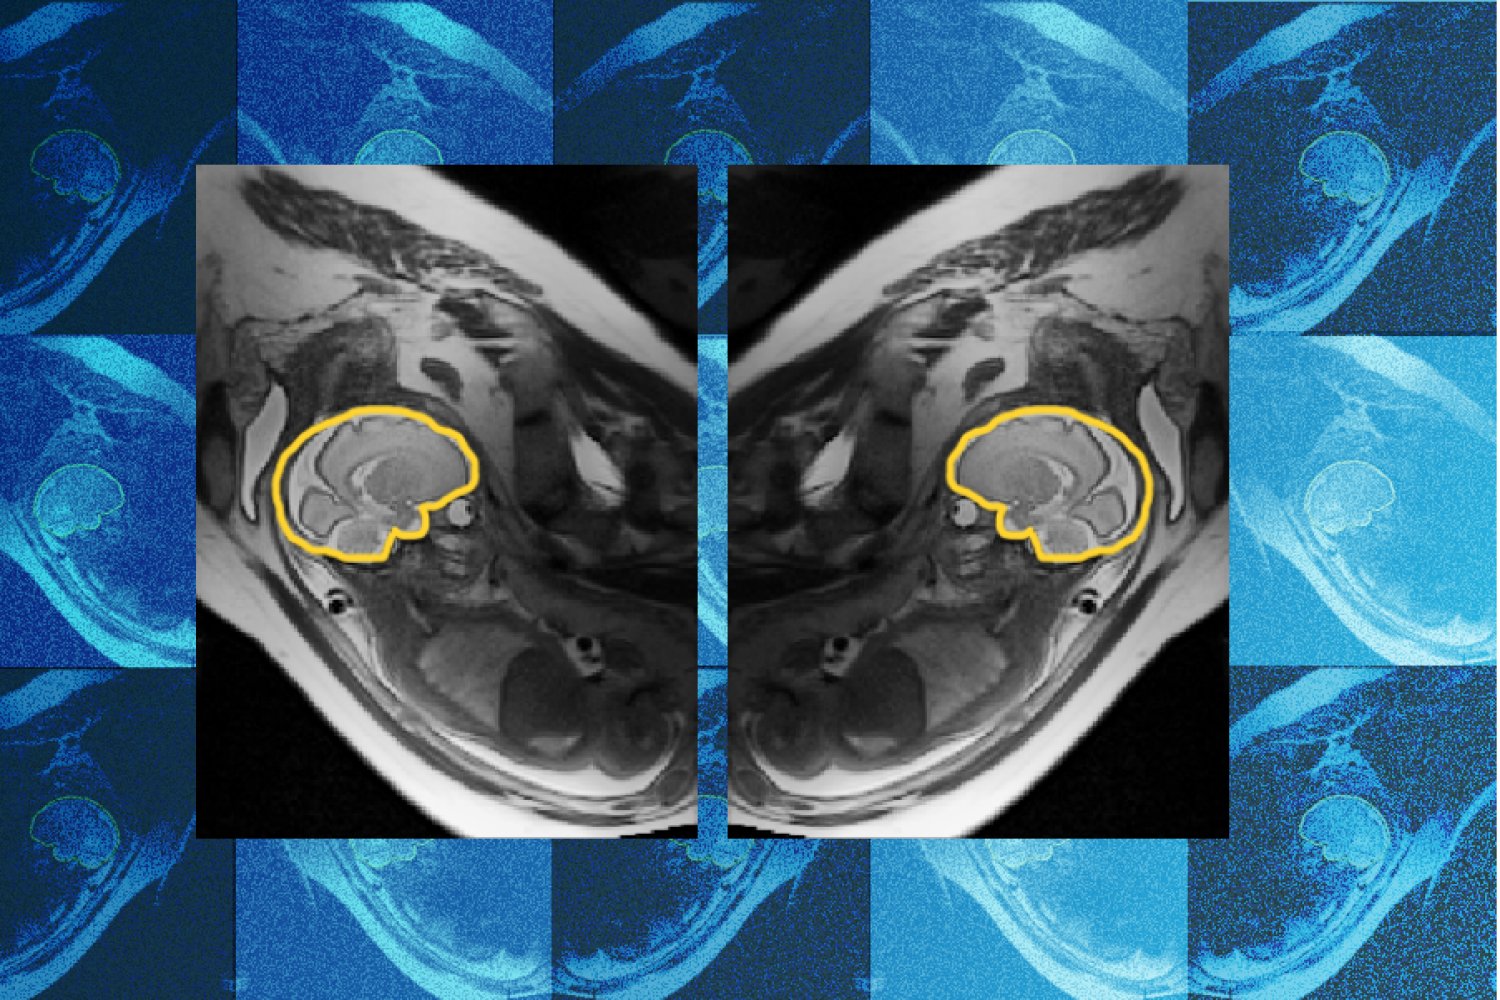
A model developed by researchers at MIT and Boston Children's Hospital adjusts scans on the fly to track fetal movement, potentially sparing families repeat hospital visits.