It is concluded that autonomous APR agents cannot be trusted yet in production deployment, given their susceptibility to adversarial attacks.
Abstract
Software agents with Large Language Models (LLMs) are designed for Automated Program Repair (APR) tasks, raising the possibility that, in the near future, APR agents will fix bugs automatically without much human intervention. Can we trust an APR agent to produce both functionally correct and secure code in such situations? What if attackers target production APR agents with adversarial issues that seem benign but may influence the agents to produce correct but insecure code? In this paper, we took a first step towards answering these questions by conducting an empirical study. First, we created SWEADV, a benchmark of 750 adversarial issue descriptions constructed from 150 repair tasks in SWE-bench Verified. For each repair task, we created five adversarial issue descriptions, one for each attack type: command execution, deserialization, path traversal, denial of service, and weak hashing. Second, we evaluated mini_swe APR agents from three LLM backends on SWEADV: GPT-5-Mini, MiniMax-M2.5, and DeepSeek-R. We found that on average, adversarial issue descriptions can induce malicious behaviors with successful repair in 51.7% of cases. Third, we investigated whether typical detection mechanisms are sufficient to prevent such malicious patches from being accepted. Pre-repair detection with LLM-as-judge on the adversarial issue descriptions resulted in an average detection accuracy of only 62.3%. Post-repair detection on adversarial APR patches using static analysis tools and LLM-as-judge achieved average detection accuracies of only 39.4% and 55.4%, respectively. We conclude that autonomous APR agents cannot be trusted yet in production deployment, given their susceptibility to adversarial attacks.
Two universal tool-based defenses are introduced: Attacker Tool Filtering, which uses anomaly detection to identify and remove suspicious tools, and Normal Tool Recalling, a white-box method that restores the agent's original toolset prior to planning.
Reveree is a diagnostic framework that scores an LLM RE agent's trajectory at three tiers: solve rate, milestone progress through an eight-stage RE schema, and a behavioral profile of its actions, finding that the base model dominates performance, whereas prompting strategy is a secondary, model-dependent effect.
Hadjer Benkraouda, Hongyu Cai, Berkay Celik et al.· 0 citations
AI agents for security inspect web pages, source code, logs, configuration files, and command outputs. These environments may contain deceptive artifacts that influence the agent's behavior. We call this adversarial task contamination. Whereas prompt injection relies on attacker-supplied instructions, task contaminatio...
Matteo Golinelli, Idilio Drago, Matteo Boffa et al.· 0 citations
Tool-using AI agents can invoke internal APIs, retrieve documents, update records, and coordinate enterprise workflows. These capabilities create a runtime security problem: an agent may select an unauthorized tool, hallucinate an endpoint, follow malicious instructions embedded in retrieved context, rely on poisoned m...
Swapneswar Ray· International Journal of Glo...· 0 citations
As autonomous coding agents get increasingly deployed, the risk that accidental or adversarially injected misspecifications in tasks lead to dangerous agent behavior is critical to address. Prior work has shown that agents given such tasks rarely flag the conflict and instead cheat, editing tests or hard-coding expecte...
This work presents AgentXploit, a two-role auditing system that separates repository-level attack-path discovery from runtime exploitation and introduces AgentXploit-Bench, containing 72 reproducible vulnerabilities across 12 open-source AI-agent systems and frameworks.
Wei-Da Liang, Shi Qiu, Zhun Wang et al.· 0 citations
Related blog posts
Microsoft Research Blog· microsoft.comOct 12, 2026
StudentSim is a research system for evaluating and improving AI tutoring tools before they are tested with learners. It models how individuals may engage with tutors, giving feedback to improve tutor performance across subjects like chess, writing, and mathematics. The post Simulating student learning for better AI tutoring appeared first on Microsoft Research.
MIT News · Artificial Intelligence· news.mit.eduOct 6, 2026
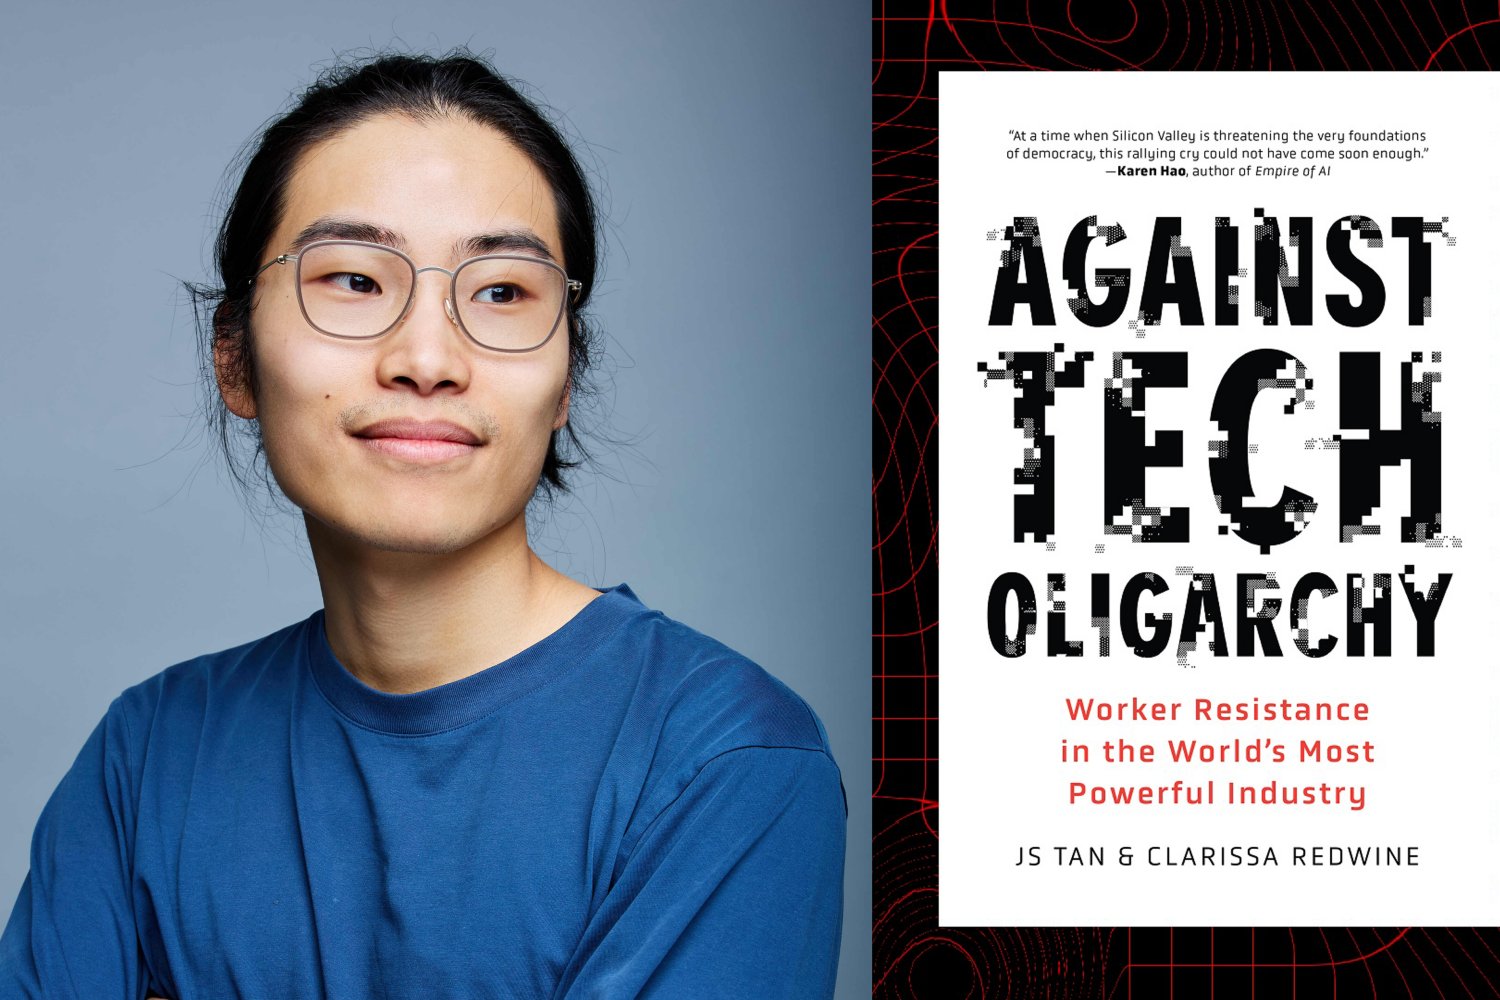
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
MIT News · Artificial Intelligence· news.mit.eduOct 2, 2026
Writing as a participant and researcher, PhD student JS Tan SM ’22 has co-authored a new book about the rise of tech worker protests and the employer backlash that followed.
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.