Many vision applications ask several independent, forced-choice questions about the same image. Visual Jev encodes the image and public context once, executes isolated question suffixes as a batch, and reads candidate probabilities from the backbone's language-model head. Across four benchmarks, answer-supervised post-training raises equal-weight macro accuracy from 70.6% to 76.1%, with the gain concentrated on the two task families represented in training. At N=32 questions per image, shared batched execution is 8.9x faster in warm amortized time than independent serial execution and remains 3.4x faster than an already-batched baseline that recomputes the prefix, at the cost of higher peak memory. A matched typed-head control offers no consistent accuracy advantage over the language-model-head readout. The supported design is therefore simple: adapt the backbone for quality, retain the existing readout, and share execution for efficiency.
Visual software often needs a decision over supplied alternatives rather than a generated explanation. We present PixelJev, a native-image decision interface that maps an image, a task instruction, and a runtime candidate set to a structured choice and candidate-conditioned probabilities using small open multimodal mod...
Xun-Lan Zhou, Xian-Liang Yang, Li Zhao· arXiv.org· 7 citations
KeyRec is a training-free framework for constructing bounded visual memory that preserves fine-grained recent observations in a visual cache and organizes historical evidence into a structured event bank and achieves the best compressed performance in 13 of 15 settings using only 10\% of the dense decoder-facing visual...
Zi-Han Chen, Xuejian Rong, Xiao-Juan Wang et al.· 0 citations
Modality reliance in VLMs is not fixed, but varies across tasks, evidence structures, models, and evaluation settings, which shows that modality reliance in VLMs is not fixed, but varies across tasks, evidence structures, and evaluation settings.
This work compares six off-the-shelf VLMs against a transparent baseline that uses classical SIFT keypoint matching and a signal-quality index over retrieved images, and shows that a learned visual representation is not the bottleneck for this task: given retrieved images, a shape-appropriate classical similarity suffi...
SimpleMemVLA, a VLA without a dedicated memory module that uses the backbone's native video context directly as memory, achieves state-of-the-art results on four memory benchmarks without loss on general-purpose control, and with the same backbone and training setup it outperforms retrieval, compression and recurrent-s...
C. Yin, Wang Xu, Jun-Peng Yang et al.· 4 citations
A training-free, Adaptive Visual Token Pruning (AVTP) framework, applicable to diverse LVLM architectures is proposed, and adaptive pruning ratios in multi-image contexts where images of higher importance retain proportionally more tokens are implemented.
Rongyang Zhang, Cheng-Qiang Lu, Cong Li et al.· 0 citations
Related blog posts
MIT News · Artificial Intelligence· news.mit.eduOct 28, 2026
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
Exploring how generative AI could make machine vision more accessible to businesses. The post GenEye in a Box: Making Machine Vision Something You Can Just Ask For appeared first on GPT-Lab.
Microsoft Research Blog· microsoft.comAug 11, 2026
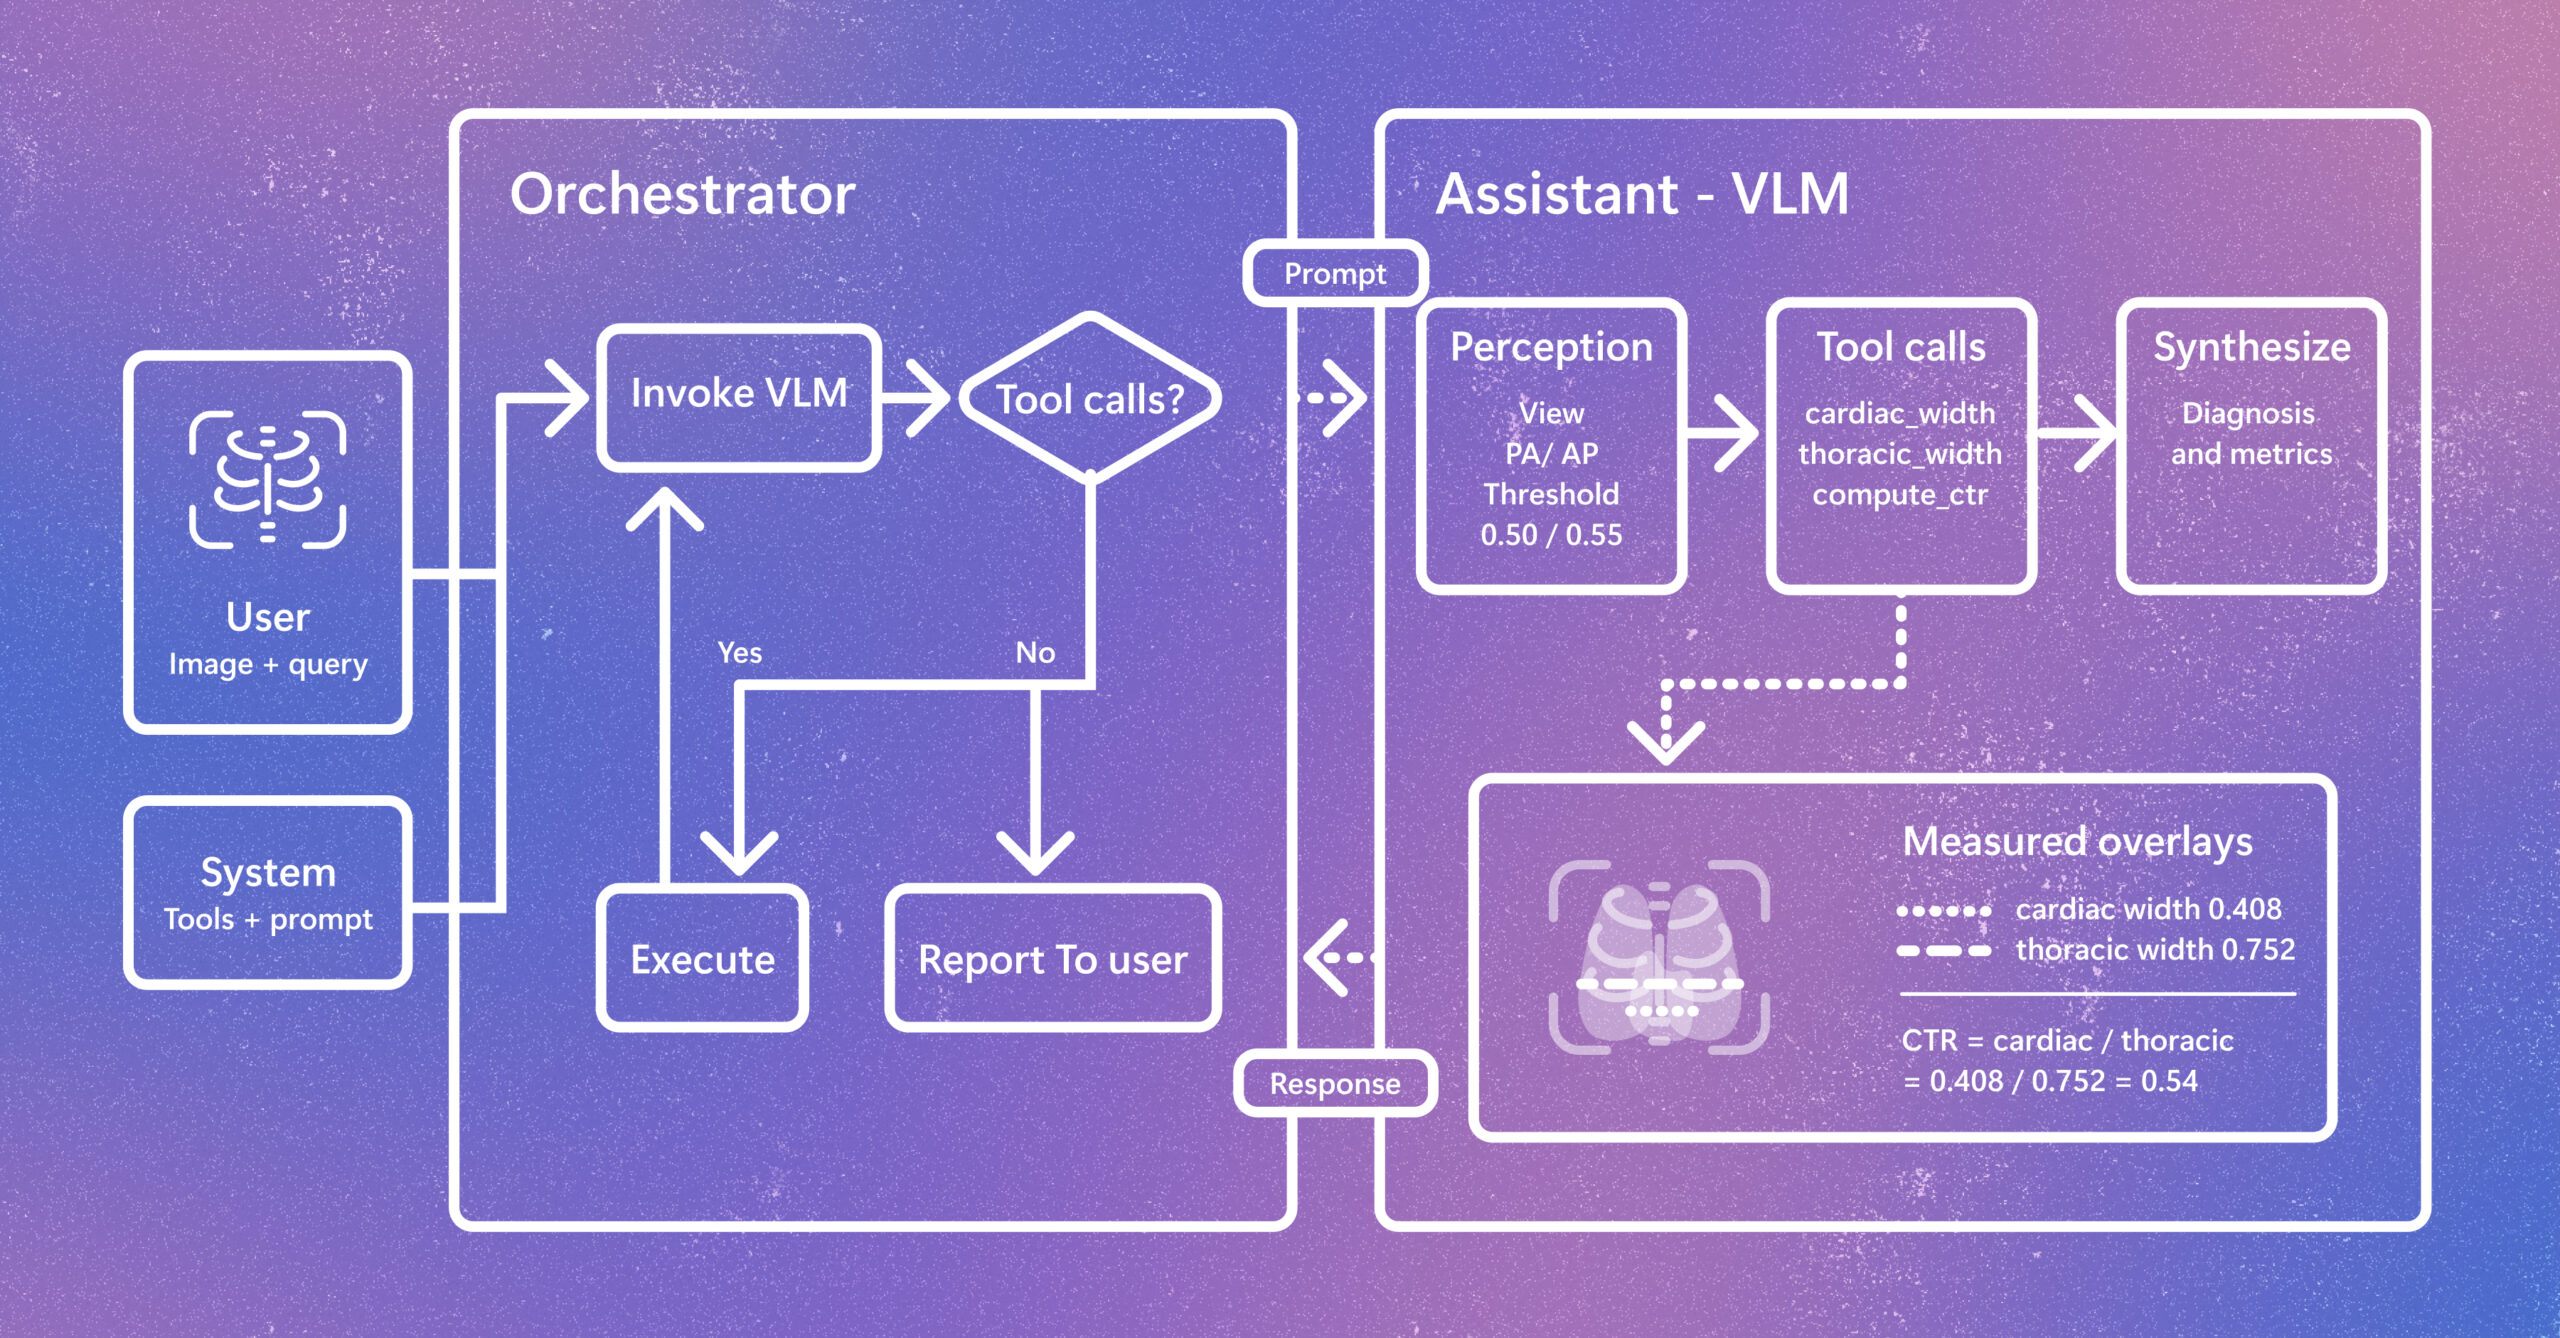
Radiology AI is evolving beyond report generation. CARE-X explores a unified approach that combines flexible reasoning, calibrated predictions, and measurement-based tools for chest X-ray interpretation. The post Introducing CARE-X: Towards Clinically Useful Radiology VLMs with Auxiliary Supervision, Reward-Aligned Learning, and Tool-Augmented Measurement appeared first on Microsoft Research.